<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.9.5">Jekyll</generator><link href="https://chongyu-fan.netlify.app/feed.xml" rel="self" type="application/atom+xml" /><link href="https://chongyu-fan.netlify.app/" rel="alternate" type="text/html" /><updated>2026-09-03T15:51:53-07:00</updated><id>https://chongyu-fan.netlify.app/feed.xml</id><title type="html">Chongyu Fan</title><subtitle>Ph.D student</subtitle><author><name>Chongyu Fan</name><email>chongyu.fan93@gmail.com</email></author><entry><title type="html">UP: Unbounded Positive Asymmetric Optimization for Breaking the Exploration-Stability Dilemma</title><link href="https://chongyu-fan.netlify.app/posts/up/" rel="alternate" type="text/html" title="UP: Unbounded Positive Asymmetric Optimization for Breaking the Exploration-Stability Dilemma" /><published>2026-07-07T00:00:00-07:00</published><updated>2026-07-07T00:00:00-07:00</updated><id>https://chongyu-fan.netlify.app/posts/up</id><content type="html" xml:base="https://chongyu-fan.netlify.app/posts/up/"><![CDATA[<!-- LINK PLACEHOLDER: only the Code link (url "#") is still a placeholder. Replace it with the real code repository once available. The arXiv link and BibTeX (arXiv ID 2607.06987) have been updated to the real values. -->

<style>
.cap-explorer { margin: 26px 0 30px; padding: 20px 22px 16px; background: linear-gradient(180deg, #f8fbff 0%, #ffffff 100%); border: 1px solid #e5e9ef; border-radius: 14px; box-shadow: 0 1px 2px rgba(15, 23, 42, 0.03); }
.cap-explorer .cap-panel { display: grid; grid-template-columns: 230px minmax(0, 1fr); gap: 22px; align-items: start; }
@media (max-width: 760px) { .cap-explorer .cap-panel { grid-template-columns: 1fr; } }
.cap-explorer .cap-controls { display: flex; flex-direction: column; gap: 13px; }
.cap-explorer .cap-seg-row { display: flex; flex-direction: column; gap: 10px; }
.cap-explorer .cap-seg-group { display: flex; flex-direction: column; gap: 5px; transition: opacity 0.15s; }
.cap-explorer .cap-seg-title { font-size: 0.68rem; text-transform: uppercase; letter-spacing: 0.1em; font-weight: 700; color: #94a3b8; }
.cap-explorer .cap-seg { display: inline-flex; border: 1px solid #e5e9ef; border-radius: 8px; overflow: hidden; background: #fff; }
.cap-explorer .cap-seg-btn { flex: 1; appearance: none; border: none; background: transparent; padding: 6px 10px; font: inherit; font-size: 0.82rem; color: #64748b; cursor: pointer; transition: background 0.15s, color 0.15s; border-right: 1px solid #e5e9ef; }
.cap-explorer .cap-seg-btn:last-child { border-right: none; }
.cap-explorer .cap-seg-btn.active { background: #4485C7; color: #fff; font-weight: 600; }
.cap-explorer .cap-slider-row { display: flex; align-items: center; gap: 10px; font-size: 0.9rem; transition: opacity 0.15s; }
.cap-explorer .cap-slider-row.is-dim { opacity: 0.34; }
.cap-explorer .cap-slider-name { min-width: 40px; font-family: 'Latin Modern Math', 'Cambria Math', serif; font-style: italic; color: #0f172a; font-size: 0.98rem; }
.cap-explorer .cap-slider-name sub { font-style: normal; font-size: 0.68em; }
.cap-explorer .cap-slider { flex: 1; -webkit-appearance: none; appearance: none; height: 4px; background: linear-gradient(to right, #e5e9ef, #cfd8e3); border-radius: 999px; outline: none; }
.cap-explorer .cap-slider::-webkit-slider-thumb { -webkit-appearance: none; appearance: none; width: 16px; height: 16px; border-radius: 50%; background: #4485C7; border: 2px solid #fff; box-shadow: 0 1px 4px rgba(68, 133, 199, 0.4); cursor: grab; }
.cap-explorer .cap-slider::-moz-range-thumb { width: 16px; height: 16px; border-radius: 50%; background: #4485C7; border: 2px solid #fff; cursor: grab; }
.cap-explorer .cap-slider-val { min-width: 44px; text-align: right; font-variant-numeric: tabular-nums; font-weight: 600; color: #1f4ca7; font-size: 0.85rem; }
.cap-explorer .cap-plot-wrap { background: #fff; border: 1px solid #e5e9ef; border-radius: 10px; padding: 8px 8px 6px; }
.cap-explorer .cap-canvas { width: 100%; height: auto; display: block; touch-action: none; }
.cap-explorer .cap-hover { margin: 6px 2px 0; padding-top: 11px; border-top: 1px solid #e5e9ef; font-size: 1.04rem; color: #64748b; font-variant-numeric: tabular-nums; min-height: 1.3em; line-height: 1.45; }
.cap-explorer .cap-hover b { color: #1f4ca7; font-weight: 600; font-style: normal; }
.cap-explorer .cap-caption { font-size: 0.86rem; color: #64748b; line-height: 1.55; margin: 12px 4px 2px; font-style: italic; }
.cap-explorer .cap-caption b { color: #1f4ca7; font-style: normal; font-weight: 600; }
</style>

<div class="post-lang post-lang-en">

  <div class="tldr">

    <h2 id="tldr">TL;DR</h2>

    <ul>
      <li>Modern reinforcement learning (RL) for LLM reasoning relies on importance sampling (IS) for sample efficiency, but IS creates an exploration-stability dilemma: pure IS explodes, and the clipping used to tame it strictly caps how much the policy is allowed to move.</li>
      <li>We formalize the <strong>Probability Capacity (Cap)</strong>, the update budget a token has before its gradient is truncated, and show that conservative clipping ties this budget to \(\pi_{\text{old}}\), structurally starving correct but low-confidence reasoning paths.</li>
      <li><strong>Unbounded Positive Asymmetric Optimization (UP)</strong> replaces the IS ratio with a stop-gradient <strong>self-anchored ratio</strong> for positive advantages, recovering a stable, unclipped REINFORCE gradient, while keeping standard clipping for negative advantages as a safeguard.</li>
      <li>UP is a plug-and-play objective that instantiates as <strong>UP-DAPO</strong>, <strong>UP-GRPO</strong>, and <strong>UP-GSPO</strong>, and improves accuracy and exploration across DAPO, GSPO, and GRPO, across dense, MoE, and vision-language models, and across language and multimodal data.</li>
    </ul>

  </div>

  <h2 id="try-it-how-does-clipping-throttle-exploration">Try It: How Does Clipping Throttle Exploration?</h2>

  <p><a href="#fig-1">Figure 1</a> below is an interactive map of the update budget a token receives before its gradient is clipped, drawn over the plane of the current policy probability \(\pi_\theta\) (x axis) and the behavior probability \(\pi_{\text{old}}\) (y axis). Switch <strong>Method</strong> between DAPO and UP-DAPO for positive advantages (\(\hat{A} &gt; 0\)), inspect the shared non-positive regime (\(\hat{A} \le 0\)), drag \(\epsilon_{\text{high}}\), \(\epsilon_{\text{low}}\), and \(c\), and hover anywhere to read the exact capacity. The key contrast: DAPO ties the budget to \(\pi_{\text{old}}\) through a thin band, while UP-DAPO frees it to the full \(1 - \pi_\theta\), independent of \(\pi_{\text{old}}\).</p>

  <div id="fig-1" class="cap-explorer" data-lang="en">
  <div class="cap-panel">
    <div class="cap-controls">
      <div class="cap-seg-row">
        <div class="cap-seg-group" data-group="method">
          <span class="cap-seg-title">Method</span>
          <div class="cap-seg" data-seg="method">
            <button type="button" class="cap-seg-btn active" data-val="dapo">DAPO</button>
            <button type="button" class="cap-seg-btn" data-val="up">UP-DAPO</button>
          </div>
        </div>
        <div class="cap-seg-group" data-group="sign">
          <span class="cap-seg-title">Advantage</span>
          <div class="cap-seg" data-seg="sign">
            <button type="button" class="cap-seg-btn active" data-val="pos">A &gt; 0</button>
            <button type="button" class="cap-seg-btn" data-val="neg">A &le; 0</button>
          </div>
        </div>
      </div>
      <div class="cap-slider-row" data-param-row="ehigh">
        <span class="cap-slider-name">&epsilon;<sub>high</sub></span>
        <input type="range" class="cap-slider" data-param="ehigh" min="0" max="1" step="0.01" value="0.28" />
        <span class="cap-slider-val" data-val="ehigh">0.28</span>
      </div>
      <div class="cap-slider-row" data-param-row="elow">
        <span class="cap-slider-name">&epsilon;<sub>low</sub></span>
        <input type="range" class="cap-slider" data-param="elow" min="0" max="0.9" step="0.01" value="0.2" />
        <span class="cap-slider-val" data-val="elow">0.20</span>
      </div>
      <div class="cap-slider-row" data-param-row="c">
        <span class="cap-slider-name">c</span>
        <input type="range" class="cap-slider" data-param="c" min="1" max="5" step="0.1" value="3" />
        <span class="cap-slider-val" data-val="c">3.0</span>
      </div>
      <p class="cap-hover" data-out="hover">Hover over the map to read Cap at any (&pi;<sub>&theta;</sub>, &pi;<sub>old</sub>).</p>
    </div>
    <div class="cap-plot-wrap">
      <canvas class="cap-canvas" width="760" height="700" role="img" aria-label="Probability Capacity heatmap over the (pi_theta, pi_old) plane"></canvas>
    </div>
  </div>
  <p class="cap-caption" data-out="caption"></p>
</div>
  <p class="fig-caption">Figure 1. Interactive Probability Capacity map (this paper's Figure 1). The color encodes the update budget Cap over the plane of the current policy probability &pi;<sub>&theta;</sub> (x axis) and the behavior probability &pi;<sub>old</sub> (y axis). For positive advantages, DAPO confines Cap to a thin band bounded by &pi;<sub>&theta;</sub> = (1 + &epsilon;<sub>high</sub>)&pi;<sub>old</sub>, while UP-DAPO frees it to the full 1 &minus; &pi;<sub>&theta;</sub> independent of &pi;<sub>old</sub>; for non-positive advantages both methods share the clipped wedge.</p>

  <h2 id="background">Background</h2>

  <h3 id="from-reinforce-to-grpo-dapo-and-gspo">From REINFORCE to GRPO, DAPO, and GSPO</h3>

  <p>RL has become the standard paradigm for eliciting complex reasoning from LLMs. The vanilla REINFORCE objective is strictly on-policy and yields a mathematically stable gradient:</p>

\[\nabla_\theta J_{\text{REINFORCE}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_\theta}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>REINFORCE is stable but sample inefficient, since each trajectory is discarded after a single step. To reuse sampled data across multiple steps, GRPO and DAPO introduce <strong>importance sampling (IS)</strong>, estimating the current policy \(\pi_\theta\) from samples drawn by a historical policy \(\pi_{\text{old}}\) through the ratio</p>

\[r_{i,t}(\theta) = \frac{\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})}{\pi_{\text{old}}(o_{i,t} \mid q, o_{i,&lt;t})}.\]

  <p>To stop this ratio from exploding, GRPO bounds it inside a trust region \([1 - \epsilon, 1 + \epsilon]\) via clipping. DAPO decouples the bounds into \((\epsilon_{\text{low}}, \epsilon_{\text{high}})\) and drops the KL penalty, so it relies exclusively on clipping to trade off stability against exploration. GSPO instead moves to a <strong>sequence-level</strong> ratio, using the length-normalized likelihood of the whole response:</p>

\[s_i(\theta) = \left( \frac{\pi_\theta(o_i \mid q)}{\pi_{\text{old}}(o_i \mid q)} \right)^{\frac{1}{|o_i|}} = \exp\!\left( \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \big( \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) - \log \pi_{\text{old}}(o_{i,t} \mid q, o_{i,&lt;t}) \big) \right).\]

  <p>Every one of these methods keeps \(\pi_{\text{old}}\) in the denominator, and every one leans on clipping. That shared structure is exactly what creates the dilemma below.</p>

  <h3 id="probability-capacity-cap">Probability Capacity (Cap)</h3>

  <p>To make the cost of clipping precise, we define the <strong>Probability Capacity (Cap)</strong> as the maximum allowable increase in \(\pi_\theta\) for a token with positive advantage (\(\hat{A} &gt; 0\)), or the maximum allowable decrease for a token with non-positive advantage (\(\hat{A} \le 0\)), before the optimization gradient is truncated. Cap is the effective <strong>budget</strong> a token has for policy exploration relative to \(\pi_{\text{old}}\). <a href="#fig-1">Figure 1</a> plots this budget directly, and the rest of this post is a story about how UP enlarges it.</p>

  <h2 id="motivation">Motivation</h2>

  <p>IS-based RL is caught between two failure modes. Pushing updates too aggressively (pure IS) triggers instability; constraining them too conservatively (clipping) stifles exploration. We examine each in turn.</p>

  <h3 id="dilemma-1-importance-sampling-induces-instability">Dilemma 1: Importance Sampling Induces Instability</h3>

  <p>The unclipped IS objective maximizes the advantage weighted by the ratio, \(J_{\text{IS}}(\theta) = \mathbb{E}[\hat{A}\, r_{i,t}(\theta)]\), whose gradient is</p>

\[\nabla_\theta J_{\text{IS}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \hat{A}\, r_{i,t}(\theta)\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>Comparing this to the REINFORCE gradient, the flaw is explicit: the IS gradient is scaled by \(r_{i,t}(\theta)\). For a rare, high-reward reasoning path where the behavior probability \(\pi_{\text{old}}\) is infinitesimally small, this ratio explodes as the active policy marginally improves. The pathological scaling destroys stable representations and drives training to diverge, which is precisely why clipping is treated as indispensable.</p>

  <h3 id="dilemma-2-clipping-stifles-exploration">Dilemma 2: Clipping Stifles Exploration</h3>

  <p>For positive advantages, the clipped objective is \(J_{\text{IS+CLIP}}(\theta) = \min\!\big[r_{i,t}(\theta), 1 + \epsilon\big]\hat{A}\), and its gradient vanishes the moment the ratio exceeds the trust-region boundary. Mapping this to absolute probability space, the policy is upper-bounded by \(\pi_\theta \le (1 + \epsilon_{\text{high}})\pi_{\text{old}}\), so the remaining budget follows a piecewise Cap:</p>

\[\mathrm{Cap}(\pi_\theta, \pi_{\text{old}}) =
\begin{cases}
\min\!\big(1,\, (1 + \epsilon_{\text{high}})\pi_{\text{old}}\big) - \pi_\theta &amp; \text{if } \pi_\theta &lt; (1 + \epsilon_{\text{high}})\pi_{\text{old}}, \\[4pt]
0 &amp; \text{if } \pi_\theta \ge (1 + \epsilon_{\text{high}})\pi_{\text{old}}.
\end{cases}\]

  <p>This exposes a structural bottleneck: the budget is <strong>linearly dependent on \(\pi_{\text{old}}\)</strong>. For a low-likelihood reasoning token with \(\pi_{\text{old}} = 0.01\), a standard \(\epsilon_{\text{high}} = 0.28\) caps the absolute probability increase at a mere \(0.0028\). Once \(\pi_\theta\) reaches \(0.0128\), the capacity drops to zero, the token enters the Upper Clip region, and its gradient is nullified even when the advantage is exceptionally high. Set the method to DAPO in <a href="#fig-1">Figure 1</a> and read along the bottom of the map, where \(\pi_{\text{old}}\) is small, to see this sliver of budget for yourself. Structurally, this stifles exploration and leaves promising long-tail trajectories undiscovered.</p>

  <div class="callout">
    <p><strong>The question.</strong> How can we maximize a model’s exploration while preventing training instability in RL? Aggressive updates destabilize training; conservative clipping starves exploration. We need a formulation that escapes both.</p>
  </div>

  <h2 id="method">Method</h2>

  <p>UP dismantles the dilemma with two mathematical moves: replace \(\pi_{\text{old}}\) with the current policy \(\pi_\theta\) via a stop-gradient, and route the gradient asymmetrically by the sign of the advantage.</p>

  <h3 id="an-unbounded-objective-for-positive-advantages">An Unbounded Objective for Positive Advantages</h3>

  <p>For correct rollouts (\(\hat{A} &gt; 0\)), we replace the IS ratio with a <strong>self-anchored ratio</strong> \(\tilde{r}_{i,t}(\theta)\) built from the stop-gradient operator \(\mathrm{sg}(\cdot)\) (Eq. 12):</p>

\[J^{+}_{\text{UP}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \frac{\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})}{\mathrm{sg}\!\big(\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})\big)} \right], \qquad \hat{A} &gt; 0.\]

  <p>During backpropagation \(\mathrm{sg}(\pi_\theta)\) is a constant scalar, yet its forward value equals \(\pi_\theta\). Applying the log-derivative trick \(\nabla x / x = \nabla \log x\) collapses the objective to (Eq. 13):</p>

\[\nabla_\theta J^{+}_{\text{UP}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>This is a profound simplification: optimizing the self-anchored ratio is mathematically equivalent to maximizing the <strong>REINFORCE</strong> objective. By anchoring the policy to \(\pi_\theta\) instead of \(\pi_{\text{old}}\), UP eradicates the root cause of IS instability from Dilemma 1, and its Cap becomes fully unconstrained by history, \(\mathrm{Cap} = 1 - \pi_\theta\). Switch the method to UP-DAPO with \(\hat{A} &gt; 0\) in <a href="#fig-1">Figure 1</a>: the thin clipped band expands into a full budget that depends only on \(\pi_\theta\).</p>

  <h3 id="why-asymmetric-keep-clipping-for-negative-advantages">Why Asymmetric: Keep Clipping for Negative Advantages</h3>

  <p>The unbounded mechanism is deliberately restricted to correct rollouts. For wrong rollouts the advantage is negative, which flips the gradient direction; applying an unbounded update there performs aggressive gradient ascent and destroys the original representation. UP therefore retains standard clipping for \(\hat{A} \le 0\), where DAPO and UP-DAPO share an identical Cap governed by the lower-clip and dual-clip boundaries (see the \(\hat{A} \le 0\) view in <a href="#fig-1">Figure 1</a>):</p>

\[\mathrm{Cap}(\pi_\theta, \pi_{\text{old}}) =
\begin{cases}
\pi_\theta - (1 - \epsilon_{\text{low}})\pi_{\text{old}} &amp; \text{if } (1 - \epsilon_{\text{low}})\pi_{\text{old}} \le \pi_\theta \le c\,\pi_{\text{old}}, \\[4pt]
0 &amp; \text{if } \pi_\theta &lt; (1 - \epsilon_{\text{low}})\pi_{\text{old}} \quad (\text{Lower Clip}), \\[4pt]
0 &amp; \text{if } \pi_\theta &gt; c\,\pi_{\text{old}} \quad (\text{Dual Clip}).
\end{cases}\]

  <p>This is the crux of UP: exploration for correct rollouts, safety for wrong ones.</p>

  <h3 id="up-gxpo-one-plugin-three-instantiations">UP-GxPO: One Plugin, Three Instantiations</h3>

  <p>Because it only rewrites the positive branch, UP plugs into any group-based policy optimizer. The token-level <strong>UP-DAPO</strong> combines the unbounded positive objective with the DAPO clipped objective for negatives (Eq. 14):</p>

\[J_{\text{UP-DAPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{\sum_i |o_i|} \sum_{i}\sum_{t}
\begin{cases}
\hat{A}_{i,t}\, \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) &amp; \text{if } \hat{A}_{i,t} &gt; 0, \\[4pt]
\min\!\big( r_{i,t}(\theta)\hat{A}_{i,t},\, \mathrm{clip}(r_{i,t}(\theta), 1 - \epsilon_{\text{low}}, 1 + \epsilon_{\text{high}})\hat{A}_{i,t} \big) &amp; \text{if } \hat{A}_{i,t} \le 0.
\end{cases}
\right].\]

  <p>The same principle gives <strong>UP-GRPO</strong>, which keeps GRPO’s symmetric clipping and KL penalty on the negative branch (Eq. 15):</p>

\[J_{\text{UP-GRPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{G} \sum_{i} \frac{1}{|o_i|} \sum_{t}
\begin{cases}
\hat{A}_i\, \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) - \beta D_{\text{KL}}(\pi_\theta \,\|\, \pi_{\text{ref}}) &amp; \text{if } \hat{A}_i &gt; 0, \\[4pt]
\min\!\big( r_{i,t}(\theta)\hat{A}_i,\, \mathrm{clip}(r_{i,t}(\theta), 1 - \epsilon, 1 + \epsilon)\hat{A}_i \big) - \beta D_{\text{KL}}(\pi_\theta \,\|\, \pi_{\text{ref}}) &amp; \text{if } \hat{A}_i \le 0.
\end{cases}
\right].\]

  <p>Finally, UP extends to the sequence level as <strong>UP-GSPO</strong>, whose positive branch provably reduces to a length-normalized REINFORCE gradient (Eq. 16):</p>

\[J_{\text{UP-GSPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{G} \sum_{i}
\begin{cases}
\hat{A}_i \left( \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right) &amp; \text{if } \hat{A}_i &gt; 0, \\[4pt]
\min\!\big( s_i(\theta)\hat{A}_i,\, \mathrm{clip}(s_i(\theta), 1 - \epsilon, 1 + \epsilon)\hat{A}_i \big) &amp; \text{if } \hat{A}_i \le 0.
\end{cases}
\right].\]

  <div class="callout">
    <p><strong>Takeaway.</strong> UP is a drop-in objective. It swaps the positive branch of any GxPO algorithm for a stop-gradient, unclipped, REINFORCE-equivalent update, and leaves the negative branch untouched as a safeguard.</p>
  </div>

  <h2 id="experiments">Experiments</h2>

  <p>We evaluate UP on dense LLMs (Qwen3-14B-Base, Qwen3-8B), an MoE model (Qwen3-30B-A3B-Base), and a vision-language model (Qwen3-VL-8B-Instruct), using the verl framework. Across every setting UP raises accuracy and exploration while keeping training stable.</p>

  <h3 id="performance-exploration-and-stability-analysis-of-up-dapo">Performance, Exploration, and Stability Analysis of UP-DAPO</h3>

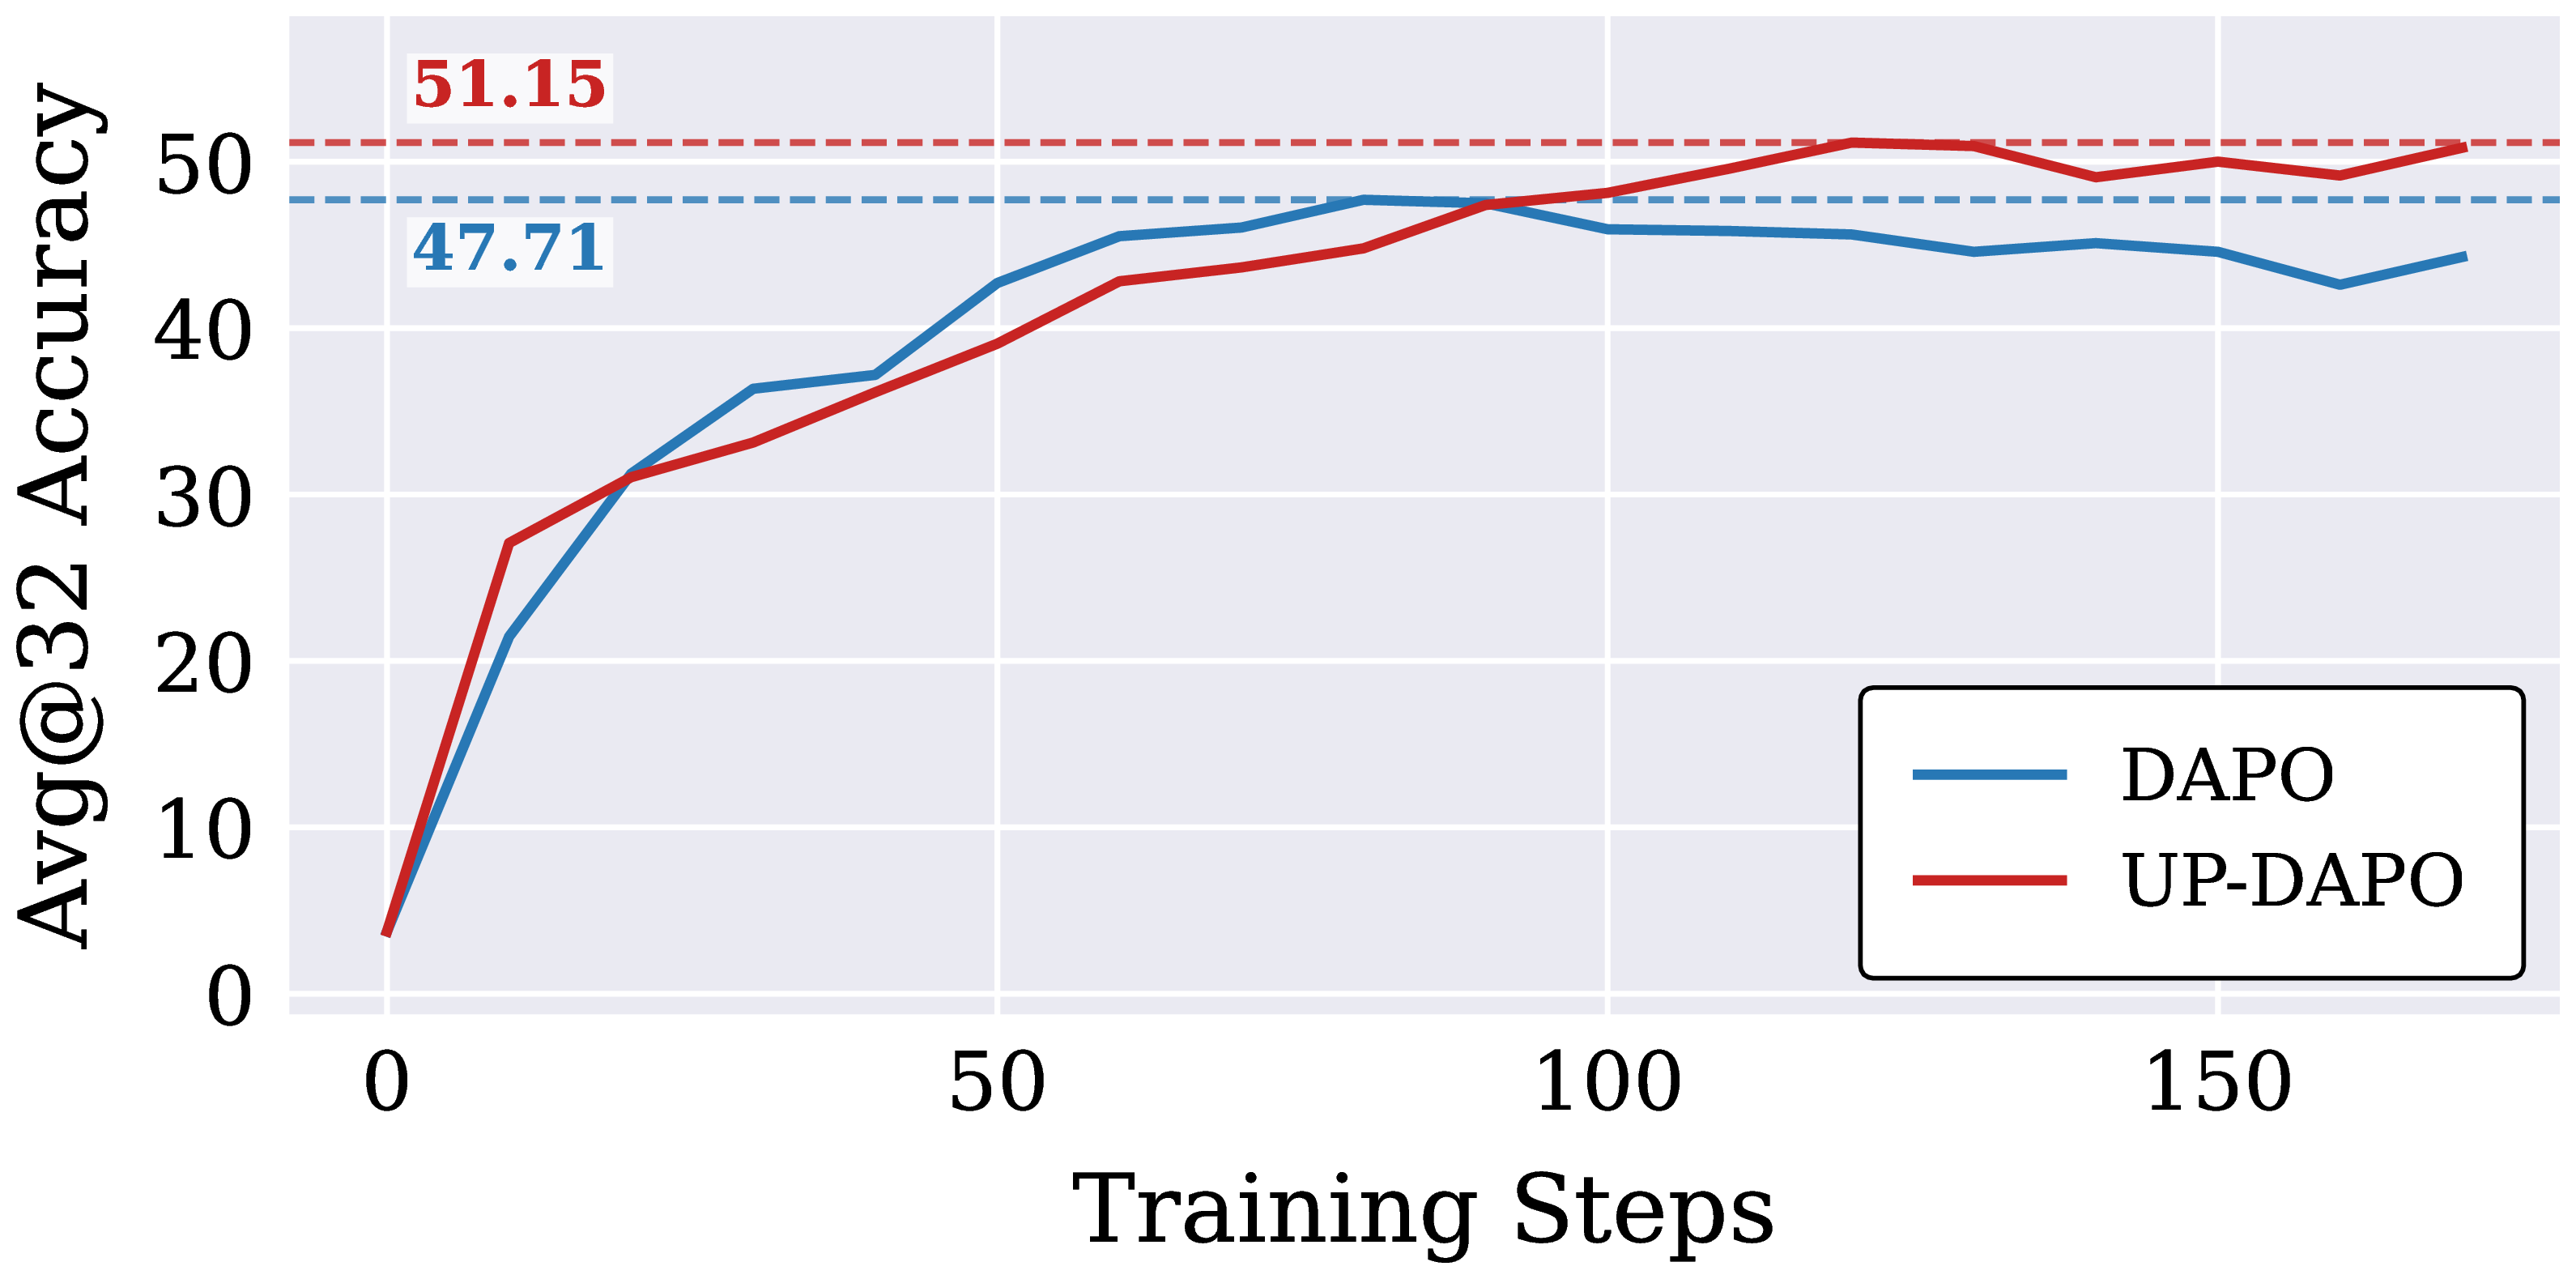
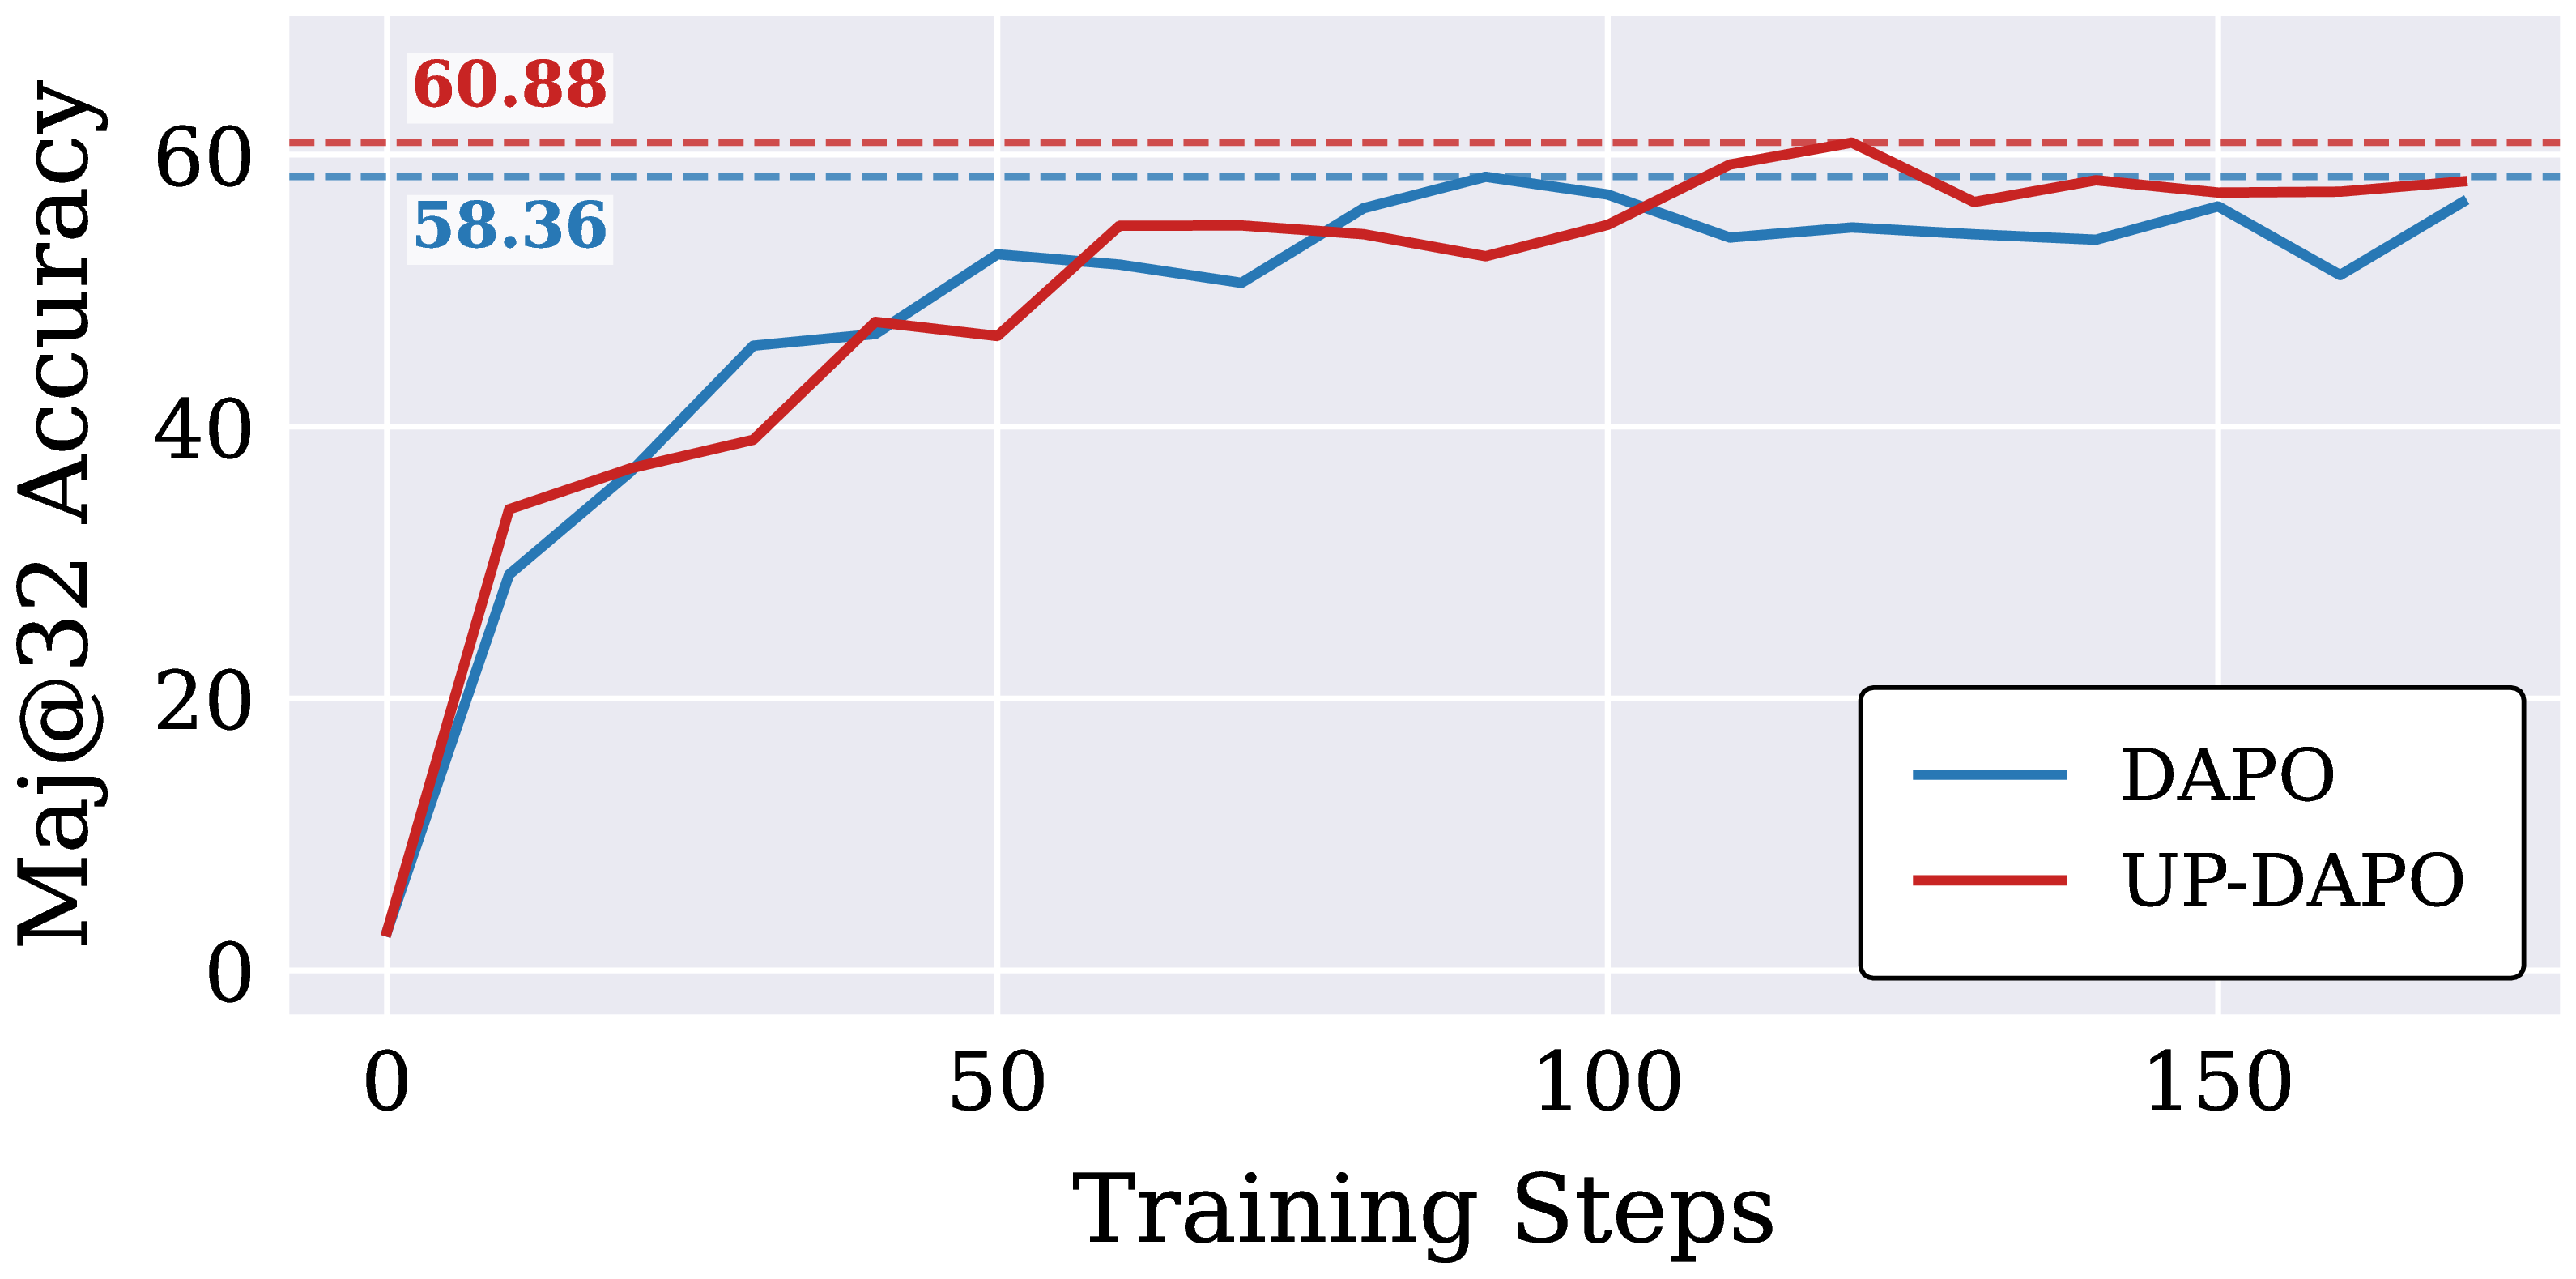
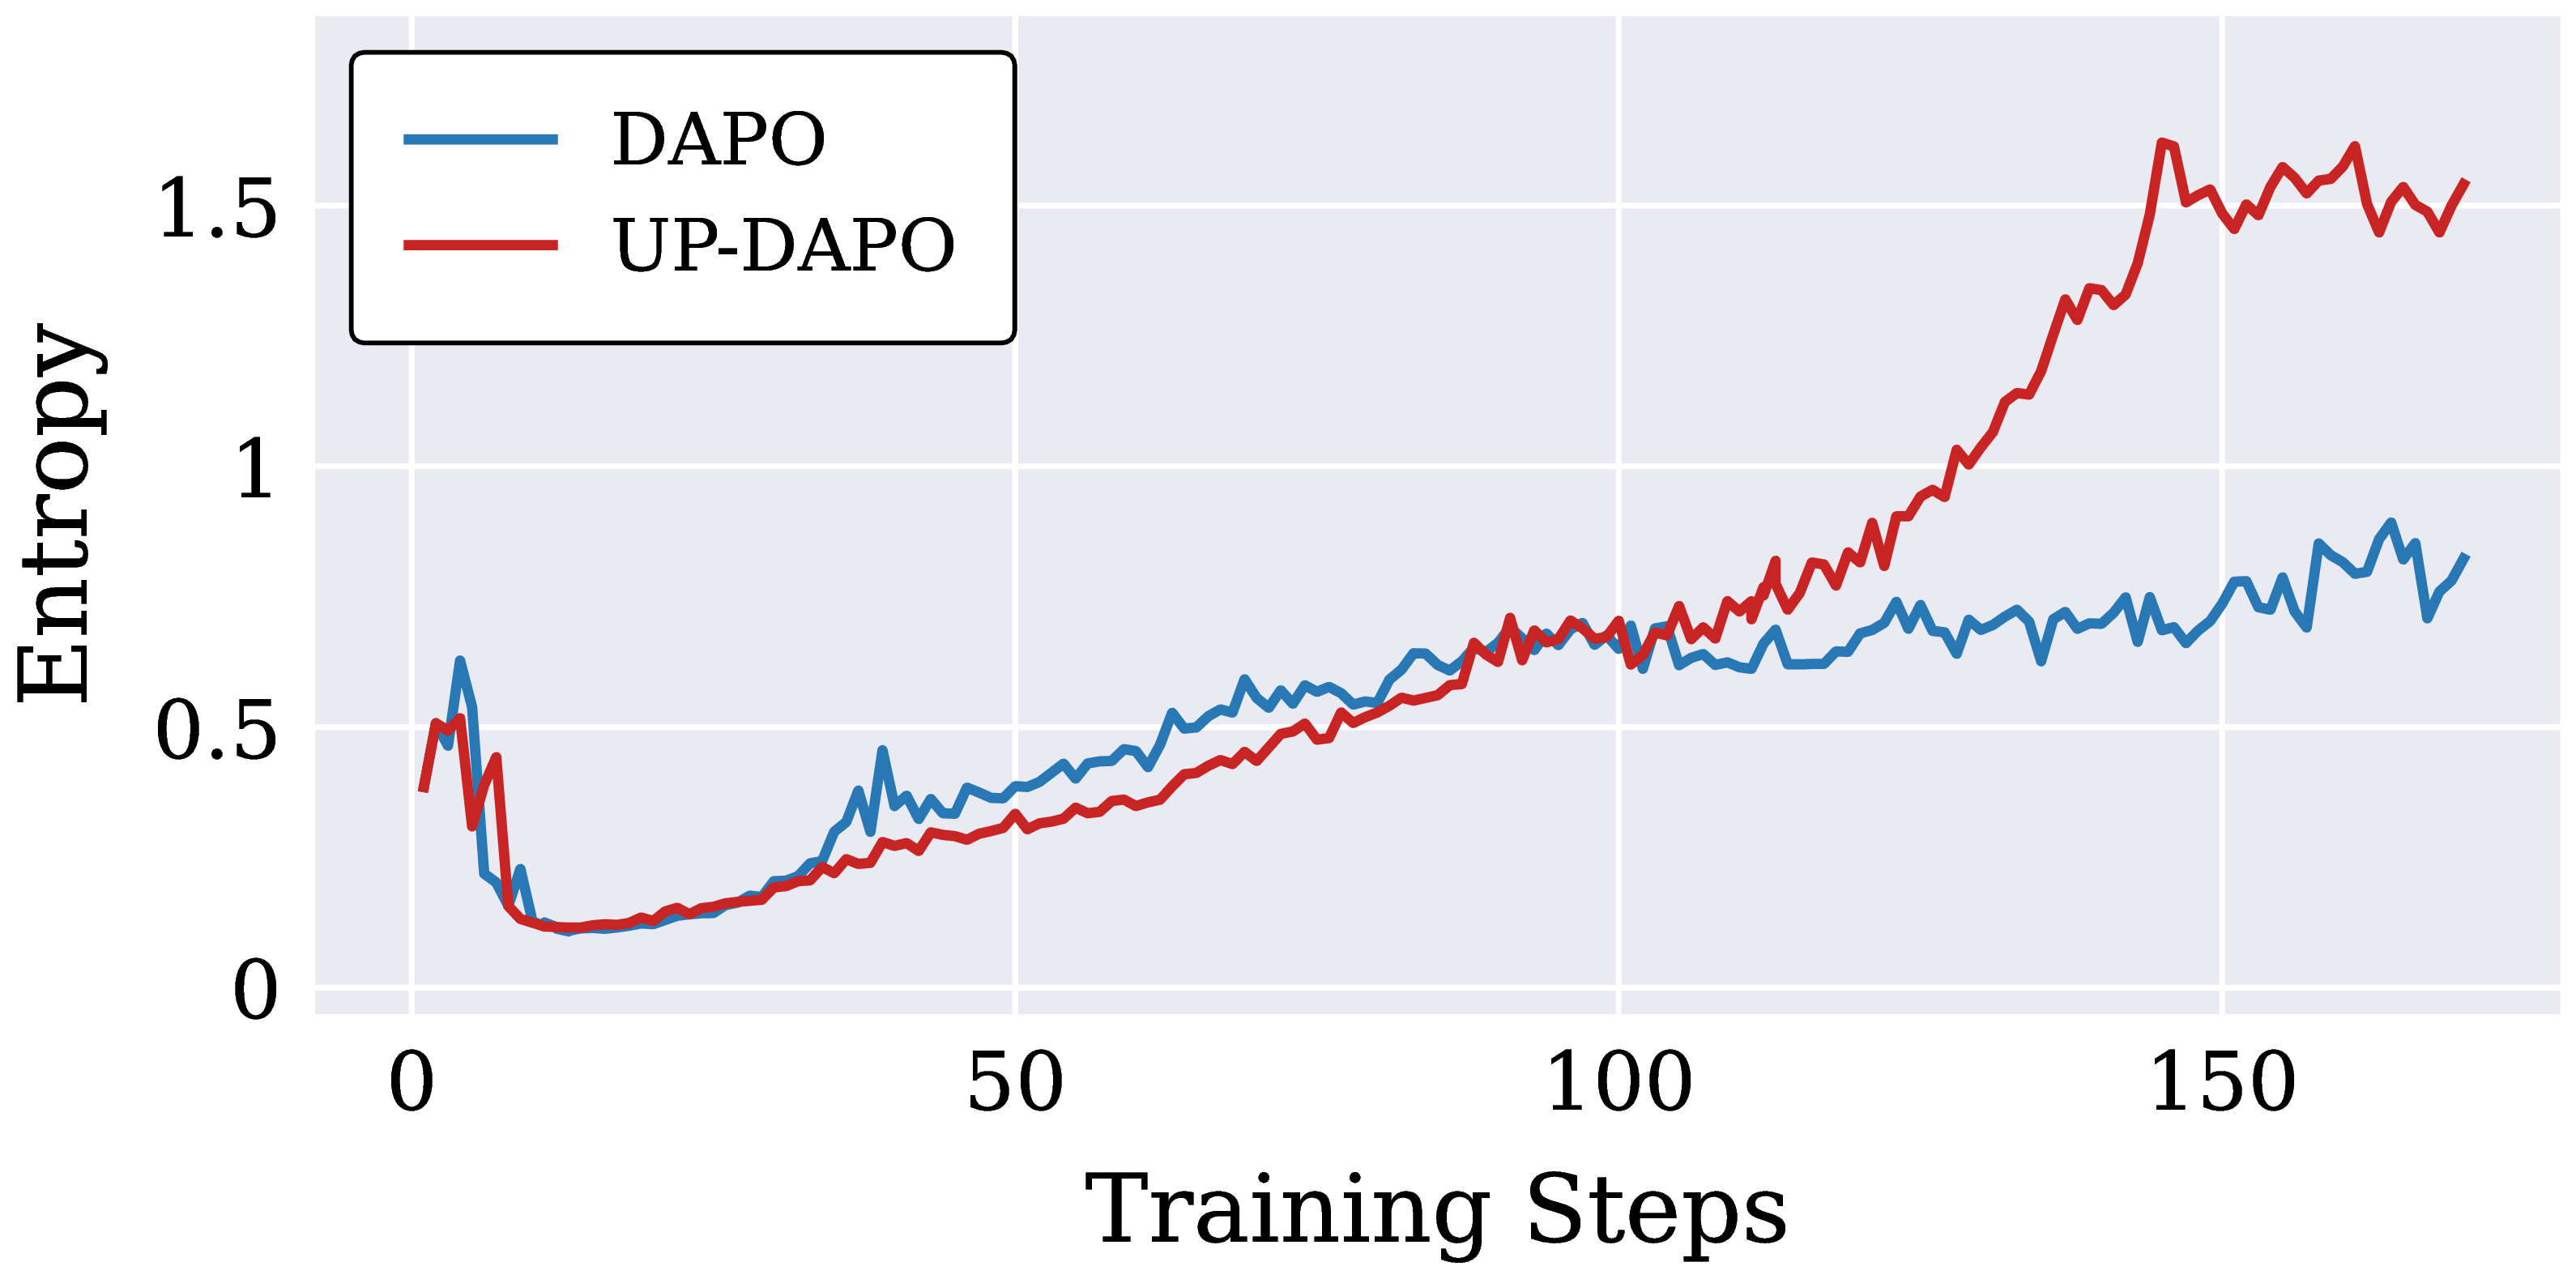
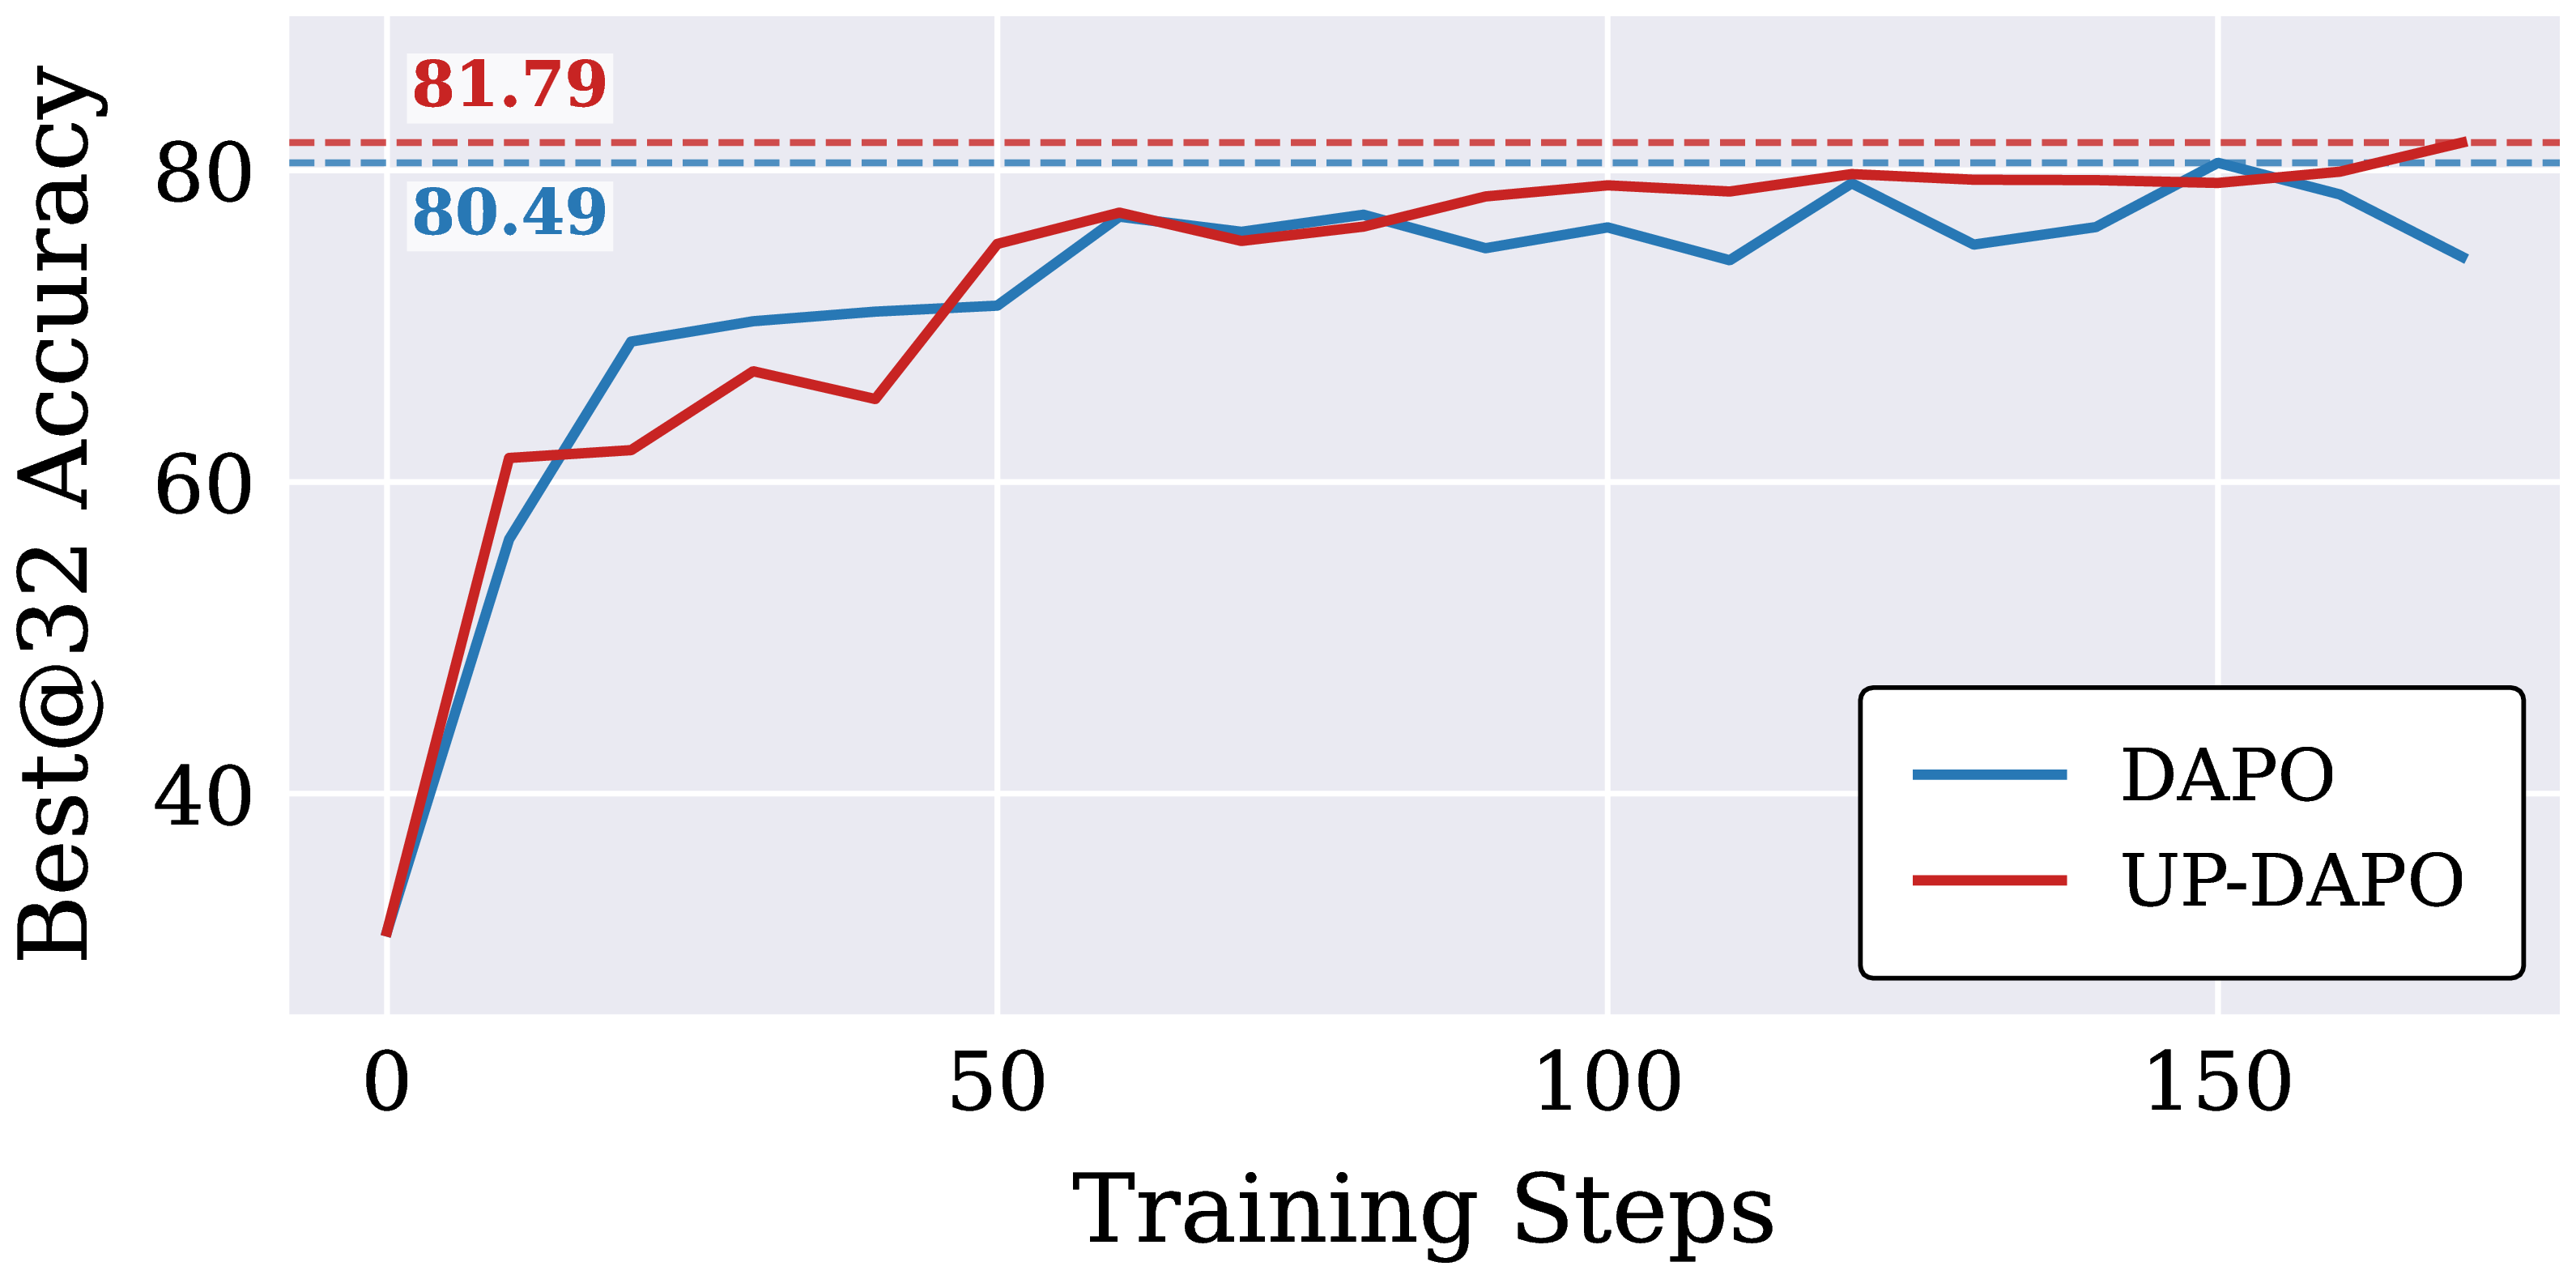
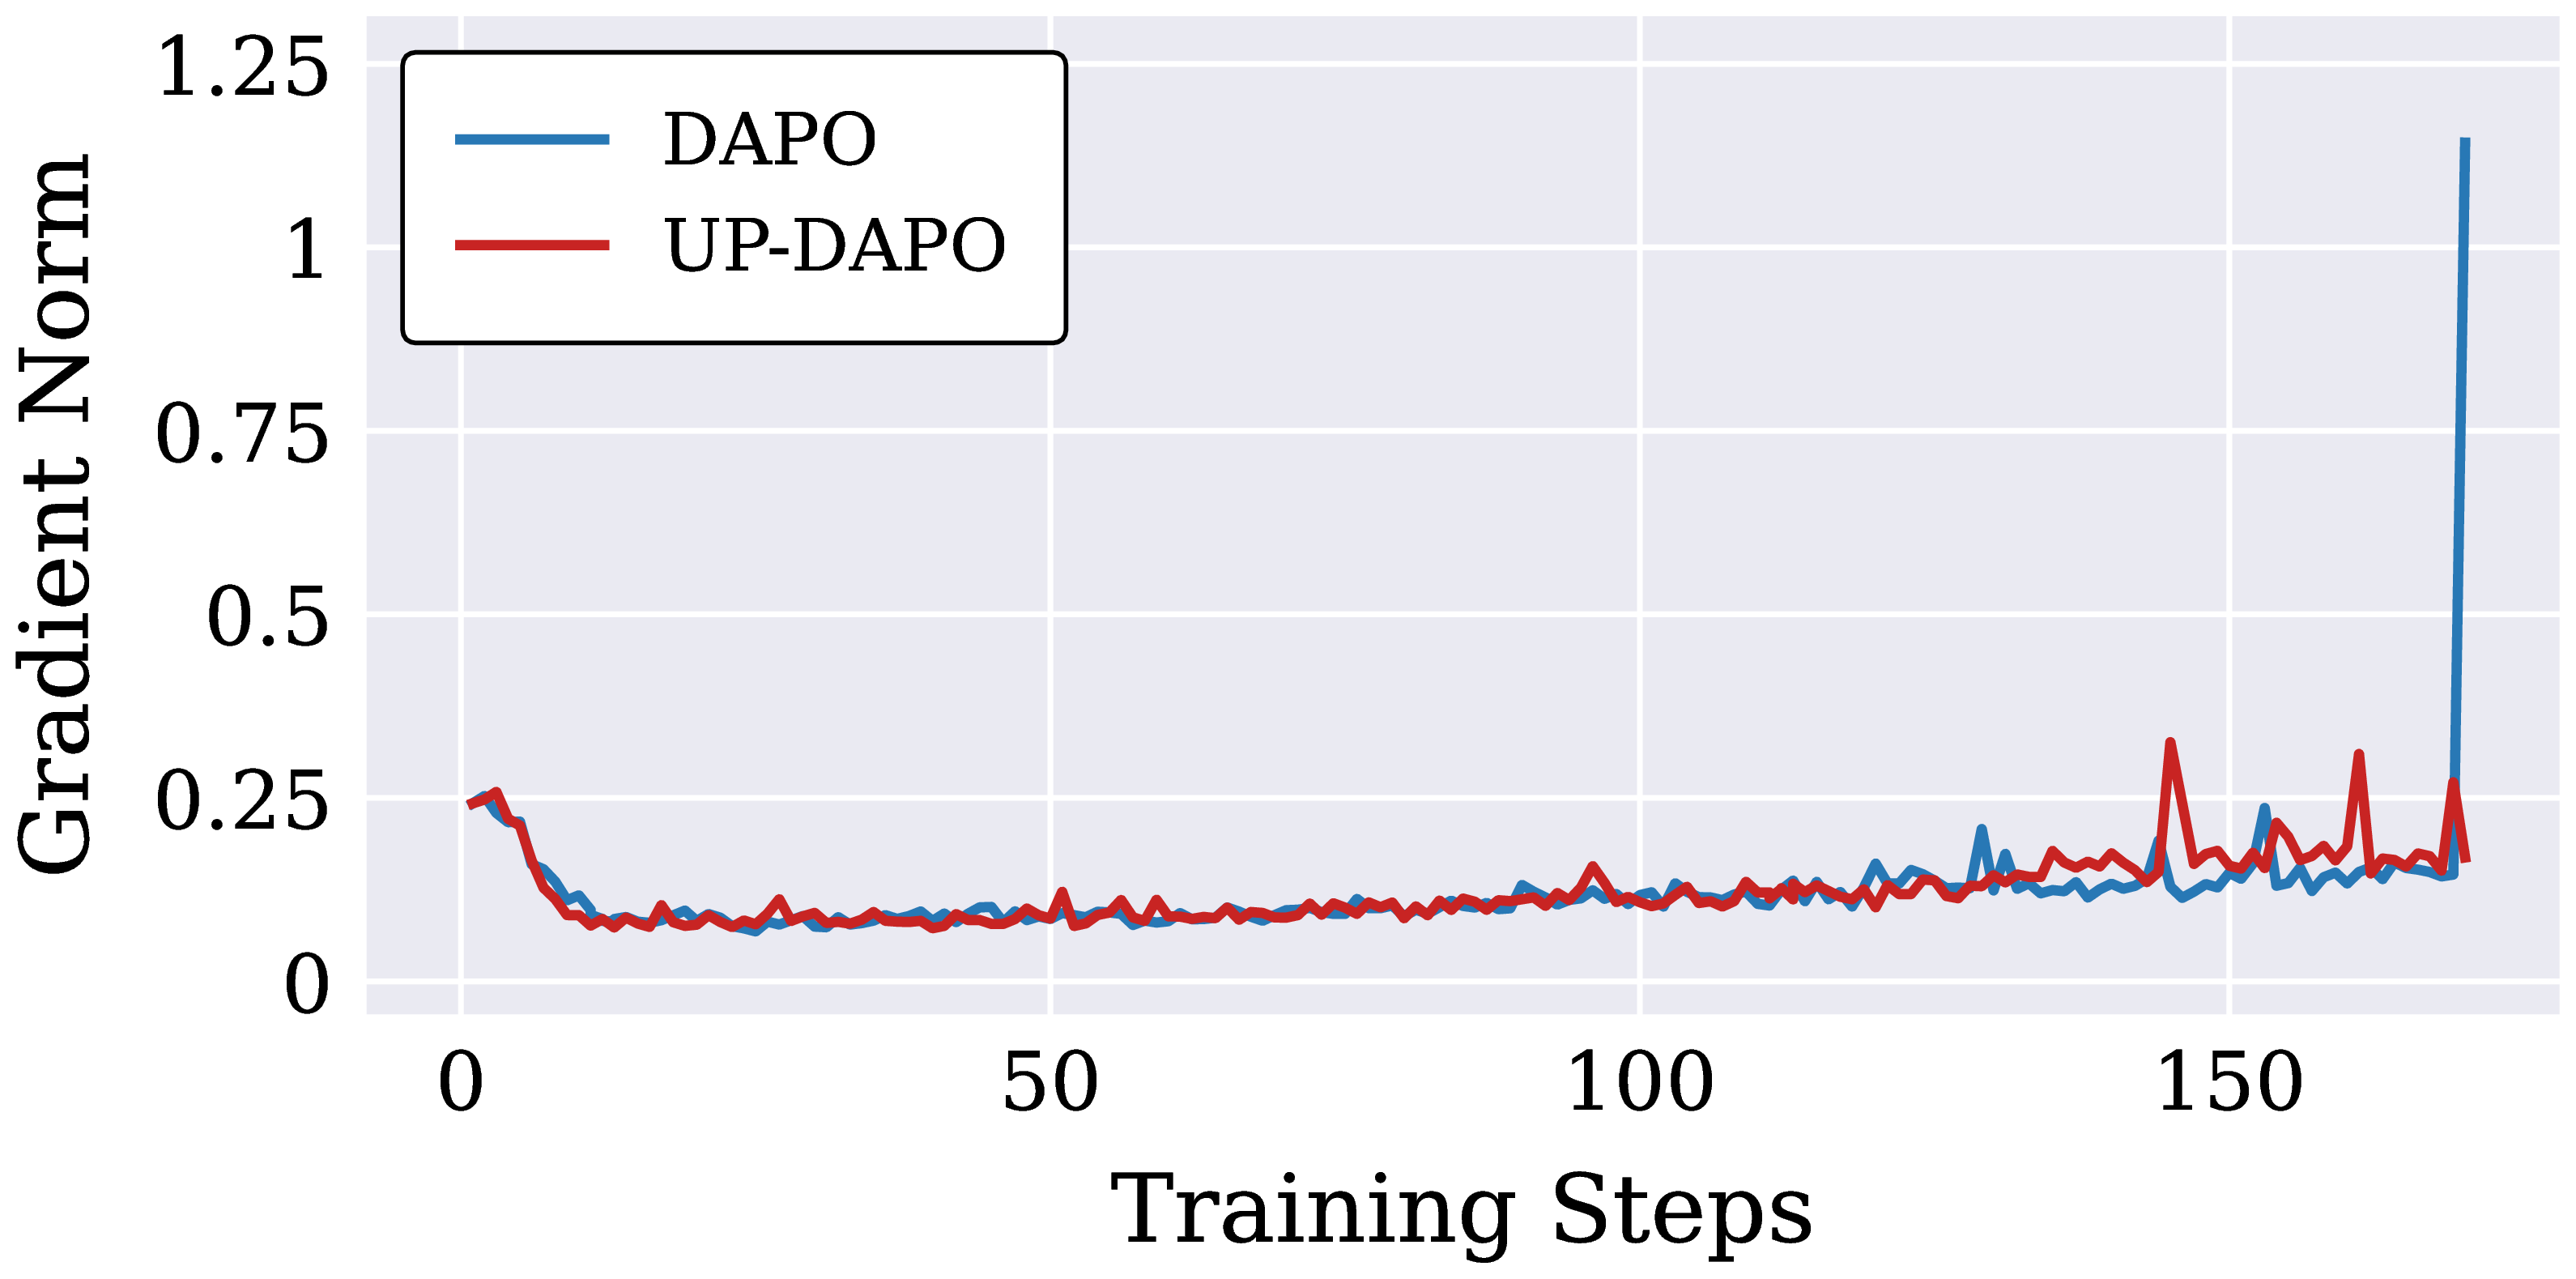
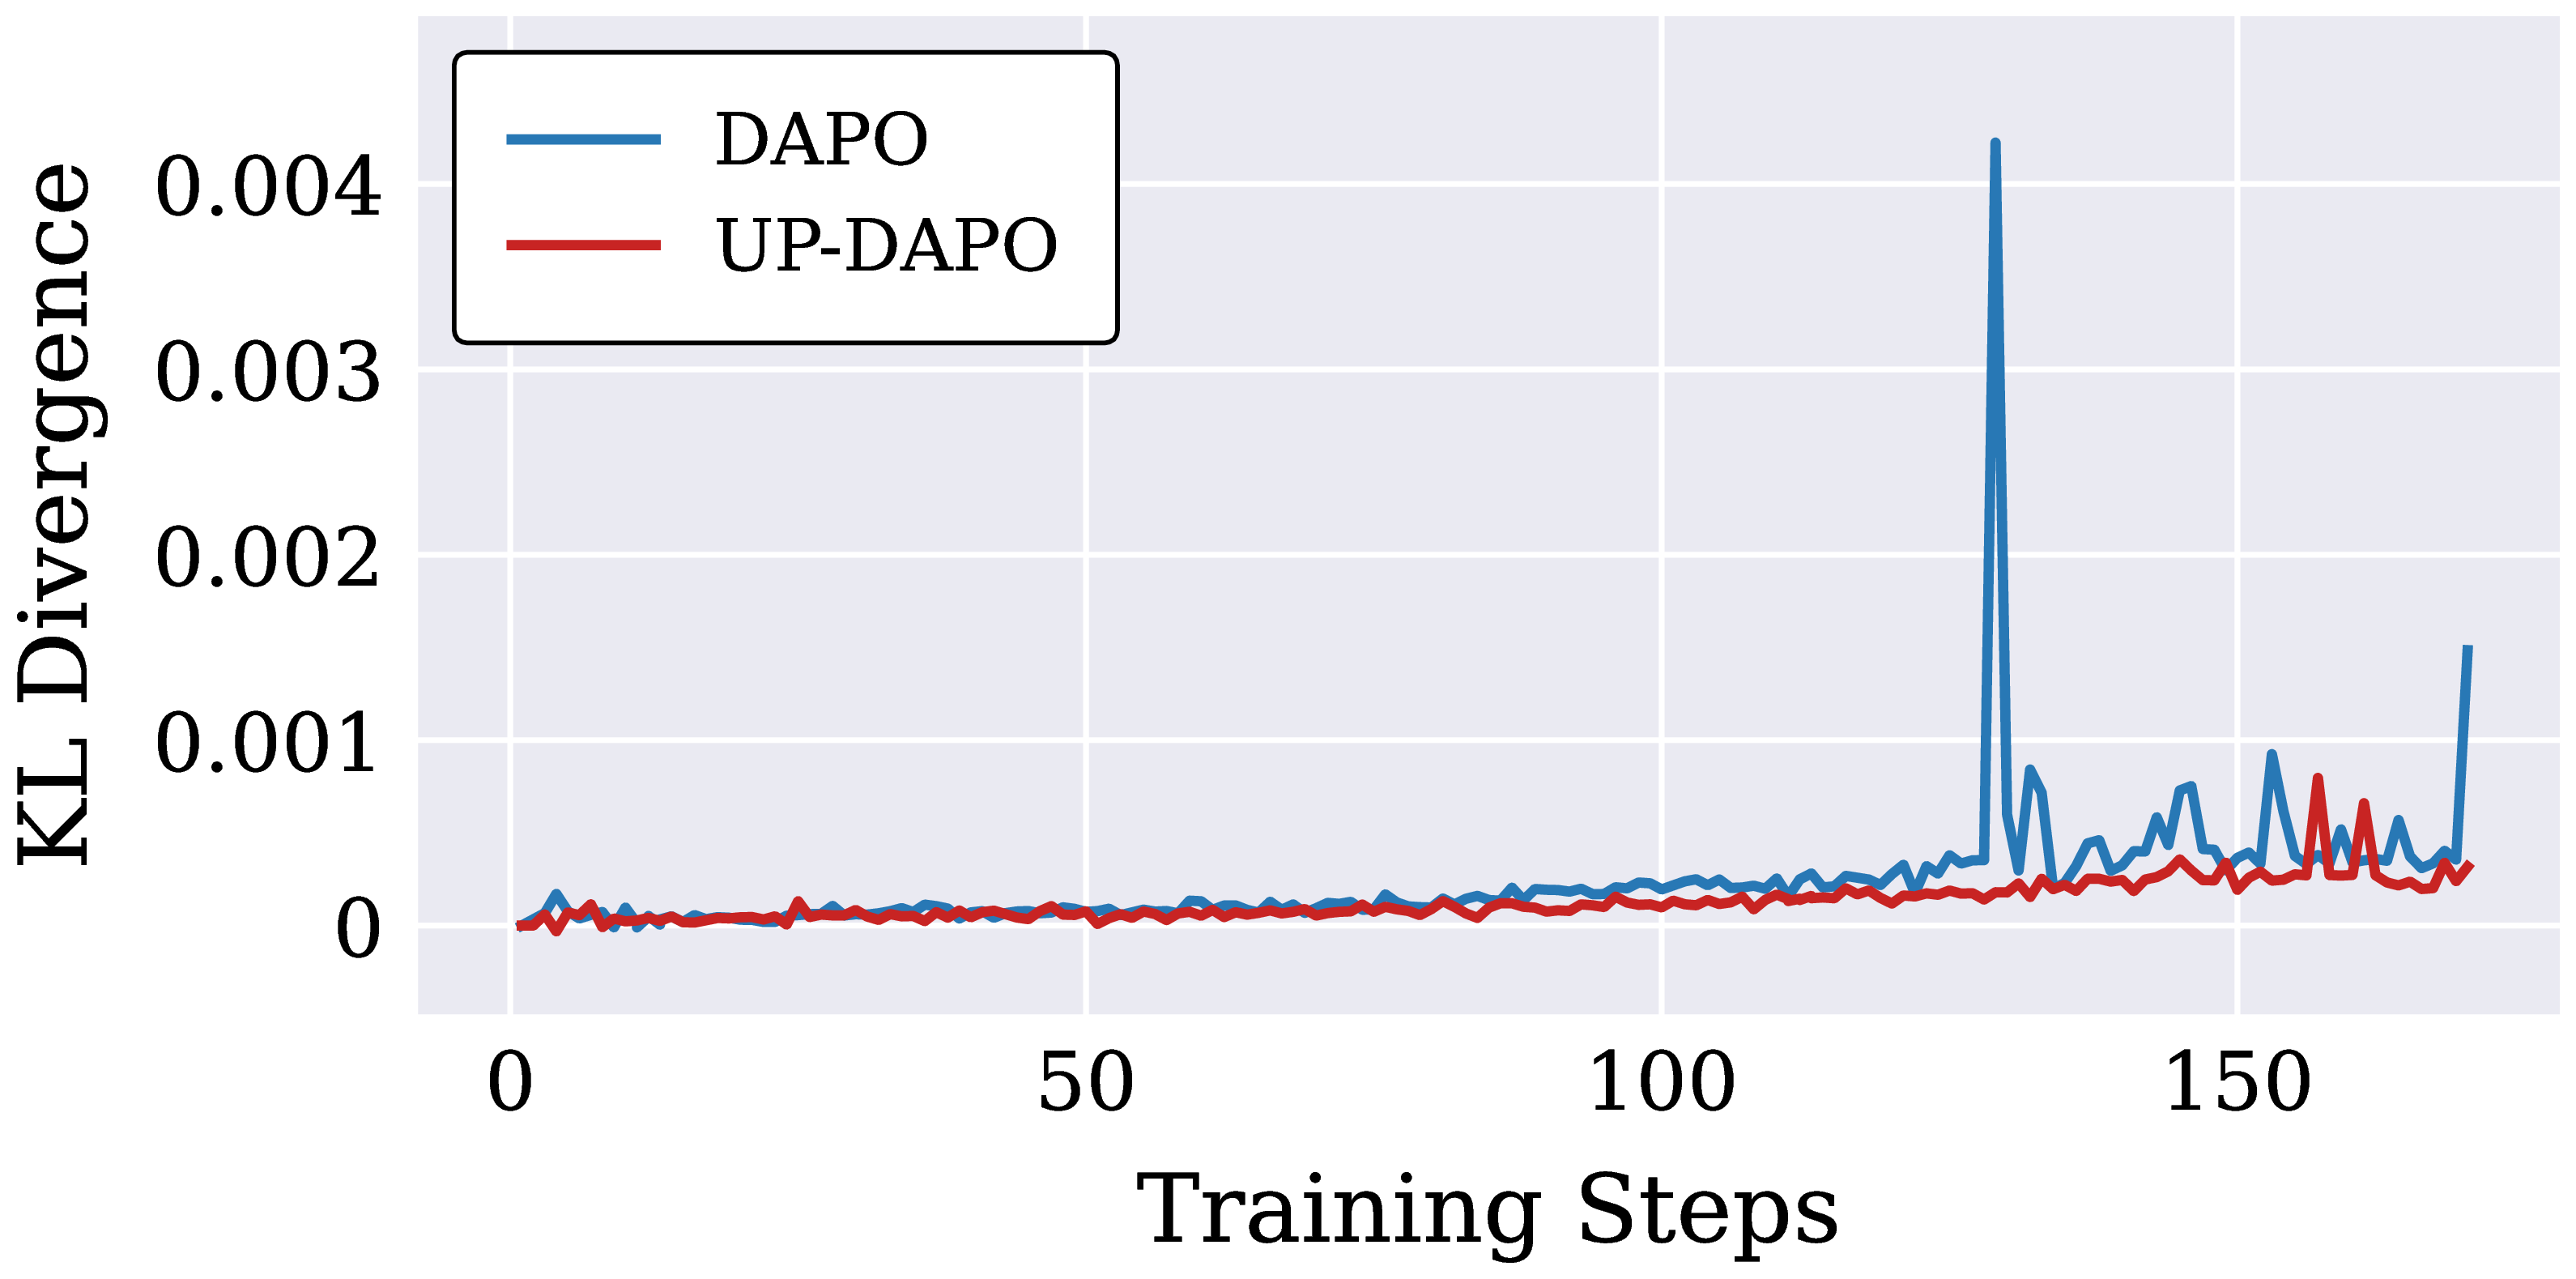
  <p>On Qwen3-14B-Base trained on DAPO-17K-MATH and evaluated on AIME24, UP-DAPO comprehensively outperforms DAPO. As shown in <a href="#fig-2">Figure 2</a>, it lifts peak Avg@32 from \(47.71\) to \(51.15\) and Maj@32 from \(58.36\) to \(60.88\). <a href="#fig-3">Figure 3</a> traces the source of these gains: a consistently higher generation entropy alongside a higher Best@32 (from \(80.49\) to \(81.79\)) confirms that removing the \(\pi_{\text{old}}\) anchor genuinely enlarges exploration capacity. Crucially, <a href="#fig-4">Figure 4</a> shows the gradient norm and the KL divergence of UP-DAPO stay comparable to, or slightly below, DAPO’s, so this added exploration does not cost stability.</p>

  <div id="fig-2" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/avg32_plot.png" alt="Avg@32 accuracy on AIME24" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Avg@32</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/maj32_plot.png" alt="Maj@32 accuracy on AIME24" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) Maj@32</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 2. Performance comparison of DAPO and UP-DAPO on Qwen3-14B-Base during training: (a) Avg@32 and (b) Maj@32 accuracy on AIME24. UP-DAPO reaches a peak Avg@32 of 51.15 against DAPO's 47.71, and a peak Maj@32 of 60.88 against 58.36.</p>

  <div id="fig-3" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/entropy_plot.png" alt="Generation entropy on DAPO-17K-MATH" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Entropy</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/best32_plot.png" alt="Best@32 accuracy on AIME24" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) Best@32</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 3. Exploration capacity of UP-DAPO: (a) entropy of generation probabilities on DAPO-17K-MATH and (b) Best@32 accuracy on AIME24. UP-DAPO sustains a higher entropy and lifts peak Best@32 to 81.79 against DAPO's 80.49.</p>

  <div id="fig-4" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grad_norm_plot.png" alt="Gradient norm on DAPO-17K-MATH" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Gradient norm</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/kl_plot.png" alt="KL divergence to the reference model" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL divergence</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 4. Training stability of UP-DAPO: (a) gradient norm and (b) KL divergence between the active policy and the reference model on DAPO-17K-MATH. Both quantities track DAPO closely, so the extra exploration does not destabilize training.</p>

  <h3 id="ablation-studies-of-up-dapo">Ablation Studies of UP-DAPO</h3>

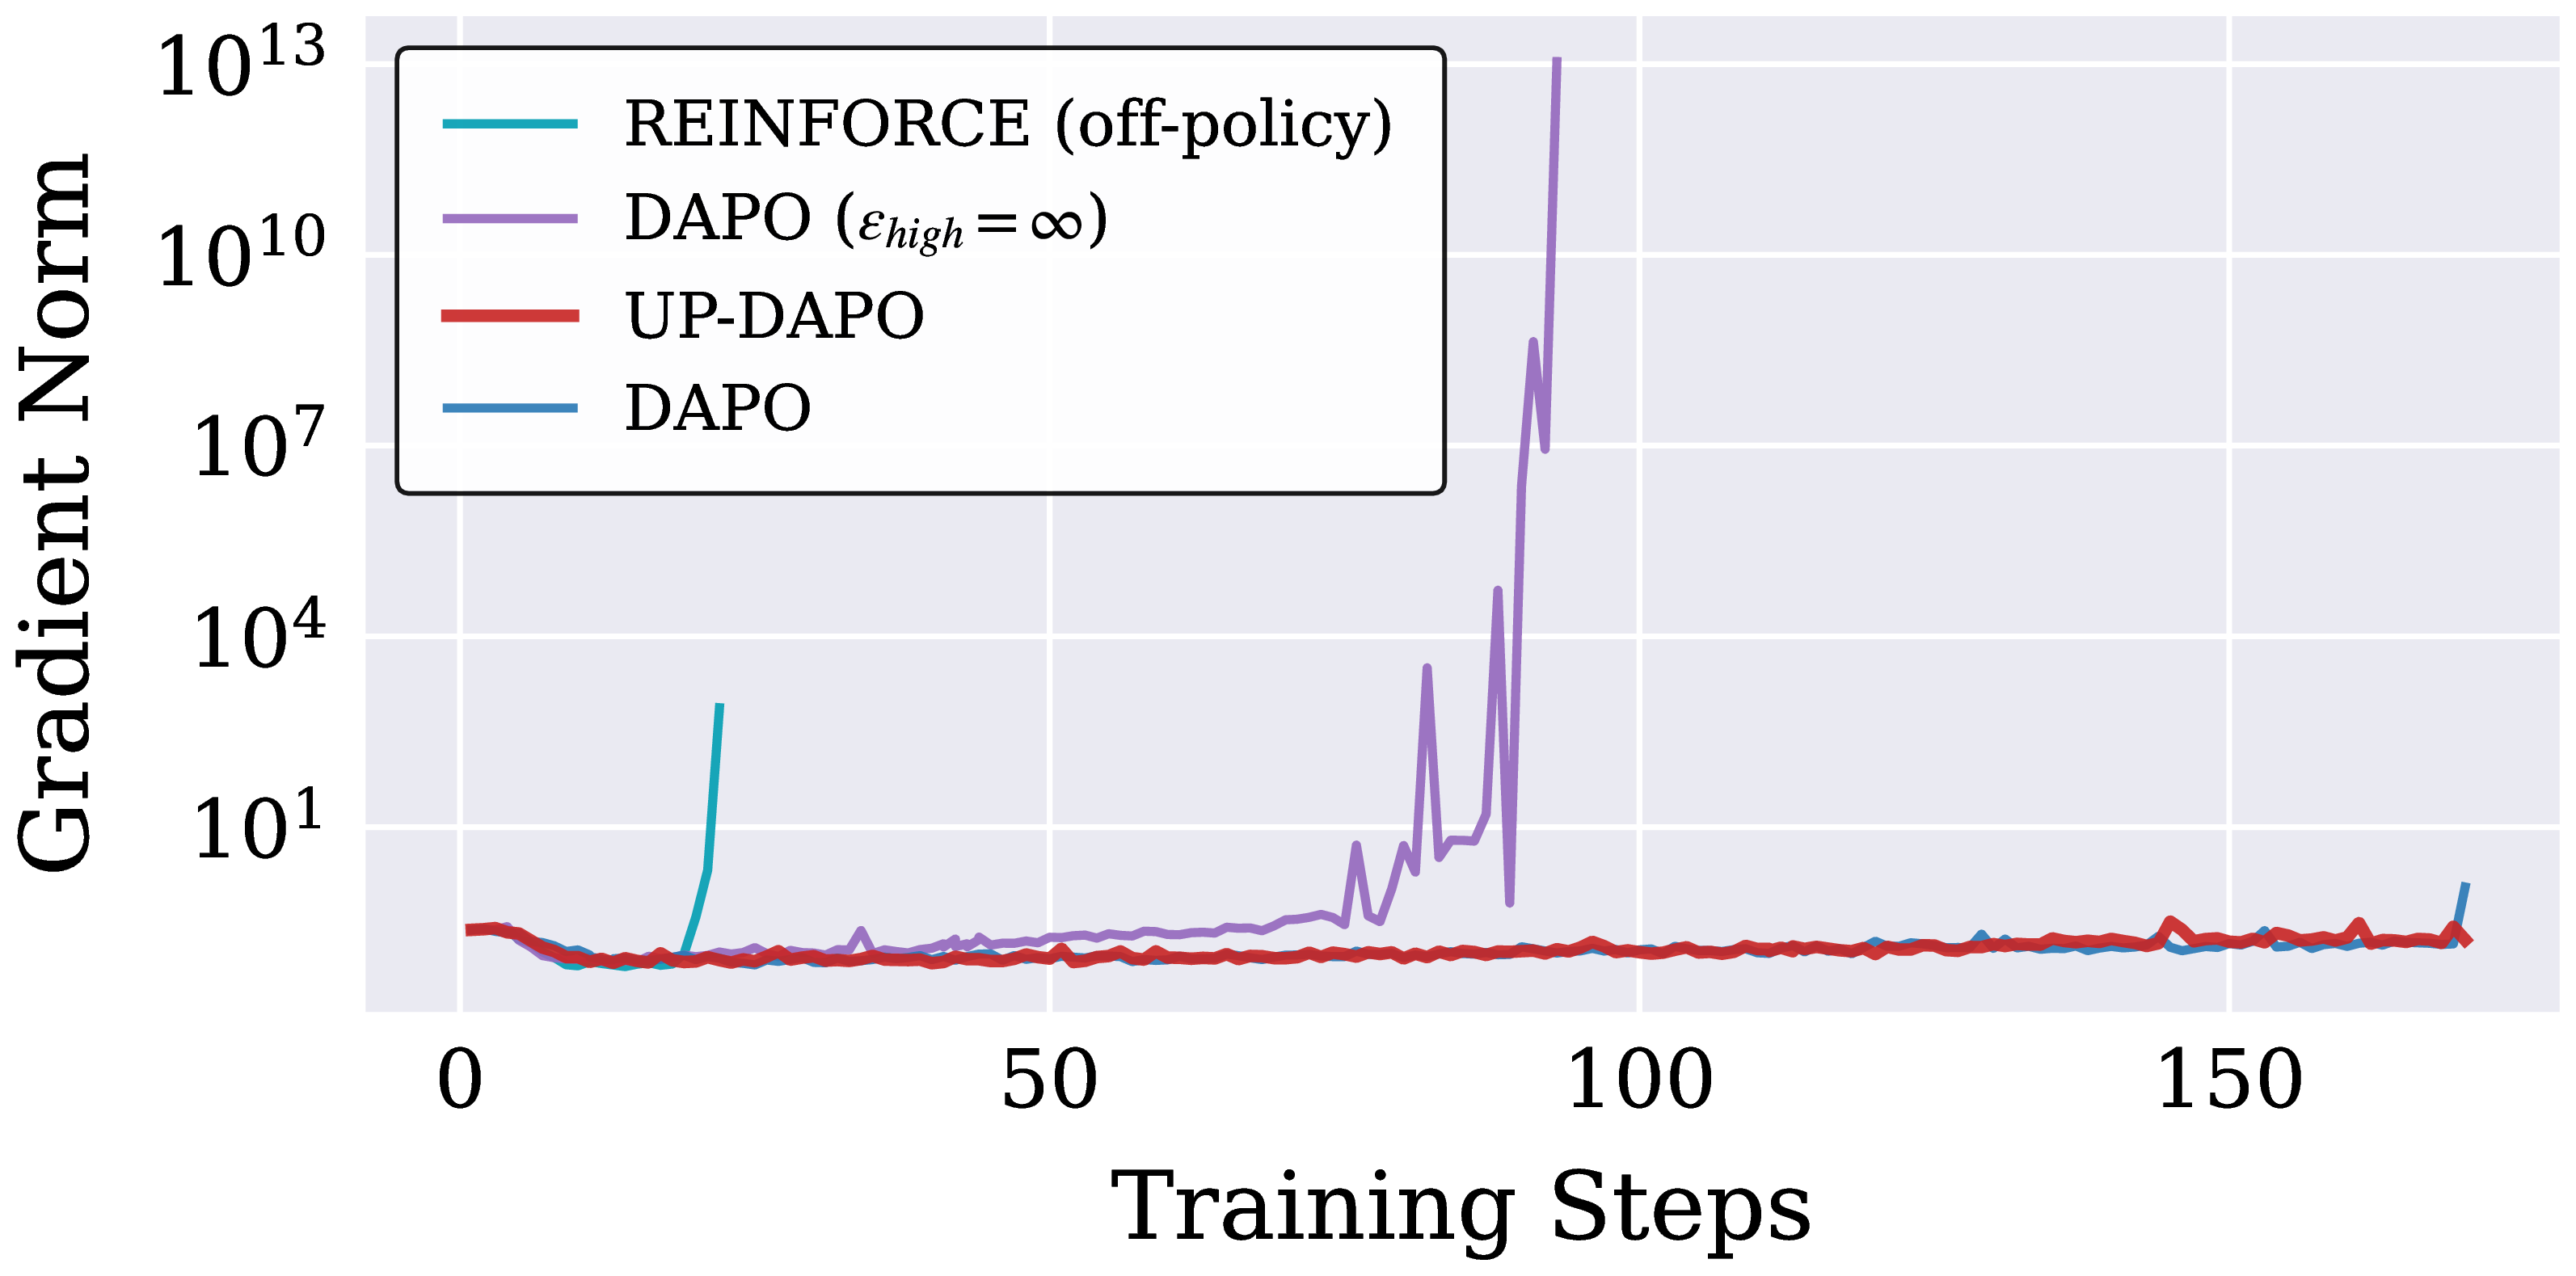
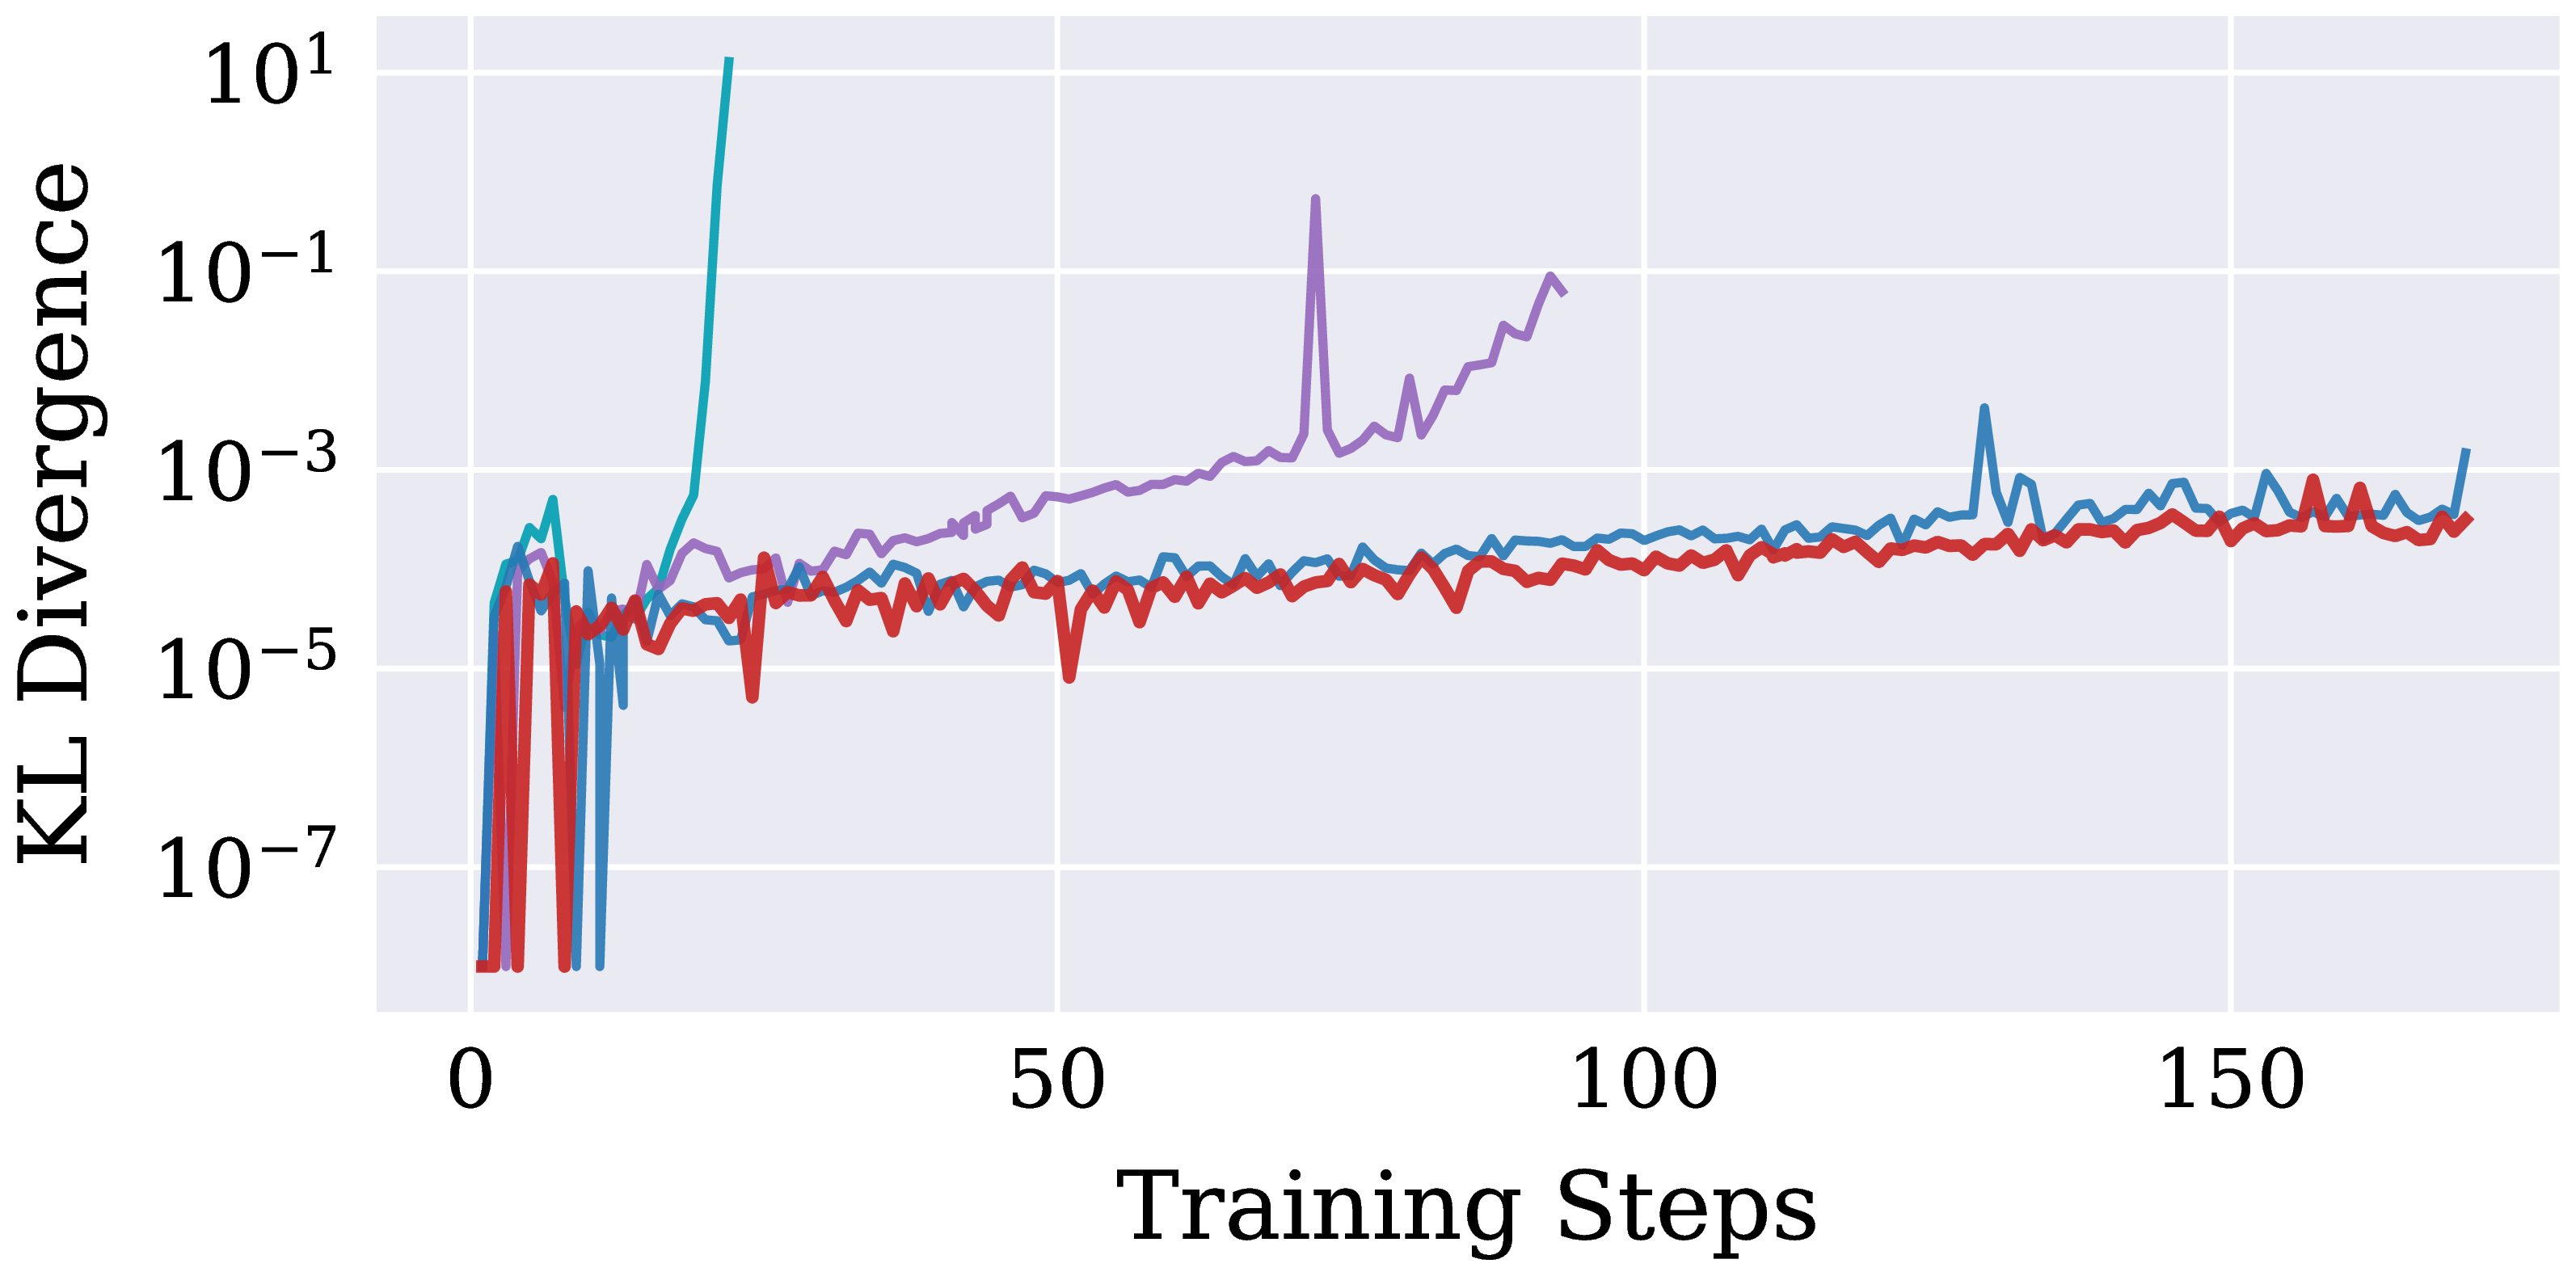
  <p>Two ablations pin down why both design choices are necessary. As <a href="#fig-5">Figure 5</a> shows, simply relaxing DAPO’s upper clip to infinity while keeping the \(\pi_{\text{old}}\) anchor stays stable at first but explodes beyond 80 steps, with the gradient norm surging to \(10^{13}\); this shows the self-anchored ratio, not merely a loosened bound, is what enables safe unbounded updates. Applying the unbounded update symmetrically to both positive and negative advantages collapses within 25 steps, confirming that clipping on the negative branch is an indispensable safeguard.</p>

  <div id="fig-5" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grad_norm_log_plot.png" alt="Gradient norm on a log scale" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Gradient norm (log scale)</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/kl_log_plot.png" alt="KL divergence on a log scale" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL divergence (log scale)</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 5. Training stability of DAPO, DAPO with \(\epsilon_{\text{high}} = \infty\), REINFORCE (off-policy), and UP-DAPO on Qwen3-14B-Base: (a) gradient norm and (b) KL divergence, both on a log scale. DAPO with \(\epsilon_{\text{high}} = \infty\) explodes to \(10^{13}\) after about 80 steps, and the symmetric unbounded variant collapses within 25 steps, while UP-DAPO stays stable.</p>

  <h3 id="comparison-with-other-rl-baselines">Comparison with Other RL Baselines</h3>

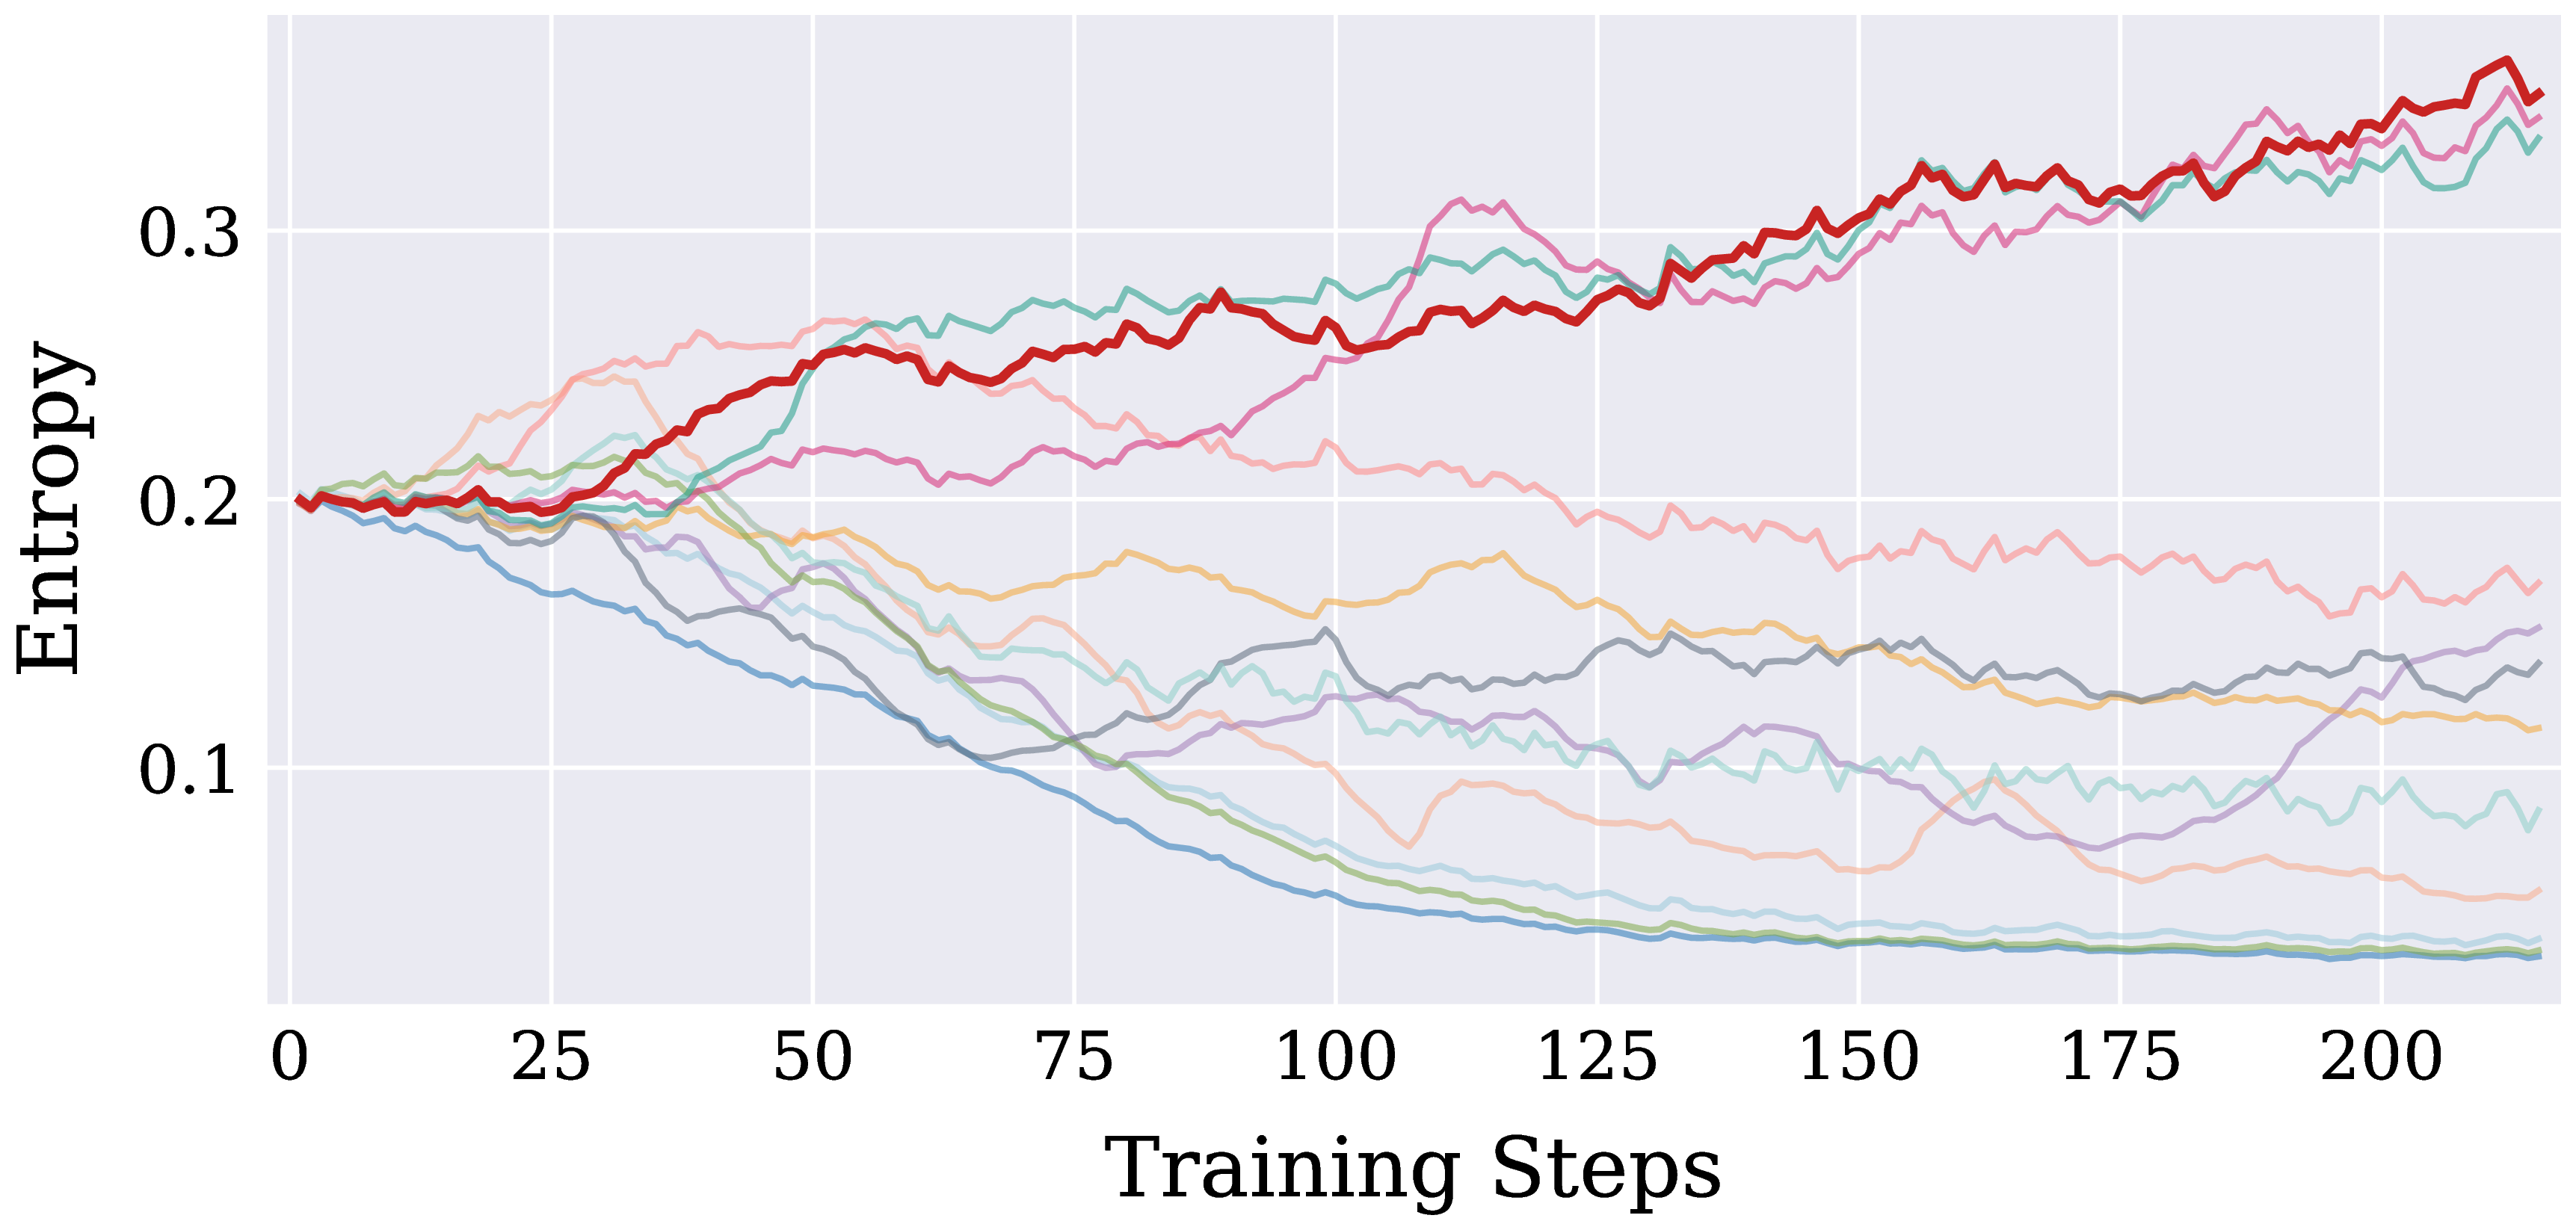
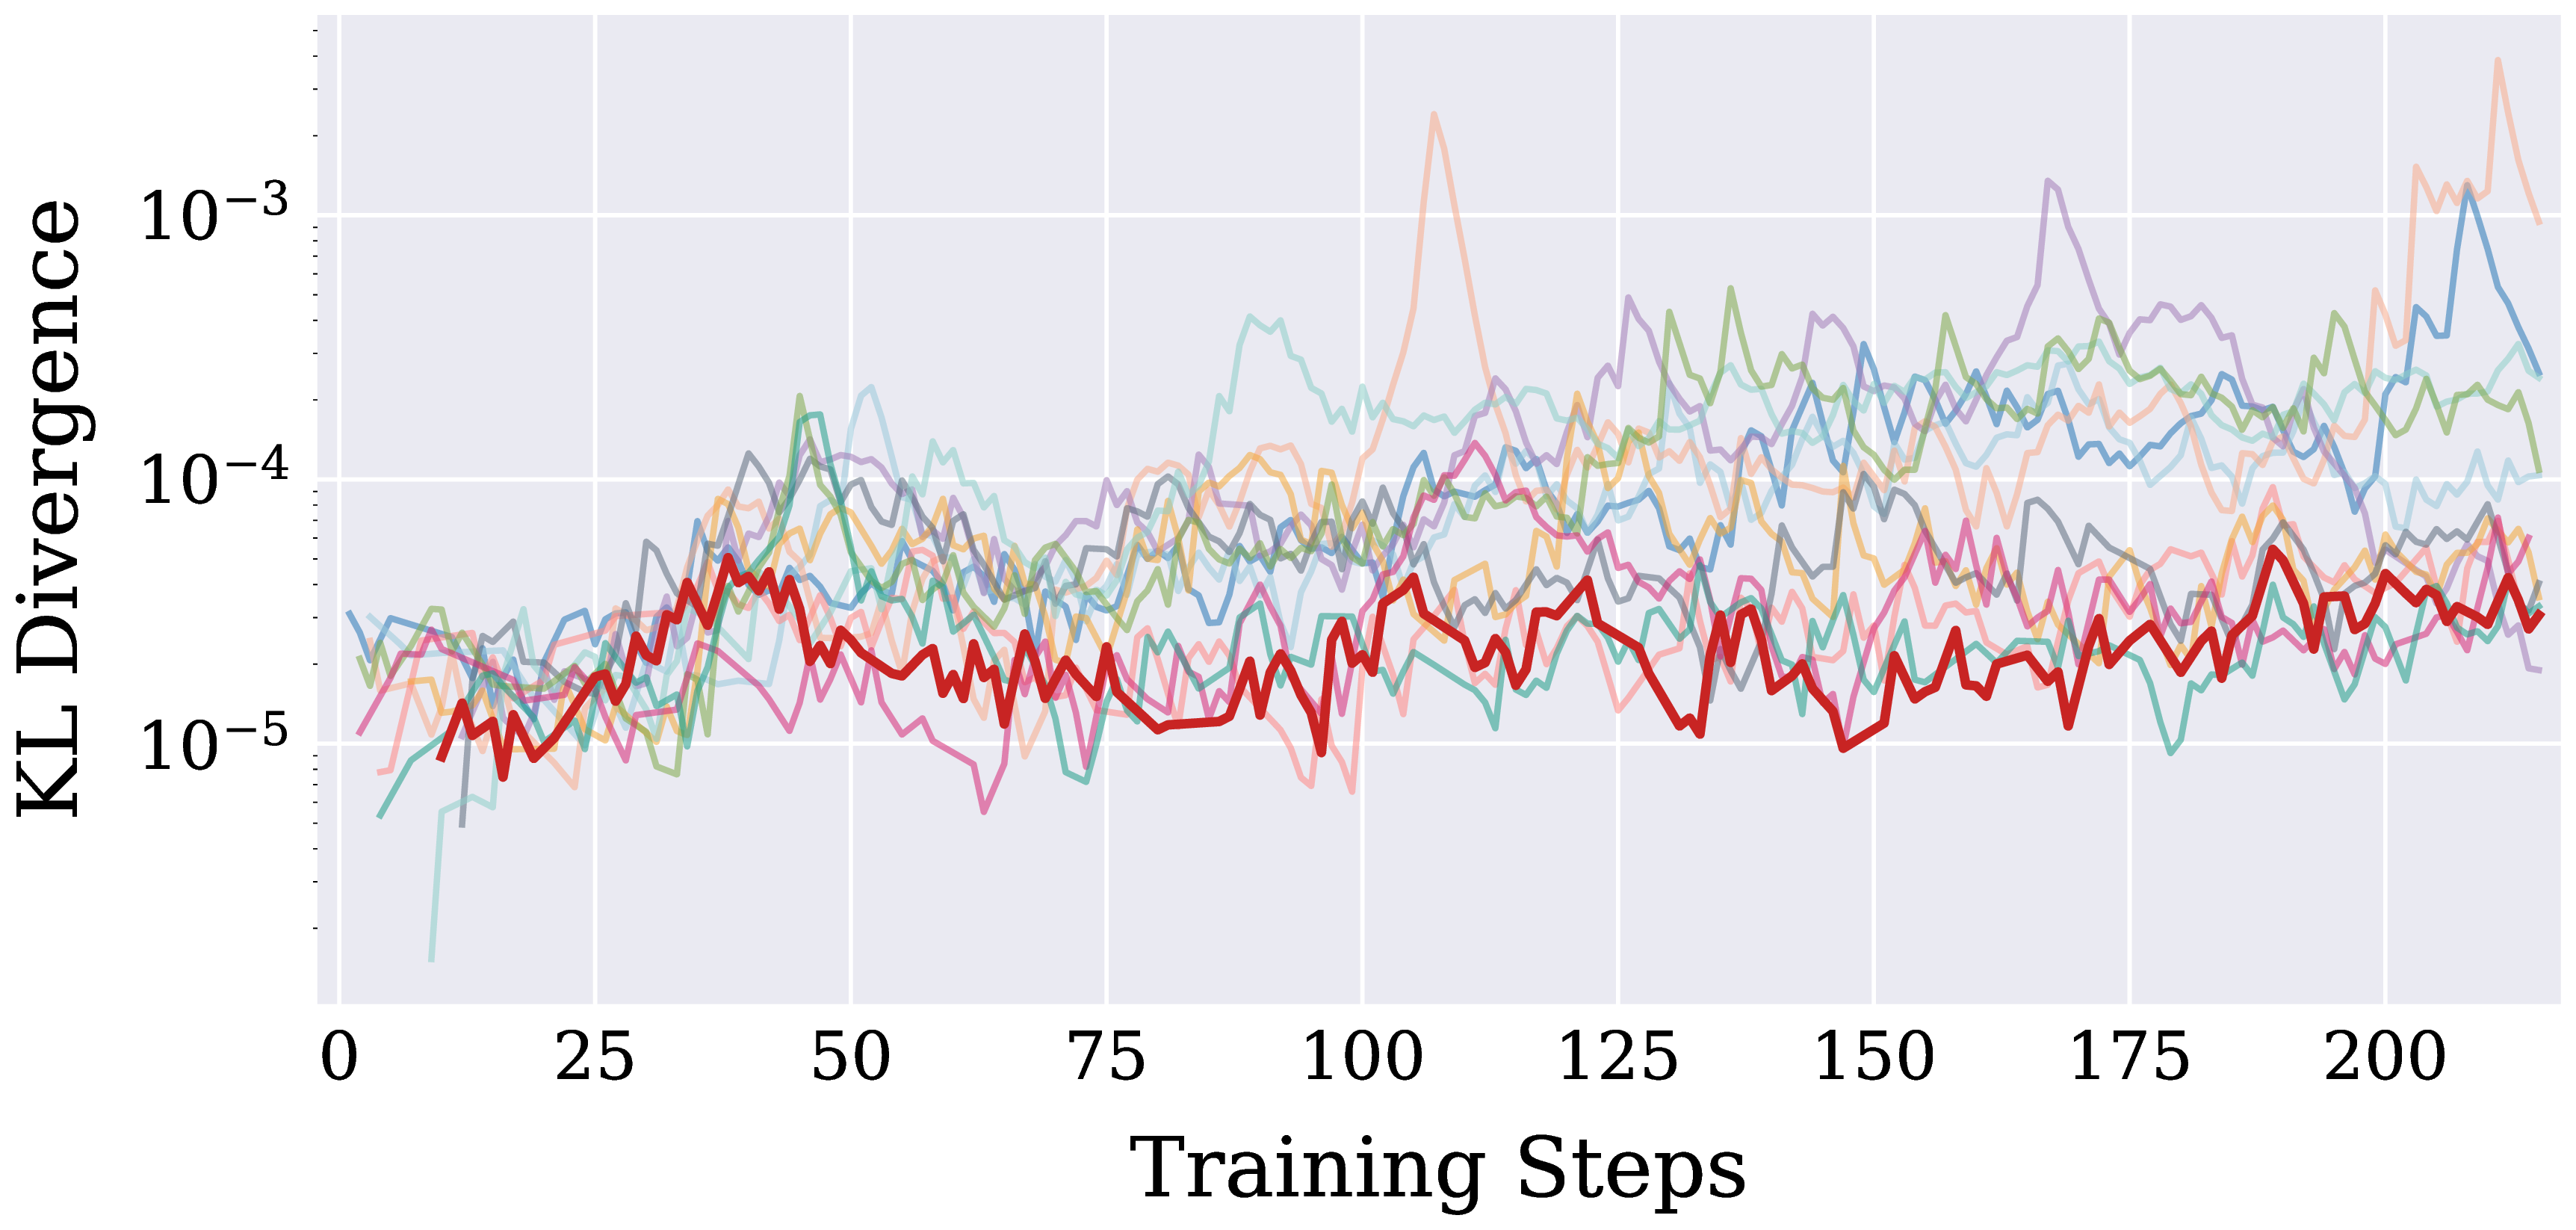
  <p>Under the unified protocol of Liu et al., we train Qwen3-8B on MATH (Levels 3 to 5) and evaluate Pass@1 across five reasoning benchmarks. As reported in <a href="#tab-1">Table 1</a>, UP-GRPO attains the best average accuracy of \(61.31\%\), surpassing the strongest prior baseline GSPO (\(60.15\%\)) by an absolute \(1.16\%\). UP-GRPO ranks first or ties for first on four of the five individual benchmarks, and remains highly competitive on OlympiadBench, second only to ASPO. Consistent gains across benchmarks of varying difficulty show that the unbounded positive update is a broadly effective, rather than benchmark-specific, improvement over the GxPO family. <a href="#fig-6">Figure 6</a> explains these downstream gains: UP-GRPO’s policy entropy keeps rising throughout training while most baselines suffer entropy collapse, and its KL divergence stays among the lowest of the twelve methods.</p>

  <div id="tab-1" class="results-table">

    <table>
      <thead>
        <tr>
          <th style="text-align: left">Method</th>
          <th style="text-align: center">AIME24</th>
          <th style="text-align: center">AMC23</th>
          <th style="text-align: center">MATH500</th>
          <th style="text-align: center">Minerva</th>
          <th style="text-align: center">OlympiadBench</th>
          <th style="text-align: center">Average</th>
        </tr>
      </thead>
      <tbody>
        <tr>
          <td style="text-align: left">GRPO</td>
          <td style="text-align: center">35.73</td>
          <td style="text-align: center">75.00</td>
          <td style="text-align: center">86.00</td>
          <td style="text-align: center">30.88</td>
          <td style="text-align: center">51.34</td>
          <td style="text-align: center">55.79</td>
        </tr>
        <tr>
          <td style="text-align: left">Dr. GRPO</td>
          <td style="text-align: center">33.33</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">85.80</td>
          <td style="text-align: center">30.15</td>
          <td style="text-align: center">51.19</td>
          <td style="text-align: center">57.09</td>
        </tr>
        <tr>
          <td style="text-align: left">CISPO</td>
          <td style="text-align: center">38.02</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">86.60</td>
          <td style="text-align: center">29.04</td>
          <td style="text-align: center">55.65</td>
          <td style="text-align: center">59.36</td>
        </tr>
        <tr>
          <td style="text-align: left">DPPO</td>
          <td style="text-align: center">40.10</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">86.20</td>
          <td style="text-align: center">30.51</td>
          <td style="text-align: center">53.27</td>
          <td style="text-align: center">59.52</td>
        </tr>
        <tr>
          <td style="text-align: left">GMPO</td>
          <td style="text-align: center">37.50</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">87.00</td>
          <td style="text-align: center">31.25</td>
          <td style="text-align: center">55.06</td>
          <td style="text-align: center">59.66</td>
        </tr>
        <tr>
          <td style="text-align: left">GSPO</td>
          <td style="text-align: center">40.52</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">88.20</td>
          <td style="text-align: center">31.25</td>
          <td style="text-align: center">55.80</td>
          <td style="text-align: center">60.15</td>
        </tr>
        <tr>
          <td style="text-align: left">SAPO</td>
          <td style="text-align: center">39.90</td>
          <td style="text-align: center">82.50</td>
          <td style="text-align: center">87.20</td>
          <td style="text-align: center">30.88</td>
          <td style="text-align: center">55.65</td>
          <td style="text-align: center">59.23</td>
        </tr>
        <tr>
          <td style="text-align: left">REINFORCE++</td>
          <td style="text-align: center">20.52</td>
          <td style="text-align: center">62.50</td>
          <td style="text-align: center">78.80</td>
          <td style="text-align: center">29.78</td>
          <td style="text-align: center">42.26</td>
          <td style="text-align: center">46.77</td>
        </tr>
        <tr>
          <td style="text-align: left">RLOO</td>
          <td style="text-align: center">31.67</td>
          <td style="text-align: center">80.00</td>
          <td style="text-align: center">85.20</td>
          <td style="text-align: center">28.68</td>
          <td style="text-align: center">50.60</td>
          <td style="text-align: center">55.23</td>
        </tr>
        <tr>
          <td style="text-align: left">W-REINFORCE</td>
          <td style="text-align: center">35.52</td>
          <td style="text-align: center">80.00</td>
          <td style="text-align: center">85.80</td>
          <td style="text-align: center">30.15</td>
          <td style="text-align: center">53.27</td>
          <td style="text-align: center">56.95</td>
        </tr>
        <tr>
          <td style="text-align: left">ASPO</td>
          <td style="text-align: center">37.50</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">87.60</td>
          <td style="text-align: center">29.78</td>
          <td style="text-align: center"><strong>58.48</strong></td>
          <td style="text-align: center">59.67</td>
        </tr>
        <tr>
          <td style="text-align: left"><strong>UP-GRPO (Ours)</strong></td>
          <td style="text-align: center"><strong>41.04</strong></td>
          <td style="text-align: center"><strong>87.50</strong></td>
          <td style="text-align: center"><strong>88.40</strong></td>
          <td style="text-align: center"><strong>31.25</strong></td>
          <td style="text-align: center">58.33</td>
          <td style="text-align: center"><strong>61.31</strong></td>
        </tr>
      </tbody>
    </table>

  </div>
  <p class="fig-caption">Table 1. UP-GRPO against eleven RL baselines on AIME24, AMC23, MATH500, Minerva, and OlympiadBench (Pass@1, %), trained on MATH (Levels 3 to 5) with Qwen3-8B. Best per column in <strong>bold</strong>.</p>

  <div id="fig-6" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px 8px; row-gap: 0;">
  <div class="fig-legend" style="margin-top: 0; margin-bottom: -4px;">
    <img src="/images/blog/up/grpo_family_legend.png" alt="Legend: UP-GRPO and eleven RL baselines" />
  </div>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grpo_family_entropy_plot.png" alt="Policy entropy of UP-GRPO and baselines" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Entropy</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grpo_family_kl_plot.png" alt="KL divergence of UP-GRPO and baselines" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL divergence</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 6. Exploration capacity and training stability of UP-GRPO against eleven RL baselines on Qwen3-8B during training: (a) entropy and (b) KL divergence between the active policy and the reference model on MATH (Levels 3 to 5). Most baselines suffer entropy collapse, while UP-GRPO keeps a rising entropy and holds its KL divergence among the lowest.</p>

  <h3 id="universality-of-up-across-algorithms-architectures-and-modalities">Universality of UP across Algorithms, Architectures, and Modalities</h3>

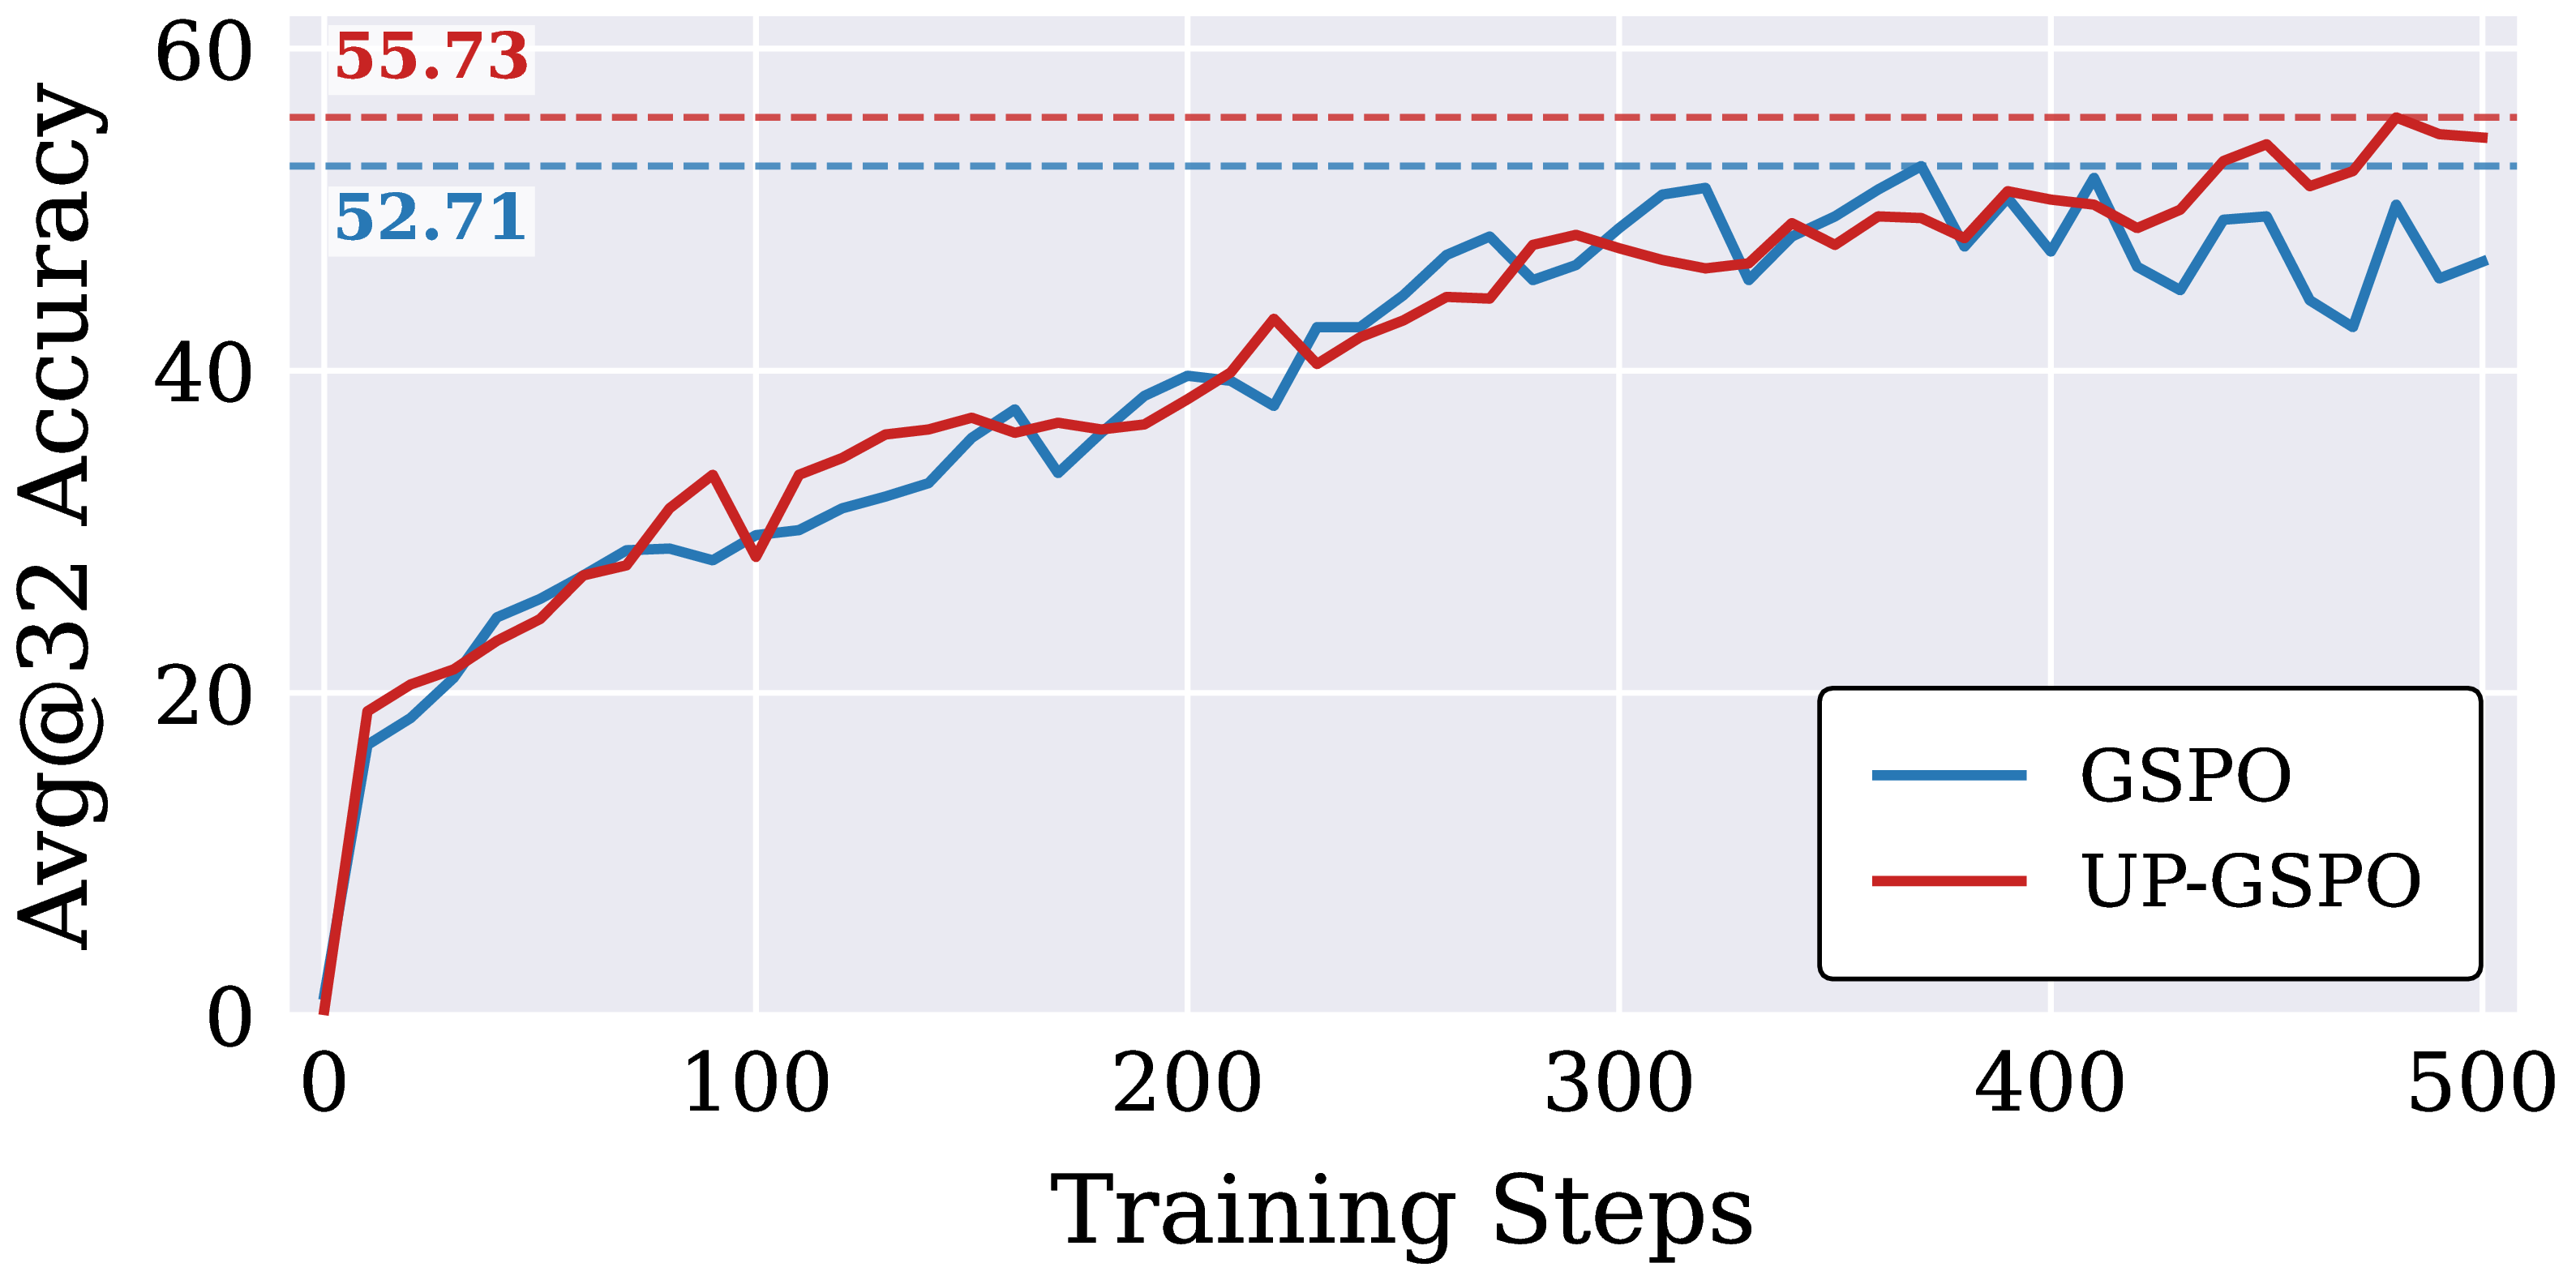
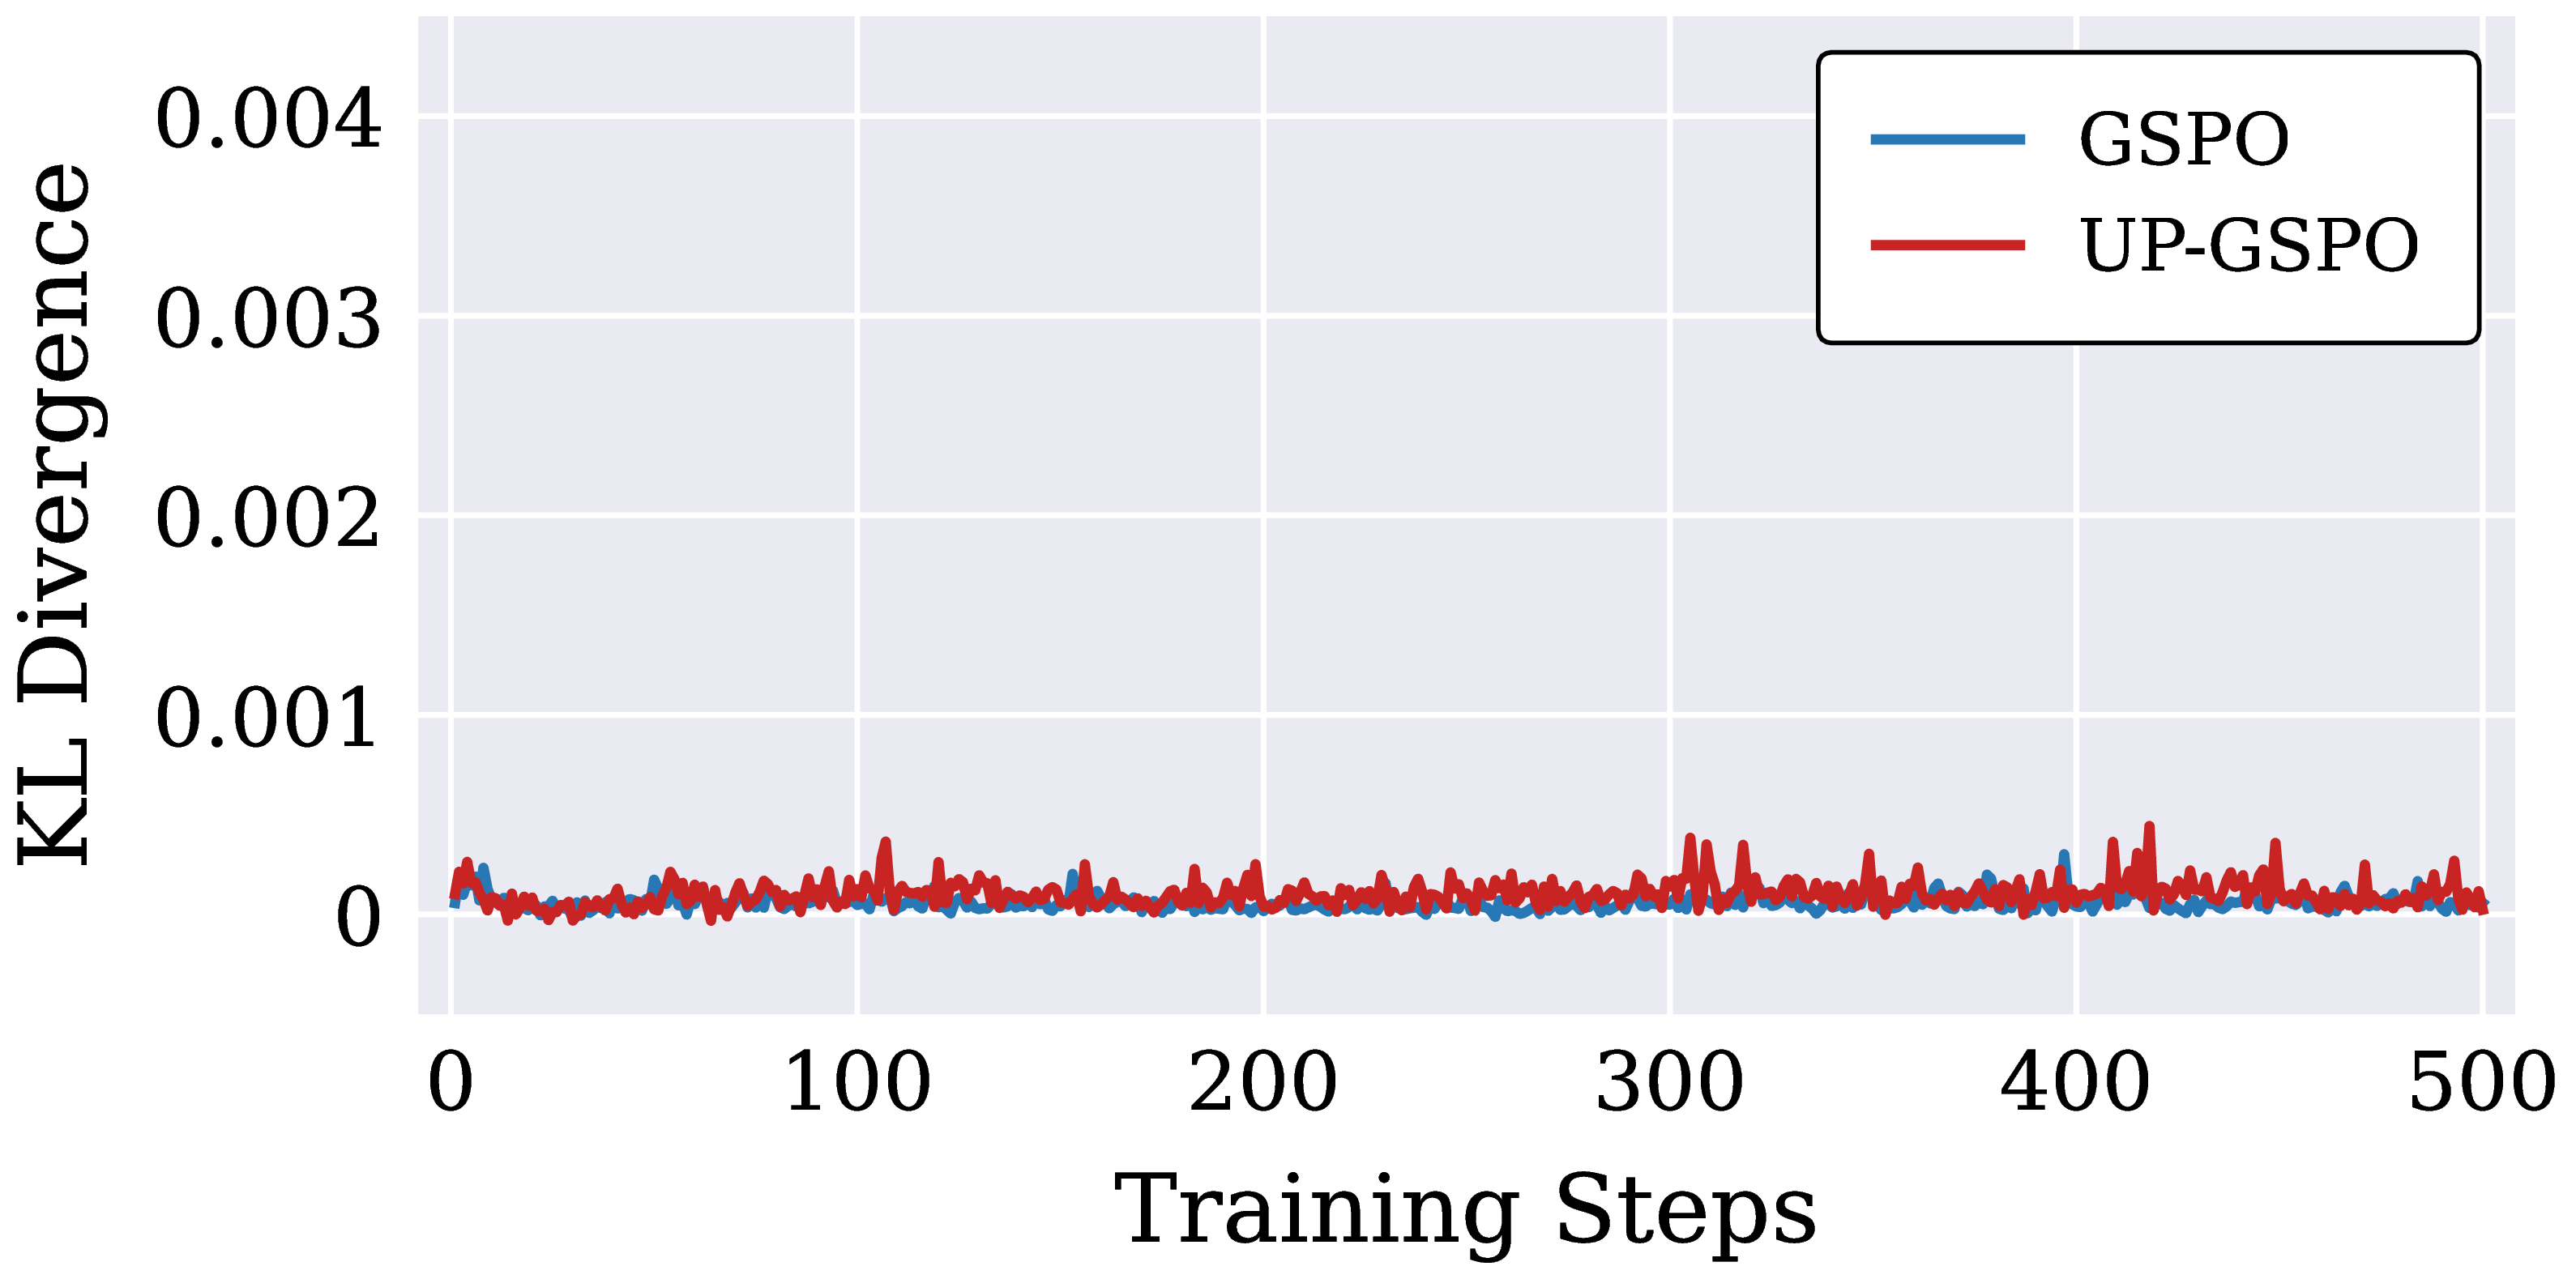
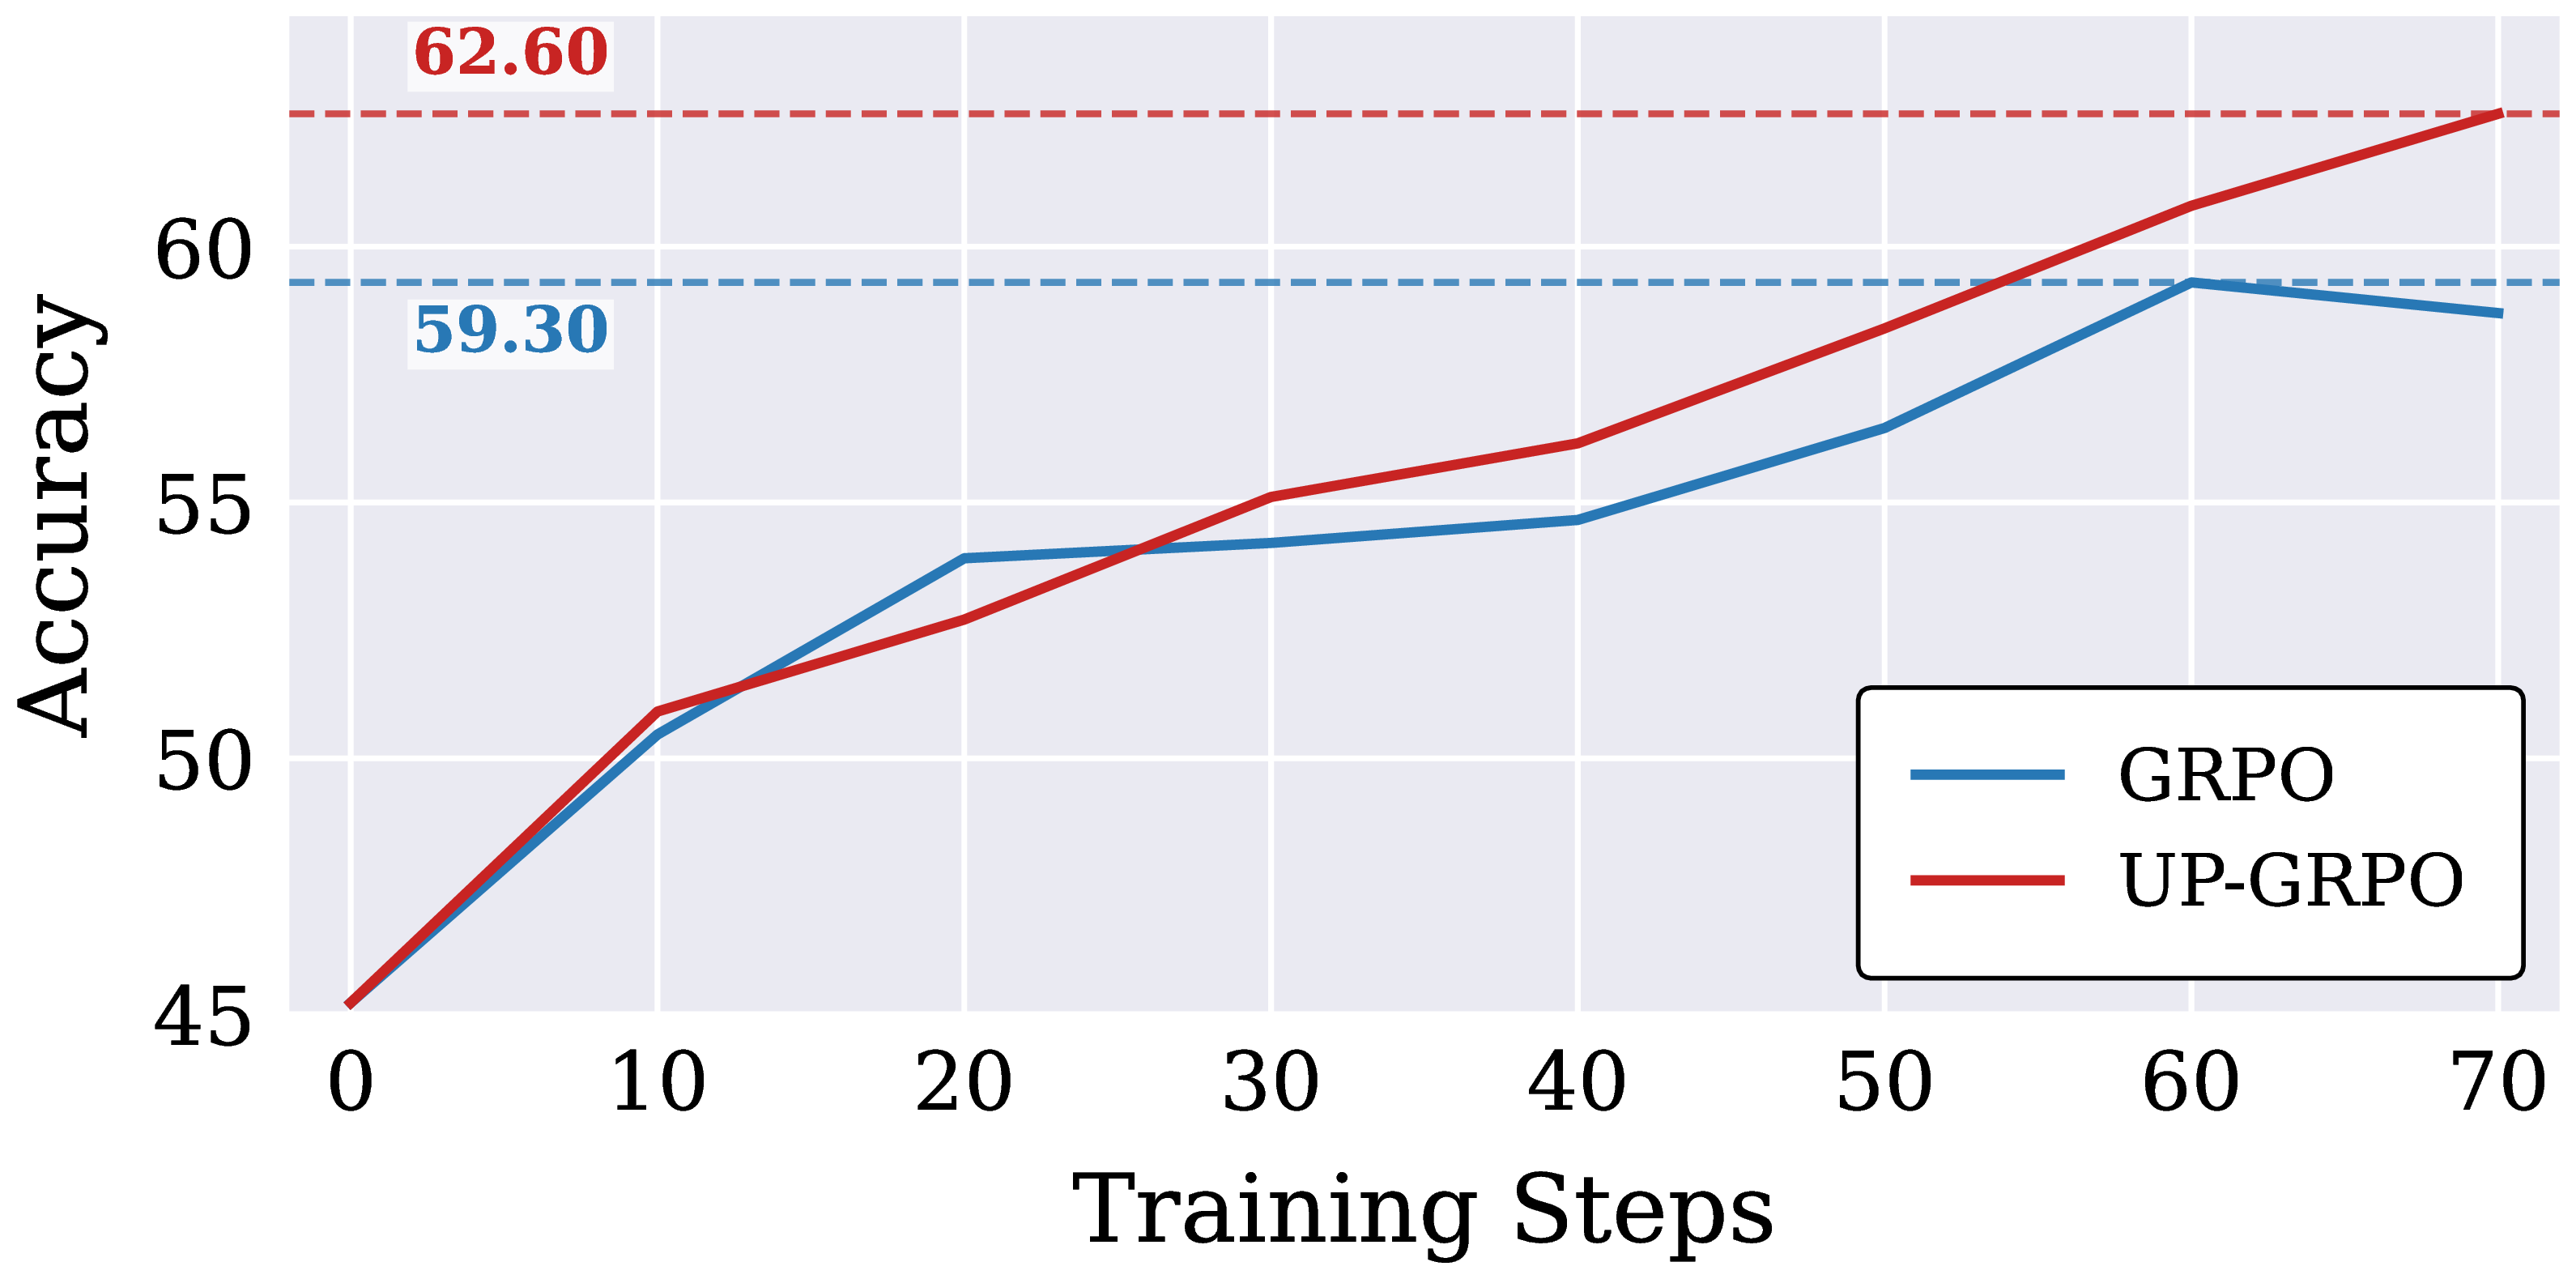
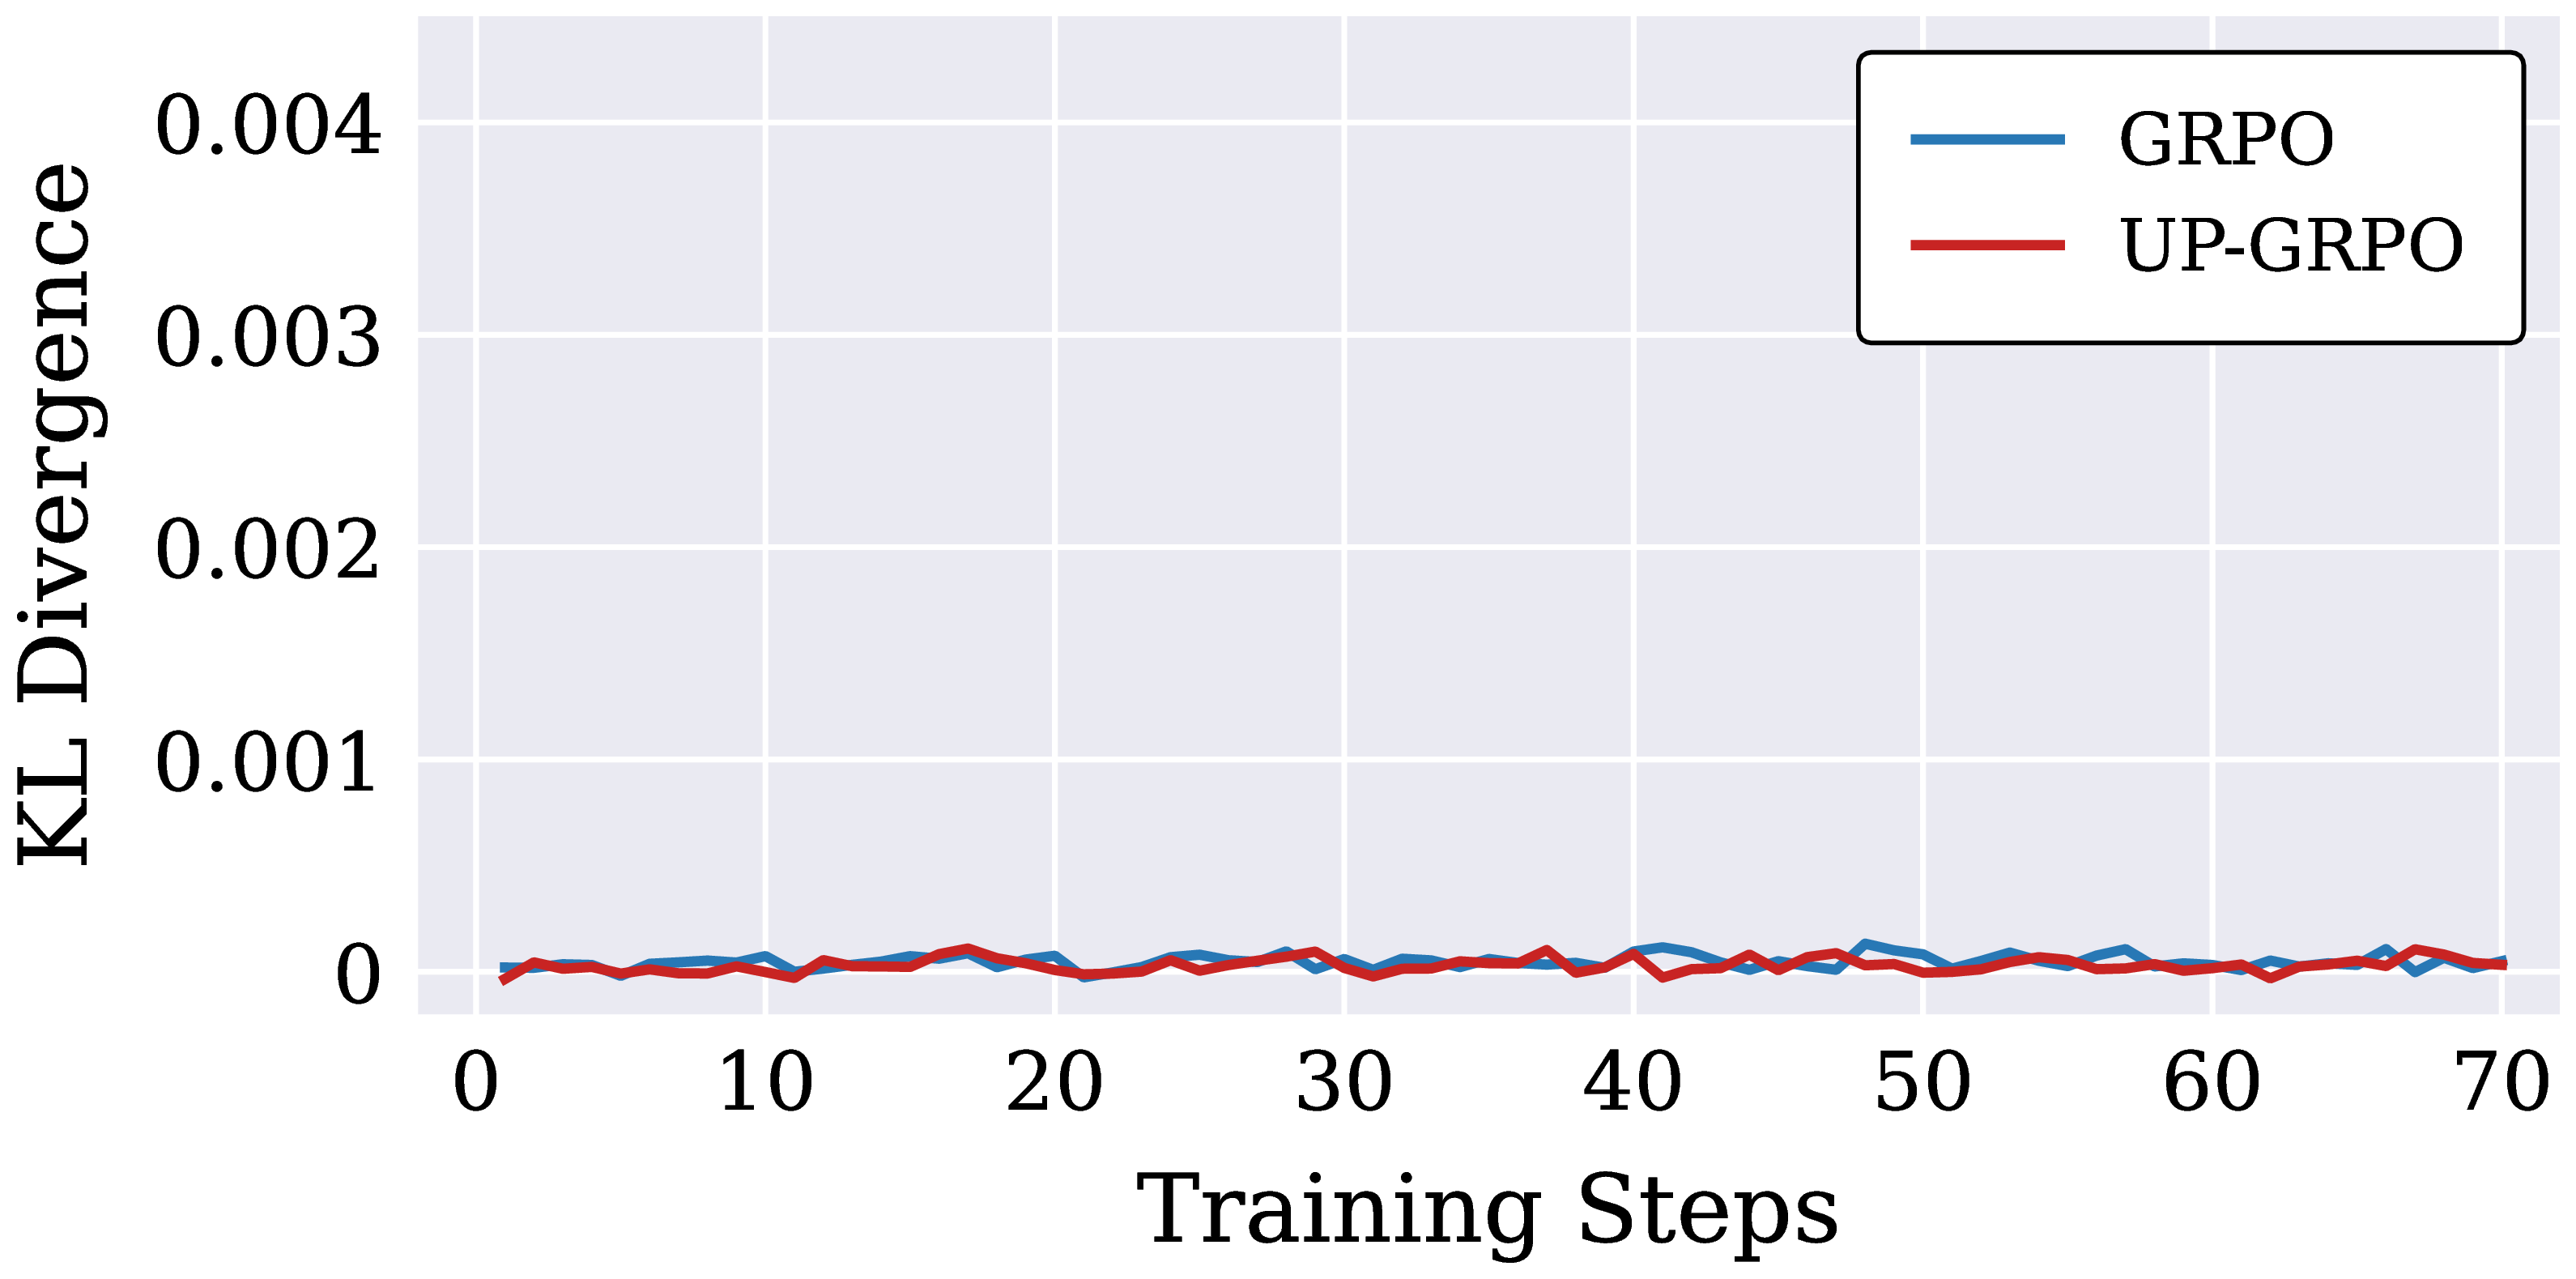
  <p>UP is a universal plugin, not a token-level trick. On the <strong>MoE</strong> model Qwen3-30B-A3B-Base, <a href="#fig-7">Figure 7</a> shows UP-GSPO raises peak Avg@32 on AIME24 from GSPO’s \(52.71\%\) to \(55.73\%\), an absolute \(3.02\%\), while keeping KL divergence nearly identical to the baseline. On the <strong>vision-language</strong> model Qwen3-VL-8B-Instruct trained on Geometry3K, <a href="#fig-8">Figure 8</a> shows UP-GRPO lifts accuracy from GRPO’s \(59.30\%\) to \(62.60\%\), an absolute \(3.30\%\), again without any added instability. Together these results show UP resolves the exploration-stability dilemma regardless of optimization granularity (token-level to sequence-level), model architecture (dense to MoE), or modality (language to multimodal).</p>

  <div id="fig-7" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/gspo_avg32_plot.png" alt="Avg@32 accuracy of GSPO and UP-GSPO on AIME24" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Avg@32</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/gspo_kl_plot.png" alt="KL divergence of GSPO and UP-GSPO" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL divergence</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 7. Performance and stability comparison of GSPO and UP-GSPO on Qwen3-30B-A3B-Base (MoE): (a) Avg@32 accuracy on AIME24 and (b) KL divergence on DAPO-17K-MATH. UP-GSPO reaches a peak Avg@32 of 55.73 against GSPO's 52.71, an absolute gain of 3.02.</p>

  <div id="fig-8" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/vlm_avg32_plot.png" alt="Accuracy of GRPO and UP-GRPO on Geometry3K" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Accuracy</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/vlm_kl_plot.png" alt="KL divergence of GRPO and UP-GRPO" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL divergence</figcaption>
  </figure>
</div>
  <p class="fig-caption">Figure 8. Performance and stability comparison of GRPO and UP-GRPO on Qwen3-VL-8B-Instruct: (a) accuracy on the Geometry3K test set and (b) KL divergence. UP-GRPO reaches 62.60 against GRPO's 59.30, an absolute gain of 3.30.</p>

  <h2 id="bibtex">BibTeX</h2>

  <pre class="bibtex-block"><code>@misc{fan2026upunboundedpositiveasymmetric,
      title={UP: Unbounded Positive Asymmetric Optimization for Breaking the Exploration-Stability Dilemma}, 
      author={Chongyu Fan and Pengfei Liu and Jingjia Huang and Sijia Liu and Yi Lin},
      year={2026},
      eprint={2607.06987},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2607.06987}, 
}
</code></pre>

</div>

<div class="post-lang post-lang-zh" hidden="">

  <div class="tldr">

    <h2 id="tldr-1">TL;DR</h2>

    <ul>
      <li>现代面向 LLM 推理的强化学习 (RL) 依赖重要性采样 (IS) 来提升样本效率，但 IS 带来了探索与稳定的两难：纯 IS 会梯度爆炸，而用于抑制爆炸的裁剪又会严格限制策略的可变动幅度。</li>
      <li>我们把一个 token 在梯度被截断前所拥有的更新预算形式化为 <strong>概率容量 (Probability Capacity, Cap)</strong>，并指出保守的裁剪把该预算与 \(\pi_{\text{old}}\) 线性绑定，从结构上饿死了那些正确但低置信的推理路径。</li>
      <li><strong>Unbounded Positive Asymmetric Optimization (UP)</strong> 对正优势用 stop-gradient <strong>自锚定比值</strong> 替换 IS 比值，从而还原出稳定、无裁剪的 REINFORCE 梯度；对负优势则保留标准裁剪作为安全阀。</li>
      <li>UP 是一个即插即用的目标，可实例化为 <strong>UP-DAPO</strong>、<strong>UP-GRPO</strong> 与 <strong>UP-GSPO</strong>，并在 DAPO、GSPO、GRPO，以及 dense / MoE / 视觉语言模型、语言与多模态数据上全面提升准确率与探索能力。</li>
    </ul>

  </div>

  <h2 id="section">试一试：裁剪如何抑制探索？</h2>

  <p>下方的 <a href="#fig-1-zh">图 1</a> 是一张交互式地图，绘制了一个 token 在梯度被裁剪之前所能获得的更新预算，横轴为当前策略概率 \(\pi_\theta\)，纵轴为行为策略概率 \(\pi_{\text{old}}\)。在正优势 (\(\hat{A} &gt; 0\)) 下把 <strong>方法</strong> 在 DAPO 与 UP-DAPO 之间切换，也可以查看非正优势区间 (\(\hat{A} \le 0\))，拖动 \(\epsilon_{\text{high}}\)、\(\epsilon_{\text{low}}\)、\(c\)，并把鼠标移到任意位置读取精确的容量值。核心对比在于：DAPO 通过一个很窄的带把预算与 \(\pi_{\text{old}}\) 绑定，而 UP-DAPO 把预算放大为完整的 \(1 - \pi_\theta\)，与 \(\pi_{\text{old}}\) 无关。</p>

  <div id="fig-1-zh" class="cap-explorer" data-lang="zh">
  <div class="cap-panel">
    <div class="cap-controls">
      <div class="cap-seg-row">
        <div class="cap-seg-group" data-group="method">
          <span class="cap-seg-title">方法</span>
          <div class="cap-seg" data-seg="method">
            <button type="button" class="cap-seg-btn active" data-val="dapo">DAPO</button>
            <button type="button" class="cap-seg-btn" data-val="up">UP-DAPO</button>
          </div>
        </div>
        <div class="cap-seg-group" data-group="sign">
          <span class="cap-seg-title">优势</span>
          <div class="cap-seg" data-seg="sign">
            <button type="button" class="cap-seg-btn active" data-val="pos">A &gt; 0</button>
            <button type="button" class="cap-seg-btn" data-val="neg">A &le; 0</button>
          </div>
        </div>
      </div>
      <div class="cap-slider-row" data-param-row="ehigh">
        <span class="cap-slider-name">&epsilon;<sub>high</sub></span>
        <input type="range" class="cap-slider" data-param="ehigh" min="0" max="1" step="0.01" value="0.28" />
        <span class="cap-slider-val" data-val="ehigh">0.28</span>
      </div>
      <div class="cap-slider-row" data-param-row="elow">
        <span class="cap-slider-name">&epsilon;<sub>low</sub></span>
        <input type="range" class="cap-slider" data-param="elow" min="0" max="0.9" step="0.01" value="0.2" />
        <span class="cap-slider-val" data-val="elow">0.20</span>
      </div>
      <div class="cap-slider-row" data-param-row="c">
        <span class="cap-slider-name">c</span>
        <input type="range" class="cap-slider" data-param="c" min="1" max="5" step="0.1" value="3" />
        <span class="cap-slider-val" data-val="c">3.0</span>
      </div>
      <p class="cap-hover" data-out="hover">将鼠标移到图上，即可读取任意 (&pi;<sub>&theta;</sub>, &pi;<sub>old</sub>) 处的 Cap。</p>
    </div>
    <div class="cap-plot-wrap">
      <canvas class="cap-canvas" width="760" height="700" role="img" aria-label="(pi_theta, pi_old) 平面上的概率容量热图"></canvas>
    </div>
  </div>
  <p class="cap-caption" data-out="caption"></p>
</div>
  <p class="fig-caption">图 1. 交互式概率容量图（即本文的 Figure 1）。颜色编码更新预算 Cap，横轴为当前策略概率 &pi;<sub>&theta;</sub>，纵轴为行为策略概率 &pi;<sub>old</sub>。对正优势，DAPO 把 Cap 限制在由 &pi;<sub>&theta;</sub> = (1 + &epsilon;<sub>high</sub>)&pi;<sub>old</sub> 界定的狭窄带内，而 UP-DAPO 把它放大为完整的 1 &minus; &pi;<sub>&theta;</sub>，与 &pi;<sub>old</sub> 无关；对非正优势，两种方法共享同一个被裁剪的楔形区。</p>

  <h2 id="section-1">背景</h2>

  <h3 id="reinforce--grpodapo--gspo">从 REINFORCE 到 GRPO、DAPO 与 GSPO</h3>

  <p>RL 已成为激发 LLM 复杂推理能力的标准范式。原始的 REINFORCE 目标严格 on-policy，其梯度在数学上是稳定的：</p>

\[\nabla_\theta J_{\text{REINFORCE}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_\theta}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>REINFORCE 稳定但样本效率低，因为每条轨迹在一步更新后即被丢弃。为了在同一批采样数据上进行多步优化，GRPO 与 DAPO 引入 <strong>重要性采样 (IS)</strong>，用历史策略 \(\pi_{\text{old}}\) 采样并通过如下比值来估计当前策略 \(\pi_\theta\)：</p>

\[r_{i,t}(\theta) = \frac{\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})}{\pi_{\text{old}}(o_{i,t} \mid q, o_{i,&lt;t})}.\]

  <p>为防止该比值爆炸，GRPO 通过裁剪把它约束在信任域 \([1 - \epsilon, 1 + \epsilon]\) 内。DAPO 进一步将上下界解耦为 \((\epsilon_{\text{low}}, \epsilon_{\text{high}})\) 并去掉 KL 惩罚，因此完全依赖裁剪来权衡稳定与探索。GSPO 则转向 <strong>序列级</strong> 比值，采用整条回复的长度归一化似然：</p>

\[s_i(\theta) = \left( \frac{\pi_\theta(o_i \mid q)}{\pi_{\text{old}}(o_i \mid q)} \right)^{\frac{1}{|o_i|}} = \exp\!\left( \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \big( \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) - \log \pi_{\text{old}}(o_{i,t} \mid q, o_{i,&lt;t}) \big) \right).\]

  <p>这些方法都把 \(\pi_{\text{old}}\) 留在分母中，也都依赖裁剪。正是这一共同结构催生了下面的两难。</p>

  <h3 id="cap">概率容量 (Cap)</h3>

  <p>为精确刻画裁剪的代价，我们把 <strong>概率容量 (Probability Capacity, Cap)</strong> 定义为：对正优势 token (\(\hat{A} &gt; 0\))，在梯度被截断前 \(\pi_\theta\) 所能增大的最大幅度；对非正优势 token (\(\hat{A} \le 0\))，则为所能减小的最大幅度。Cap 就是一个 token 相对 \(\pi_{\text{old}}\) 用于探索的有效 <strong>预算</strong>。<a href="#fig-1-zh">图 1</a> 直接绘制了这一预算，而本文其余部分讲的正是 UP 如何把它放大。</p>

  <h2 id="section-2">动机</h2>

  <p>IS-based RL 夹在两种失效模式之间：更新过猛（纯 IS）会触发不稳定；约束过严（裁剪）会抑制探索。我们逐一分析。</p>

  <h3 id="section-3">困境一：重要性采样导致训练不稳定</h3>

  <p>无裁剪的 IS 目标用比值加权优势，\(J_{\text{IS}}(\theta) = \mathbb{E}[\hat{A}\, r_{i,t}(\theta)]\)，其梯度为：</p>

\[\nabla_\theta J_{\text{IS}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \hat{A}\, r_{i,t}(\theta)\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>与 REINFORCE 梯度对比，问题一目了然：IS 梯度被 \(r_{i,t}(\theta)\) 显式缩放。对一条稀有的高回报推理路径，其行为概率 \(\pi_{\text{old}}\) 极小，只要当前策略略有提升，该比值便会爆炸。这种病态缩放会破坏稳定的表征，使训练发散，这正是裁剪被视为不可或缺的原因。</p>

  <h3 id="section-4">困境二：裁剪抑制探索</h3>

  <p>对正优势，裁剪后的目标为 \(J_{\text{IS+CLIP}}(\theta) = \min\!\big[r_{i,t}(\theta), 1 + \epsilon\big]\hat{A}\)，一旦比值越过信任域上界，其梯度立即归零。映射到绝对概率空间，策略被上界约束为 \(\pi_\theta \le (1 + \epsilon_{\text{high}})\pi_{\text{old}}\)，于是剩余预算服从如下分段 Cap：</p>

\[\mathrm{Cap}(\pi_\theta, \pi_{\text{old}}) =
\begin{cases}
\min\!\big(1,\, (1 + \epsilon_{\text{high}})\pi_{\text{old}}\big) - \pi_\theta &amp; \text{if } \pi_\theta &lt; (1 + \epsilon_{\text{high}})\pi_{\text{old}}, \\[4pt]
0 &amp; \text{if } \pi_\theta \ge (1 + \epsilon_{\text{high}})\pi_{\text{old}}.
\end{cases}\]

  <p>这暴露出一个结构性瓶颈：预算 <strong>线性依赖于 \(\pi_{\text{old}}\)</strong>。对一个低似然的推理 token，\(\pi_{\text{old}} = 0.01\)，标准的 \(\epsilon_{\text{high}} = 0.28\) 只允许绝对概率增大区区 \(0.0028\)。一旦 \(\pi_\theta\) 达到 \(0.0128\)，容量便降为零，token 进入 Upper Clip 区间，即便其优势极高，梯度也被抹除。在 <a href="#fig-1-zh">图 1</a> 中把方法设为 DAPO，观察地图底部 \(\pi_{\text{old}}\) 很小的区域，即可亲眼看到这一狭窄的预算。从结构上看，这抑制了探索，也让有潜力的长尾轨迹无从被发现。</p>

  <div class="callout">
    <p><strong>核心问题。</strong> 如何在 RL 中最大化模型探索的同时防止训练不稳定？更新过猛会破坏稳定，保守裁剪会饿死探索。我们需要一种能同时跳出这两者的形式化方法。</p>
  </div>

  <h2 id="section-5">方法</h2>

  <p>UP 通过两步数学操作来化解两难：用 stop-gradient 把 \(\pi_{\text{old}}\) 替换为当前策略 \(\pi_\theta\)，并按优势的符号非对称地路由梯度。</p>

  <h3 id="section-6">面向正优势的无界目标</h3>

  <p>对正确 rollout (\(\hat{A} &gt; 0\))，我们用基于 stop-gradient 算子 \(\mathrm{sg}(\cdot)\) 构造的 <strong>自锚定比值</strong> \(\tilde{r}_{i,t}(\theta)\) 替换 IS 比值（式 12）：</p>

\[J^{+}_{\text{UP}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \frac{\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})}{\mathrm{sg}\!\big(\pi_\theta(o_{i,t} \mid q, o_{i,&lt;t})\big)} \right], \qquad \hat{A} &gt; 0.\]

  <p>反向传播时 \(\mathrm{sg}(\pi_\theta)\) 是常数标量，但其前向取值恰等于 \(\pi_\theta\)。应用对数导数技巧 \(\nabla x / x = \nabla \log x\)，目标坍缩为（式 13）：</p>

\[\nabla_\theta J^{+}_{\text{UP}}(\theta) = \mathbb{E}_{q \sim Q,\, o \sim \pi_{\text{old}}}\!\left[ \sum_{t=1}^{|o|} \hat{A}\, \nabla_\theta \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right].\]

  <p>这是一个深刻的简化：优化自锚定比值在数学上等价于最大化 <strong>REINFORCE</strong> 目标。通过把策略锚定到 \(\pi_\theta\) 而非 \(\pi_{\text{old}}\)，UP 从根源上消除了困境一中的 IS 不稳定，其 Cap 也不再受历史约束，\(\mathrm{Cap} = 1 - \pi_\theta\)。在 <a href="#fig-1-zh">图 1</a> 中把方法切换为 UP-DAPO 并取 \(\hat{A} &gt; 0\)：狭窄的裁剪带会扩展为只依赖 \(\pi_\theta\) 的完整预算。</p>

  <h3 id="section-7">为何非对称：负优势保留裁剪</h3>

  <p>无界机制被有意限制在正确 rollout 上。对错误 rollout，优势为负，会反转梯度方向；在此处施加无界更新等于做激进的梯度上升，会破坏原有表征。因此 UP 对 \(\hat{A} \le 0\) 保留标准裁剪，此时 DAPO 与 UP-DAPO 共享一个由下界裁剪与 dual clip 边界决定的相同 Cap（见 <a href="#fig-1-zh">图 1</a> 中的 \(\hat{A} \le 0\) 视图）：</p>

\[\mathrm{Cap}(\pi_\theta, \pi_{\text{old}}) =
\begin{cases}
\pi_\theta - (1 - \epsilon_{\text{low}})\pi_{\text{old}} &amp; \text{if } (1 - \epsilon_{\text{low}})\pi_{\text{old}} \le \pi_\theta \le c\,\pi_{\text{old}}, \\[4pt]
0 &amp; \text{if } \pi_\theta &lt; (1 - \epsilon_{\text{low}})\pi_{\text{old}} \quad (\text{Lower Clip}), \\[4pt]
0 &amp; \text{if } \pi_\theta &gt; c\,\pi_{\text{old}} \quad (\text{Dual Clip}).
\end{cases}\]

  <p>这正是 UP 的关键：对正确 rollout 放开探索，对错误 rollout 守住安全。</p>

  <h3 id="up-gxpo">UP-GxPO：一个插件，三种实例化</h3>

  <p>由于只改写正优势分支，UP 可插入任意 group-based 策略优化器。token 级的 <strong>UP-DAPO</strong> 把无界正目标与 DAPO 对负优势的裁剪目标组合（式 14）：</p>

\[J_{\text{UP-DAPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{\sum_i |o_i|} \sum_{i}\sum_{t}
\begin{cases}
\hat{A}_{i,t}\, \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) &amp; \text{if } \hat{A}_{i,t} &gt; 0, \\[4pt]
\min\!\big( r_{i,t}(\theta)\hat{A}_{i,t},\, \mathrm{clip}(r_{i,t}(\theta), 1 - \epsilon_{\text{low}}, 1 + \epsilon_{\text{high}})\hat{A}_{i,t} \big) &amp; \text{if } \hat{A}_{i,t} \le 0.
\end{cases}
\right].\]

  <p>同一原理给出 <strong>UP-GRPO</strong>，其负优势分支保留 GRPO 的对称裁剪与 KL 惩罚（式 15）：</p>

\[J_{\text{UP-GRPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{G} \sum_{i} \frac{1}{|o_i|} \sum_{t}
\begin{cases}
\hat{A}_i\, \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) - \beta D_{\text{KL}}(\pi_\theta \,\|\, \pi_{\text{ref}}) &amp; \text{if } \hat{A}_i &gt; 0, \\[4pt]
\min\!\big( r_{i,t}(\theta)\hat{A}_i,\, \mathrm{clip}(r_{i,t}(\theta), 1 - \epsilon, 1 + \epsilon)\hat{A}_i \big) - \beta D_{\text{KL}}(\pi_\theta \,\|\, \pi_{\text{ref}}) &amp; \text{if } \hat{A}_i \le 0.
\end{cases}
\right].\]

  <p>最后，UP 扩展到序列级得到 <strong>UP-GSPO</strong>，其正优势分支可证明地退化为长度归一化的 REINFORCE 梯度（式 16）：</p>

\[J_{\text{UP-GSPO}}(\theta) = \mathbb{E}\!\left[ \frac{1}{G} \sum_{i}
\begin{cases}
\hat{A}_i \left( \frac{1}{|o_i|} \sum_{t=1}^{|o_i|} \log \pi_\theta(o_{i,t} \mid q, o_{i,&lt;t}) \right) &amp; \text{if } \hat{A}_i &gt; 0, \\[4pt]
\min\!\big( s_i(\theta)\hat{A}_i,\, \mathrm{clip}(s_i(\theta), 1 - \epsilon, 1 + \epsilon)\hat{A}_i \big) &amp; \text{if } \hat{A}_i \le 0.
\end{cases}
\right].\]

  <div class="callout">
    <p><strong>一句话总结。</strong> UP 是一个即插即用的目标：它把任意 GxPO 算法的正优势分支替换为 stop-gradient、无裁剪、等价于 REINFORCE 的更新，而负优势分支原封不动，充当安全阀。</p>
  </div>

  <h2 id="section-8">实验</h2>

  <p>我们在 dense LLM（Qwen3-14B-Base、Qwen3-8B）、MoE 模型（Qwen3-30B-A3B-Base）以及视觉语言模型（Qwen3-VL-8B-Instruct）上评估 UP，实现基于 verl 框架。在所有 setting 上，UP 都能在保持训练稳定的同时提升准确率与探索能力。</p>

  <h3 id="up-dapo-">UP-DAPO 的性能、探索与稳定性分析</h3>

  <p>在 Qwen3-14B-Base 上用 DAPO-17K-MATH 训练并在 AIME24 评估，UP-DAPO 全面优于 DAPO。如 <a href="#fig-2-zh">图 2</a> 所示，峰值 Avg@32 从 \(47.71\) 提升至 \(51.15\)，Maj@32 从 \(58.36\) 提升至 \(60.88\)。<a href="#fig-3-zh">图 3</a> 揭示了增益来源：始终更高的生成熵，加上更高的 Best@32（从 \(80.49\) 提升至 \(81.79\)），共同证实移除 \(\pi_{\text{old}}\) 锚点确实放大了探索能力。更关键的是，<a href="#fig-4-zh">图 4</a> 表明 UP-DAPO 的梯度范数与 KL 散度与 DAPO 相当甚至略低，说明这份额外的探索并未以牺牲稳定为代价。</p>

  <div id="fig-2-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/avg32_plot.png" alt="AIME24 上的 Avg@32 准确率" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Avg@32</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/maj32_plot.png" alt="AIME24 上的 Maj@32 准确率" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) Maj@32</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 2. DAPO 与 UP-DAPO 在 Qwen3-14B-Base 训练过程中的性能对比：(a) AIME24 上的 Avg@32 与 (b) Maj@32 准确率。UP-DAPO 的峰值 Avg@32 为 51.15，DAPO 为 47.71；峰值 Maj@32 为 60.88，DAPO 为 58.36。</p>

  <div id="fig-3-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/entropy_plot.png" alt="DAPO-17K-MATH 上的生成熵" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) 熵</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/best32_plot.png" alt="AIME24 上的 Best@32 准确率" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) Best@32</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 3. UP-DAPO 的探索能力：(a) DAPO-17K-MATH 上生成概率的熵，(b) AIME24 上的 Best@32 准确率。UP-DAPO 维持更高的熵，并把峰值 Best@32 提升至 81.79，DAPO 为 80.49。</p>

  <div id="fig-4-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grad_norm_plot.png" alt="DAPO-17K-MATH 上的梯度范数" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) 梯度范数</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/kl_plot.png" alt="与参考模型之间的 KL 散度" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL 散度</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 4. UP-DAPO 的训练稳定性：(a) 梯度范数，(b) DAPO-17K-MATH 上活跃策略与参考模型之间的 KL 散度。两者都与 DAPO 高度贴合，说明额外的探索不会破坏训练稳定。</p>

  <h3 id="up-dapo--1">UP-DAPO 的消融研究</h3>

  <p>两项消融进一步锁定了两个设计各自的必要性。如 <a href="#fig-5-zh">图 5</a> 所示，仅仅把 DAPO 的上界裁剪放宽到无穷、同时仍保留 \(\pi_{\text{old}}\) 锚点，前期尚能稳定，但在 80 步后爆炸，梯度范数飙升至 \(10^{13}\)；这说明真正让无界更新变得安全的是自锚定比值，而非单纯放宽边界。若把无界更新对称地施加到正负优势两侧，训练在 25 步内即崩溃，证明负优势分支上的裁剪是不可或缺的安全阀。</p>

  <div id="fig-5-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grad_norm_log_plot.png" alt="对数坐标下的梯度范数" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) 梯度范数（对数坐标）</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/kl_log_plot.png" alt="对数坐标下的 KL 散度" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL 散度（对数坐标）</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 5. DAPO、DAPO（\(\epsilon_{\text{high}} = \infty\)）、REINFORCE（off-policy）与 UP-DAPO 在 Qwen3-14B-Base 上的训练稳定性：(a) 梯度范数，(b) KL 散度，均为对数坐标。DAPO（\(\epsilon_{\text{high}} = \infty\)）在约 80 步后爆炸至 \(10^{13}\)，对称无界变体在 25 步内崩溃，而 UP-DAPO 始终稳定。</p>

  <h3 id="rl-">与其他 RL 基线的比较</h3>

  <p>在 Liu et al. 的统一协议下，我们用 Qwen3-8B 在 MATH（难度 3 至 5）上训练，并在五个推理基准上评估 Pass@1。如 <a href="#tab-1-zh">表 1</a> 所示，UP-GRPO 取得最高平均准确率 \(61.31\%\)，比此前最强基线 GSPO（\(60.15\%\)）高出 \(1.16\%\) 的绝对值。UP-GRPO 在五个单项基准中的四个上排名第一或并列第一，在 OlympiadBench 上也极具竞争力，仅次于 ASPO。跨越不同难度基准的稳定增益表明，无界正更新是对 GxPO 家族的普遍改进，而非针对某个基准的特例。<a href="#fig-6-zh">图 6</a> 为这些下游增益提供了解释：UP-GRPO 的策略熵在整段训练中持续上升，而多数基线出现熵坍缩；其 KL 散度也维持在十二种方法中的最低之列。</p>

  <div id="tab-1-zh" class="results-table">

    <table>
      <thead>
        <tr>
          <th style="text-align: left">方法</th>
          <th style="text-align: center">AIME24</th>
          <th style="text-align: center">AMC23</th>
          <th style="text-align: center">MATH500</th>
          <th style="text-align: center">Minerva</th>
          <th style="text-align: center">OlympiadBench</th>
          <th style="text-align: center">平均</th>
        </tr>
      </thead>
      <tbody>
        <tr>
          <td style="text-align: left">GRPO</td>
          <td style="text-align: center">35.73</td>
          <td style="text-align: center">75.00</td>
          <td style="text-align: center">86.00</td>
          <td style="text-align: center">30.88</td>
          <td style="text-align: center">51.34</td>
          <td style="text-align: center">55.79</td>
        </tr>
        <tr>
          <td style="text-align: left">Dr. GRPO</td>
          <td style="text-align: center">33.33</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">85.80</td>
          <td style="text-align: center">30.15</td>
          <td style="text-align: center">51.19</td>
          <td style="text-align: center">57.09</td>
        </tr>
        <tr>
          <td style="text-align: left">CISPO</td>
          <td style="text-align: center">38.02</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">86.60</td>
          <td style="text-align: center">29.04</td>
          <td style="text-align: center">55.65</td>
          <td style="text-align: center">59.36</td>
        </tr>
        <tr>
          <td style="text-align: left">DPPO</td>
          <td style="text-align: center">40.10</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">86.20</td>
          <td style="text-align: center">30.51</td>
          <td style="text-align: center">53.27</td>
          <td style="text-align: center">59.52</td>
        </tr>
        <tr>
          <td style="text-align: left">GMPO</td>
          <td style="text-align: center">37.50</td>
          <td style="text-align: center">87.50</td>
          <td style="text-align: center">87.00</td>
          <td style="text-align: center">31.25</td>
          <td style="text-align: center">55.06</td>
          <td style="text-align: center">59.66</td>
        </tr>
        <tr>
          <td style="text-align: left">GSPO</td>
          <td style="text-align: center">40.52</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">88.20</td>
          <td style="text-align: center">31.25</td>
          <td style="text-align: center">55.80</td>
          <td style="text-align: center">60.15</td>
        </tr>
        <tr>
          <td style="text-align: left">SAPO</td>
          <td style="text-align: center">39.90</td>
          <td style="text-align: center">82.50</td>
          <td style="text-align: center">87.20</td>
          <td style="text-align: center">30.88</td>
          <td style="text-align: center">55.65</td>
          <td style="text-align: center">59.23</td>
        </tr>
        <tr>
          <td style="text-align: left">REINFORCE++</td>
          <td style="text-align: center">20.52</td>
          <td style="text-align: center">62.50</td>
          <td style="text-align: center">78.80</td>
          <td style="text-align: center">29.78</td>
          <td style="text-align: center">42.26</td>
          <td style="text-align: center">46.77</td>
        </tr>
        <tr>
          <td style="text-align: left">RLOO</td>
          <td style="text-align: center">31.67</td>
          <td style="text-align: center">80.00</td>
          <td style="text-align: center">85.20</td>
          <td style="text-align: center">28.68</td>
          <td style="text-align: center">50.60</td>
          <td style="text-align: center">55.23</td>
        </tr>
        <tr>
          <td style="text-align: left">W-REINFORCE</td>
          <td style="text-align: center">35.52</td>
          <td style="text-align: center">80.00</td>
          <td style="text-align: center">85.80</td>
          <td style="text-align: center">30.15</td>
          <td style="text-align: center">53.27</td>
          <td style="text-align: center">56.95</td>
        </tr>
        <tr>
          <td style="text-align: left">ASPO</td>
          <td style="text-align: center">37.50</td>
          <td style="text-align: center">85.00</td>
          <td style="text-align: center">87.60</td>
          <td style="text-align: center">29.78</td>
          <td style="text-align: center"><strong>58.48</strong></td>
          <td style="text-align: center">59.67</td>
        </tr>
        <tr>
          <td style="text-align: left"><strong>UP-GRPO (Ours)</strong></td>
          <td style="text-align: center"><strong>41.04</strong></td>
          <td style="text-align: center"><strong>87.50</strong></td>
          <td style="text-align: center"><strong>88.40</strong></td>
          <td style="text-align: center"><strong>31.25</strong></td>
          <td style="text-align: center">58.33</td>
          <td style="text-align: center"><strong>61.31</strong></td>
        </tr>
      </tbody>
    </table>

  </div>
  <p class="fig-caption">表 1. UP-GRPO 与十一个 RL 基线在 AIME24、AMC23、MATH500、Minerva、OlympiadBench 上的对比（Pass@1，%），使用 Qwen3-8B 在 MATH（难度 3 至 5）上训练。每列最优用<strong>粗体</strong>。</p>

  <div id="fig-6-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px 8px; row-gap: 0;">
  <div class="fig-legend" style="margin-top: 0; margin-bottom: -4px;">
    <img src="/images/blog/up/grpo_family_legend.png" alt="图例：UP-GRPO 与十一个 RL 基线" />
  </div>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grpo_family_entropy_plot.png" alt="UP-GRPO 与各基线的策略熵" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) 熵</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/grpo_family_kl_plot.png" alt="UP-GRPO 与各基线的 KL 散度" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL 散度</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 6. UP-GRPO 与十一个 RL 基线在 Qwen3-8B 训练过程中的探索能力与训练稳定性：(a) 熵，(b) MATH（难度 3 至 5）上活跃策略与参考模型之间的 KL 散度。多数基线出现熵坍缩，而 UP-GRPO 的熵持续上升，且 KL 散度维持在最低之列。</p>

  <h3 id="up-">UP 在算法、架构与模态上的通用性</h3>

  <p>UP 是通用插件，而非 token 级的技巧。在 <strong>MoE</strong> 模型 Qwen3-30B-A3B-Base 上，<a href="#fig-7-zh">图 7</a> 显示 UP-GSPO 把 AIME24 的峰值 Avg@32 从 GSPO 的 \(52.71\%\) 提升至 \(55.73\%\)，绝对提升 \(3.02\%\)，同时 KL 散度与基线几乎一致。在 <strong>视觉语言</strong> 模型 Qwen3-VL-8B-Instruct 上用 Geometry3K 训练，<a href="#fig-8-zh">图 8</a> 显示 UP-GRPO 把准确率从 GRPO 的 \(59.30\%\) 提升至 \(62.60\%\)，绝对提升 \(3.30\%\)，同样没有引入任何额外不稳定。这两个 setting 共同表明，无论优化粒度（token 级到序列级）、模型架构（dense 到 MoE）还是模态（语言到多模态），UP 都能化解探索与稳定的两难。</p>

  <div id="fig-7-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/gspo_avg32_plot.png" alt="GSPO 与 UP-GSPO 在 AIME24 上的 Avg@32 准确率" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) Avg@32</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/gspo_kl_plot.png" alt="GSPO 与 UP-GSPO 的 KL 散度" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL 散度</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 7. GSPO 与 UP-GSPO 在 MoE 模型 Qwen3-30B-A3B-Base 训练过程中的性能与稳定性：(a) AIME24 上的 Avg@32 准确率，(b) DAPO-17K-MATH 上的 KL 散度。UP-GSPO 把峰值 Avg@32 从 52.71 提升至 55.73，且 KL 轨迹几乎一致。</p>

  <div id="fig-8-zh" class="fig-grid" style="grid-template-columns: minmax(0, 1fr) minmax(0, 1fr); max-width: 94%; margin: 1.2em auto 0.1em; padding: 6px 12px; row-gap: 0;">
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/vlm_avg32_plot.png" alt="GRPO 与 UP-GRPO 在 Geometry3K 上的准确率" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(a) 准确率</figcaption>
  </figure>
  <figure style="min-width: 0; margin: 0;">
    <img src="/images/blog/up/vlm_kl_plot.png" alt="GRPO 与 UP-GRPO 在 Geometry3K 上的 KL 散度" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" />
    <figcaption style="white-space: normal; margin: 0;">(b) KL 散度</figcaption>
  </figure>
</div>
  <p class="fig-caption">图 8. GRPO 与 UP-GRPO 在视觉语言模型 Qwen3-VL-8B-Instruct（Geometry3K）训练过程中的性能与稳定性：(a) Geometry3K 测试集上的准确率，(b) KL 散度。UP-GRPO 把峰值准确率从 59.30 提升至 62.60，且未引入额外不稳定。</p>

  <h2 id="bibtex-zh">BibTeX</h2>

  <pre class="bibtex-block"><code>@misc{fan2026upunboundedpositiveasymmetric,
      title={UP: Unbounded Positive Asymmetric Optimization for Breaking the Exploration-Stability Dilemma}, 
      author={Chongyu Fan and Pengfei Liu and Jingjia Huang and Sijia Liu and Yi Lin},
      year={2026},
      eprint={2607.06987},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2607.06987}, 
}
</code></pre>

</div>

<script>
(function () {
  var REDS = [[255,245,240],[254,224,210],[252,146,114],[222,45,38],[103,0,13]];
  var BLUES = [[247,251,255],[198,219,239],[107,174,214],[33,113,181],[8,48,107]];
  var C_RED = '#e8110b', C_BLUE = '#1414e0', C_PURPLE = '#8e1ca8';
  var C_DIAG = '#8b95a3', C_AXIS = '#94a3b8', C_TICK = '#94a3b8', C_TXT = '#475569';
  var C_CLIPBASE = [244, 244, 245], C_HATCH = 'rgba(120,130,145,0.42)';

  // fixed backing-store geometry (independent of clientWidth so hidden ZH block renders)
  var W = 760, H = 700;
  var PADL = 104, PADR = 128, PADT = 30, PADB = 124;
  var PW = W - PADL - PADR;   // 528
  var PH = H - PADT - PADB;   // 546
  var X0 = PADL, Y0 = PADT;

  function gx(pt) { return X0 + pt * PW; }
  function gy(po) { return Y0 + (1 - po) * PH; }
  function ramp(stops, t) {
    t = t < 0 ? 0 : (t > 1 ? 1 : t);
    var s = t * (stops.length - 1), i = Math.floor(s);
    if (i >= stops.length - 1) return stops[stops.length - 1];
    var f = s - i, a = stops[i], b = stops[i + 1];
    return [a[0] + (b[0] - a[0]) * f, a[1] + (b[1] - a[1]) * f, a[2] + (b[2] - a[2]) * f];
  }
  function fmt(v) { return (Math.abs(v) < 0.0005 ? 0 : v).toFixed(3); }

  // ---- rich text with real subscripts (canvas cannot render HTML <sub>) ----
  // A "rich" string is an array of runs: [{t:'π'}, {t:'old', sub:true}, ...]
  var PI_TH = [{ t: '\u03c0' }, { t: '\u03b8', sub: true }];
  var PI_OLD = [{ t: '\u03c0' }, { t: 'old', sub: true }];
  function fontPx(font) { var m = font.match(/(\d+(?:\.\d+)?)px/); return m ? parseFloat(m[1]) : 12; }
  function subFontOf(font) {
    var sz = fontPx(font);
    return font.replace(/(\d+(?:\.\d+)?)px/, (Math.round(sz * 0.66 * 10) / 10) + 'px');
  }
  function toSegs(x) { return typeof x === 'string' ? [{ t: x }] : x; }
  function measureRich(ctx, segs, font) {
    var sub = subFontOf(font), w = 0;
    segs.forEach(function (s) { ctx.font = s.sub ? sub : font; w += ctx.measureText(s.t).width; });
    return w;
  }
  function drawRich(ctx, segs, x, y, font, color) {
    var sub = subFontOf(font), drop = fontPx(font) * 0.22, cx = x;
    ctx.textAlign = 'left';
    ctx.textBaseline = 'middle';
    ctx.fillStyle = color;
    segs.forEach(function (s) {
      ctx.font = s.sub ? sub : font;
      ctx.fillText(s.t, cx, s.sub ? y + drop : y);
      cx += ctx.measureText(s.t).width;
    });
  }
  function drawRichCentered(ctx, segs, cx, y, font, color) {
    drawRich(ctx, segs, cx - measureRich(ctx, segs, font) / 2, y, font, color);
  }

  // Cap(pi_theta, pi_old) for the current mode
  function capAt(pt, po, st) {
    if (st.sign === 'pos') {
      if (st.method === 'up') return Math.max(0, 1 - pt);
      var bnd = Math.min(1, po * (1 + st.ehigh));
      return Math.max(0, bnd - pt);
    }
    var hi = pt / (1 - st.elow); // pi_old upper bound (above -> Lower Clip)
    var lo = pt / st.c;          // pi_old lower bound (below -> Dual Clip)
    if (po > hi || po < lo) return 0;
    return Math.max(0, pt - (1 - st.elow) * po);
  }
  function maxCap(st) {
    if (st.sign === 'neg') return Math.max(1e-6, 1 - (1 - st.elow) / st.c);
    return 1;
  }

  function roundRect(ctx, x, y, w, h, r) {
    ctx.beginPath();
    ctx.moveTo(x + r, y);
    ctx.arcTo(x + w, y, x + w, y + h, r);
    ctx.arcTo(x + w, y + h, x, y + h, r);
    ctx.arcTo(x, y + h, x, y, r);
    ctx.arcTo(x, y, x + w, y, r);
    ctx.closePath();
  }
  function boxLabel(ctx, cx, cy, lines, color, font) {
    lines = lines.map(toSegs);
    var lh = fontPx(font) + 12, pad = 13, wmax = 0;
    lines.forEach(function (ln) { wmax = Math.max(wmax, measureRich(ctx, ln, font)); });
    var bw = wmax + pad * 2, bh = lines.length * lh + pad * 2 - 4;
    var bx = cx - bw / 2, by = cy - bh / 2;
    bx = Math.max(X0 + 2, Math.min(X0 + PW - bw - 2, bx));
    by = Math.max(Y0 + 2, Math.min(Y0 + PH - bh - 2, by));
    ctx.fillStyle = 'rgba(255,255,255,0.92)';
    ctx.strokeStyle = 'rgba(203,213,225,0.95)';
    ctx.lineWidth = 1;
    roundRect(ctx, bx, by, bw, bh, 8);
    ctx.fill(); ctx.stroke();
    for (var i = 0; i < lines.length; i++) {
      drawRichCentered(ctx, lines[i], bx + bw / 2, by + pad + lh / 2 + i * lh - 1, font, color);
    }
  }
  function hatch(ctx, poly) {
    ctx.save();
    ctx.beginPath();
    poly.forEach(function (p, i) {
      var X = gx(p[0]), Y = gy(p[1]);
      if (i === 0) ctx.moveTo(X, Y); else ctx.lineTo(X, Y);
    });
    ctx.closePath();
    ctx.clip();
    ctx.strokeStyle = C_HATCH;
    ctx.lineWidth = 0.9;
    ctx.beginPath();
    var step = 13, x;
    for (x = X0 - PH; x < X0 + PW; x += step) {
      ctx.moveTo(x, Y0 + PH); ctx.lineTo(x + PH, Y0);
    }
    for (x = X0; x < X0 + PW + PH; x += step) {
      ctx.moveTo(x, Y0 + PH); ctx.lineTo(x - PH, Y0);
    }
    ctx.stroke();
    ctx.restore();
  }
  function seg(ctx, p0, p1, color, width, dash) {
    ctx.save();
    ctx.strokeStyle = color;
    ctx.lineWidth = width;
    ctx.lineCap = 'round';
    ctx.setLineDash(dash || []);
    ctx.beginPath();
    ctx.moveTo(gx(p0[0]), gy(p0[1]));
    ctx.lineTo(gx(p1[0]), gy(p1[1]));
    ctx.stroke();
    ctx.restore();
  }

  function draw(cv, st, lang) {
    var ctx = cv.getContext('2d');
    ctx.clearRect(0, 0, W, H);
    ctx.fillStyle = '#ffffff';
    ctx.fillRect(0, 0, W, H);

    var stops = st.sign === 'pos' ? REDS : BLUES;
    var mx = maxCap(st);

    // heatmap
    var img = ctx.createImageData(PW, PH), d = img.data;
    for (var yy = 0; yy < PH; yy++) {
      var po = 1 - (yy + 0.5) / PH;
      for (var xx = 0; xx < PW; xx++) {
        var pt = (xx + 0.5) / PW;
        var cap = capAt(pt, po, st);
        var idx = (yy * PW + xx) * 4;
        if (cap > 1e-9) {
          var col = ramp(stops, cap / mx);
          d[idx] = col[0]; d[idx + 1] = col[1]; d[idx + 2] = col[2]; d[idx + 3] = 255;
        } else {
          d[idx] = C_CLIPBASE[0]; d[idx + 1] = C_CLIPBASE[1]; d[idx + 2] = C_CLIPBASE[2]; d[idx + 3] = 255;
        }
      }
    }
    ctx.putImageData(img, X0, Y0);

    // clip-region hatching
    if (st.sign === 'pos') {
      if (st.method === 'dapo') {
        var yb = 1 / (1 + st.ehigh); // pi_old at pt=1 on red line
        hatch(ctx, [[0, 0], [1, 0], [1, yb]]);
      }
    } else {
      var xTop = 1 - st.elow;            // pt where blue line hits po=1
      hatch(ctx, [[0, 0], [xTop, 1], [0, 1]]);       // Lower Clip
      hatch(ctx, [[0, 0], [1, 0], [1, 1 / st.c]]);   // Dual Clip
    }

    // grey dashed diagonal pi_old = pi_theta
    seg(ctx, [0, 0], [1, 1], C_DIAG, 2.2, [8, 6]);

    // boundary lines + boxed labels
    var lblFont = 'italic 32px "Source Serif Pro", Georgia, serif';
    var clipFont = '600 30px Inter, "Segoe UI", sans-serif';
    if (st.sign === 'pos') {
      if (st.method === 'dapo') {
        var yb2 = 1 / (1 + st.ehigh);
        seg(ctx, [0, 0], [1, yb2], C_RED, 5, []);
        boxLabel(ctx, gx(0.5), gy(0.92),
          [[{ t: 'Cap = min(1, ' }, { t: '\u03c0' }, { t: 'old', sub: true }, { t: '(1 + ' }, { t: '\u03b5' }, { t: 'high', sub: true }, { t: ')) \u2212 ' }, { t: '\u03c0' }, { t: '\u03b8', sub: true }]],
          '#8f1a12', lblFont);
        boxLabel(ctx, gx(0.75), gy(0.24), ['Upper Clip', '(Cap = 0)'], '#334155', clipFont);
      } else {
        boxLabel(ctx, gx(0.52), gy(0.5),
          [[{ t: 'Cap = 1 \u2212 ' }, { t: '\u03c0' }, { t: '\u03b8', sub: true }]], '#8f1a12', lblFont);
      }
    } else {
      var xTop2 = 1 - st.elow;
      seg(ctx, [0, 0], [xTop2, 1], C_BLUE, 5, []);
      seg(ctx, [0, 0], [1, 1 / st.c], C_PURPLE, 4.5, [11, 6, 3, 6]);
      boxLabel(ctx, gx(0.56), gy(0.52),
        [[{ t: 'Cap = ' }, { t: '\u03c0' }, { t: '\u03b8', sub: true }, { t: ' \u2212 ' }, { t: '\u03c0' }, { t: 'old', sub: true }, { t: '(1 \u2212 ' }, { t: '\u03b5' }, { t: 'low', sub: true }, { t: ')' }]],
        '#15347a', lblFont);
      boxLabel(ctx, gx(0.24), gy(0.86), ['Lower Clip', '(Cap = 0)'], '#334155', clipFont);
      boxLabel(ctx, gx(0.8), gy(0.15), ['Dual Clip', '(Cap = 0)'], '#7a1690', clipFont);
    }

    // axes frame
    ctx.strokeStyle = C_AXIS;
    ctx.lineWidth = 1.2;
    ctx.setLineDash([]);
    ctx.strokeRect(X0, Y0, PW, PH);

    // ticks + tick labels
    var ticks = [0, 0.2, 0.4, 0.6, 0.8, 1];
    ctx.fillStyle = C_TICK;
    ctx.font = '30px Inter, "Segoe UI", sans-serif';
    ctx.textBaseline = 'alphabetic';
    ctx.textAlign = 'center';
    ticks.forEach(function (t) {
      var X = gx(t);
      ctx.beginPath(); ctx.moveTo(X, Y0 + PH); ctx.lineTo(X, Y0 + PH + 7);
      ctx.strokeStyle = C_AXIS; ctx.lineWidth = 1.2; ctx.stroke();
      ctx.fillText(t.toFixed(1), X, Y0 + PH + 38);
    });
    ctx.textAlign = 'right';
    ctx.textBaseline = 'middle';
    ticks.forEach(function (t) {
      var Y = gy(t);
      ctx.beginPath(); ctx.moveTo(X0 - 7, Y); ctx.lineTo(X0, Y);
      ctx.strokeStyle = C_AXIS; ctx.lineWidth = 1.2; ctx.stroke();
      ctx.fillText(t.toFixed(1), X0 - 14, Y);
    });

    // axis titles (with real subscripts)
    // x-axis title: big symbol + descriptive text on one line, spaced apart so they never overlap
    var axisSym = 'italic 40px "Source Serif Pro", Georgia, serif';
    var xDescFont = '24px Inter, "Segoe UI", sans-serif';
    var xDesc = lang === 'zh' ? '\uff08\u5f53\u524d\u7b56\u7565\u6982\u7387\uff09' : '(current policy probability)';
    var xSymW = measureRich(ctx, PI_TH, axisSym);
    ctx.font = xDescFont;
    var xDescW = ctx.measureText(xDesc).width;
    var xGap = 20;
    var xTitleStart = X0 + PW / 2 - (xSymW + xGap + xDescW) / 2;
    var xTitleY = H - 42;
    drawRich(ctx, PI_TH, xTitleStart, xTitleY, axisSym, C_TXT);
    ctx.fillStyle = C_TXT;
    ctx.font = xDescFont;
    ctx.textAlign = 'left';
    ctx.textBaseline = 'middle';
    ctx.fillText(xDesc, xTitleStart + xSymW + xGap, xTitleY);
    ctx.save();
    ctx.translate(24, Y0 + PH / 2);
    ctx.rotate(-Math.PI / 2);
    drawRichCentered(ctx, PI_OLD, 0, 0, axisSym, C_TXT);
    ctx.restore();

    // colorbar
    var cbx = X0 + PW + 26, cbw = 22, cbTop = Y0 + 10, cbH = PH - 20;
    var grad = ctx.createLinearGradient(0, cbTop, 0, cbTop + cbH);
    for (var g = 0; g <= 10; g++) {
      var cc = ramp(stops, 1 - g / 10);
      grad.addColorStop(g / 10, 'rgb(' + Math.round(cc[0]) + ',' + Math.round(cc[1]) + ',' + Math.round(cc[2]) + ')');
    }
    ctx.fillStyle = grad;
    ctx.fillRect(cbx, cbTop, cbw, cbH);
    ctx.strokeStyle = C_AXIS; ctx.lineWidth = 1.2;
    ctx.strokeRect(cbx, cbTop, cbw, cbH);
    ctx.fillStyle = C_TICK;
    ctx.font = '24px Inter, "Segoe UI", sans-serif';
    ctx.textAlign = 'left';
    ctx.textBaseline = 'middle';
    ctx.fillText(mx.toFixed(2), cbx + cbw + 8, cbTop);
    ctx.fillText((mx / 2).toFixed(2), cbx + cbw + 8, cbTop + cbH / 2);
    ctx.fillText('0', cbx + cbw + 8, cbTop + cbH);
    ctx.fillStyle = C_TXT;
    ctx.font = '600 26px Inter, "Segoe UI", sans-serif';
    ctx.textAlign = 'center';
    ctx.textBaseline = 'alphabetic';
    ctx.fillText('Cap', cbx + cbw / 2, cbTop - 12);
  }

  function initRoot(root) {
    if (root.dataset.capInit) return;
    root.dataset.capInit = '1';
    var lang = root.dataset.lang || 'en';
    var cv = root.querySelector('.cap-canvas');
    if (!cv) return;
    var st = { method: 'dapo', sign: 'pos', ehigh: 0.28, elow: 0.2, c: 3 };
    var vals = {};
    root.querySelectorAll('.cap-slider-val').forEach(function (v) { vals[v.getAttribute('data-val')] = v; });
    var caption = root.querySelector('[data-out="caption"]');
    var hover = root.querySelector('[data-out="hover"]');
    var hoverDefault = hover ? hover.innerHTML : '';

    function dimRows() {
      root.querySelectorAll('.cap-slider-row').forEach(function (r) {
        var p = r.getAttribute('data-param-row'), dim = false;
        if (st.sign === 'pos') {
          if (p === 'elow' || p === 'c') dim = true;
          if (p === 'ehigh' && st.method === 'up') dim = true;
        } else if (p === 'ehigh') { dim = true; }
        r.classList.toggle('is-dim', dim);
      });
      var mg = root.querySelector('.cap-seg-group[data-group="method"]');
      if (mg) {
        var off = (st.sign === 'neg');
        mg.style.opacity = off ? '0.45' : '1';
        var mseg = mg.querySelector('.cap-seg');
        if (mseg) { mseg.style.pointerEvents = off ? 'none' : 'auto'; mseg.title = off ? 'DAPO and UP-DAPO are identical for A \u2264 0' : ''; }
      }
    }

    function setCaption() {
      if (!caption) return;
      var t = '';
      if (st.sign === 'pos' && st.method === 'dapo') {
        t = lang === 'zh'
          ? 'DAPO\uff08A &gt; 0\uff09\uff1a\u9884\u7b97\u5c40\u9650\u5728\u7ea2\u7ebf <b>\u03c0<sub>\u03b8</sub> = (1+\u03b5<sub>high</sub>)\u03c0<sub>old</sub></b> \u4e0a\u65b9\u7684\u7ea2\u8272\u7a84\u5e26\u5185\uff1b\u4e0b\u65b9\u7684 Upper Clip \u533a\u57df Cap = 0\u3002\u9884\u7b97\u968f \u03c0<sub>old</sub> \u7ebf\u6027\u6536\u7f29\uff0c\u56e0\u6b64\u4f4e \u03c0<sub>old</sub> \u7684\u7a00\u6709 token \u5947\u5c11\u3002'
          : 'DAPO (A &gt; 0): the budget is confined to the red band above <b>\u03c0<sub>\u03b8</sub> = (1+\u03b5<sub>high</sub>)\u03c0<sub>old</sub></b>; the Upper Clip region below it has Cap = 0. Because the budget shrinks linearly with \u03c0<sub>old</sub>, rare low \u03c0<sub>old</sub> tokens are starved.';
      } else if (st.sign === 'pos' && st.method === 'up') {
        t = lang === 'zh'
          ? 'UP-DAPO\uff08A &gt; 0\uff09\uff1a\u79fb\u9664 \u03c0<sub>old</sub> \u951a\u70b9\u540e\uff0c\u9884\u7b97\u53d8\u4e3a\u5b8c\u6574\u7684 <b>Cap = 1 \u2212 \u03c0<sub>\u03b8</sub></b>\uff08\u7ad6\u5411\u8272\u5e26\uff09\uff0c\u4e0e \u03c0<sub>old</sub> \u65e0\u5173\u4e14\u65e0\u88c1\u526a\u3002\u63a2\u7d22\u4e0d\u518d\u88ab\u5386\u53f2\u7b56\u7565\u9650\u4f4f\u3002'
          : 'UP-DAPO (A &gt; 0): with the \u03c0<sub>old</sub> anchor removed, the budget becomes the full <b>Cap = 1 \u2212 \u03c0<sub>\u03b8</sub></b> (vertical bands), independent of \u03c0<sub>old</sub> and free of clipping. Exploration is no longer throttled by history.';
      } else {
        t = lang === 'zh'
          ? '\u975e\u6b63\u4f18\u52bf\uff08A \u2264 0\uff09\uff1aDAPO \u4e0e UP-DAPO \u5b8c\u5168\u4e00\u81f4\u3002\u9884\u7b97 <b>Cap = \u03c0<sub>\u03b8</sub> \u2212 (1\u2212\u03b5<sub>low</sub>)\u03c0<sub>old</sub></b> \u4ec5\u5728\u84dd\u8272\u697d\u5f62\u5185\u6709\u6548\uff1b\u84dd\u7ebf\u4e0a\u65b9\u4e3a Lower Clip\uff0c\u7d2b\u7ebf\u4e0b\u65b9\u4e3a Dual Clip\uff0c\u4e24\u5904 Cap = 0\u3002'
          : 'Non-positive advantage (A \u2264 0): DAPO and UP-DAPO are identical. The budget <b>Cap = \u03c0<sub>\u03b8</sub> \u2212 (1\u2212\u03b5<sub>low</sub>)\u03c0<sub>old</sub></b> is active only inside the blue wedge; above the blue line lies the Lower Clip and below the purple line the Dual Clip, both with Cap = 0.';
      }
      caption.innerHTML = t;
    }

    function render() { draw(cv, st, lang); dimRows(); setCaption(); }

    root.querySelectorAll('.cap-slider').forEach(function (s) {
      s.addEventListener('input', function () {
        var p = s.getAttribute('data-param');
        st[p] = parseFloat(s.value);
        var out = vals[p];
        if (out) out.textContent = (p === 'c') ? st[p].toFixed(1) : st[p].toFixed(2);
        render();
      });
    });
    root.querySelectorAll('.cap-seg').forEach(function (sg) {
      var kind = sg.getAttribute('data-seg');
      sg.querySelectorAll('.cap-seg-btn').forEach(function (btn) {
        btn.addEventListener('click', function () {
          sg.querySelectorAll('.cap-seg-btn').forEach(function (b) { b.classList.remove('active'); });
          btn.classList.add('active');
          st[kind] = btn.getAttribute('data-val');
          render();
        });
      });
    });

    if (hover) {
      cv.addEventListener('mousemove', function (e) {
        var rect = cv.getBoundingClientRect();
        if (!rect.width) return;
        var sx = W / rect.width, sy = H / rect.height;
        var cx = (e.clientX - rect.left) * sx, cy = (e.clientY - rect.top) * sy;
        var pt = (cx - X0) / PW, po = 1 - (cy - Y0) / PH;
        if (pt < 0 || pt > 1 || po < 0 || po > 1) { hover.innerHTML = hoverDefault; return; }
        var cap = capAt(pt, po, st);
        hover.innerHTML = '\u03c0<sub>\u03b8</sub> = <b>' + fmt(pt) + '</b>, \u03c0<sub>old</sub> = <b>' + fmt(po) + '</b> \u2192 Cap = <b>' + fmt(cap) + '</b>';
      });
      cv.addEventListener('mouseleave', function () { hover.innerHTML = hoverDefault; });
    }

    render();
  }

  function initAll() {
    var roots = document.querySelectorAll('.cap-explorer');
    for (var i = 0; i < roots.length; i++) initRoot(roots[i]);
  }
  if (document.readyState === 'loading') {
    document.addEventListener('DOMContentLoaded', initAll);
  } else {
    initAll();
  }
})();
</script>]]></content><author><name>Chongyu Fan</name></author><category term="rlvr" /><category term="reasoning" /><summary type="html"><![CDATA[IS-based RL for LLM reasoning faces an exploration-stability dilemma: pure importance sampling explodes, and the clipping used to tame it ties a token's update budget to the old policy. By formalizing the Probability Capacity and anchoring the policy to itself with a stop-gradient, Unbounded Positive Asymmetric Optimization (UP) unleashes stable, unclipped gradients for correct rollouts while keeping clipping as a safeguard for wrong ones. UP is a plug-and-play objective that improves DAPO, GRPO, and GSPO across dense, MoE, and vision-language models.]]></summary></entry><entry><title type="html">Rethinking Muon Beyond Pretraining: Spectral Failures and High Pass Remedies for VLA and RLVR</title><link href="https://chongyu-fan.netlify.app/posts/pion/" rel="alternate" type="text/html" title="Rethinking Muon Beyond Pretraining: Spectral Failures and High Pass Remedies for VLA and RLVR" /><published>2026-05-15T00:00:00-07:00</published><updated>2026-05-15T00:00:00-07:00</updated><id>https://chongyu-fan.netlify.app/posts/pion</id><content type="html" xml:base="https://chongyu-fan.netlify.app/posts/pion/"><![CDATA[<div class="post-lang post-lang-en">

  <div class="tldr">

    <h2 id="tldr">TL;DR</h2>

    <ul>
      <li><strong>Muon</strong> is the de facto matrix aware optimizer for <strong>LLM pretraining</strong>, which is basically next token classification on text via supervised learning. Muon orthogonalizes the momentum matrix through a few Newton Schulz (NS) iterations, pushing every singular value of the momentum to one.</li>
      <li>When we move beyond LLM pretraining along three axes (a different <strong>modality</strong>, a different <strong>loss</strong>, or a different <strong>learning paradigm</strong>), Muon’s uniform spectral whitening turns out to be the wrong inductive bias.</li>
      <li>We propose <strong>Pion</strong> (s<strong>P</strong>ectral h<strong>I</strong>gh pass <strong>O</strong>ptimization on mome<strong>N</strong>tum), a drop in replacement for Muon’s NS iteration. It changes only the polynomial coefficients used inside NS, keeps the same per step cost, and realizes a sharp spectral high pass that anchors the informative leading singular values at one while suppressing the noisy tail toward zero.</li>
    </ul>

  </div>

  <h2 id="try-it-where-does-a-singular-value-go">Try It: Where Does a Singular Value Go?</h2>

  <div class="pion-demo" data-muon-labels="whitened to 1|lifted from zero|overshoots 1" data-pion-labels="kept (passes the high pass)|filtered (suppressed)|kept (passes the high pass)">
  <div class="pion-demo-body">
    <div class="pion-demo-controls">
      <div class="pion-demo-intro">
        Pick any <span class="kbd">&sigma; &isin; [0, 1]</span> and watch the same <span class="kbd">&sigma;</span> reshaped by Muon's NS iteration (5 steps) and Pion's high pass NS (<span class="kbd">k<sub>p</sub> = 1, k<sub>s</sub> = 4</span>). Muon tries to push every <span class="kbd">&sigma;</span> toward 1; Pion keeps the head, drops the tail.
      </div>
      <div class="pion-demo-slider-row">
        <span class="sigma-label">&sigma;</span>
        <input type="range" min="0" max="1" step="0.001" value="0.35" class="pion-demo-slider" aria-label="input singular value sigma" />
        <span class="pion-demo-sigma">0.350</span>
      </div>
      <div class="pion-demo-outputs">
        <div class="pion-demo-output muon">
          <div class="out-label">Muon (NS)</div>
          <div class="out-result-wrap">
            <div class="out-divider"></div>
            <div class="out-result">
              <span class="out-input">&sigma; = <span class="out-sigma-in">0.350</span></span>
              <span class="out-arrow-sym">&#x21A6;</span>
              <span class="out-value">&mdash;</span>
            </div>
            <div class="out-tag">&nbsp;</div>
          </div>
        </div>
        <div class="pion-demo-output pion">
          <div class="out-label">Pion (High-pass NS)</div>
          <div class="out-result-wrap">
            <div class="out-divider"></div>
            <div class="out-result">
              <span class="out-input">&sigma; = <span class="out-sigma-in">0.350</span></span>
              <span class="out-arrow-sym">&#x21A6;</span>
              <span class="out-value">&mdash;</span>
            </div>
            <div class="out-tag">&nbsp;</div>
          </div>
        </div>
      </div>
    </div>
    <div class="pion-demo-plot-wrap">
      <svg class="pion-demo-plot" xmlns="http://www.w3.org/2000/svg" aria-hidden="true"></svg>
      <div class="pion-demo-legend">
        <span class="lg lg-muon"><span class="swatch"></span>Muon</span>
        <span class="lg lg-pion"><span class="swatch"></span>Pion</span>
      </div>
    </div>
  </div>
</div>

  <h2 id="background">Background</h2>

  <h3 id="muon">Muon</h3>

  <p>Muon is a <strong>matrix aware</strong> optimizer that has gained wide adoption in <strong>LLM pretraining</strong>. Its entire construction is built around a single observation: treating the momentum as a matrix rather than a flat vector, the natural notion of steepest descent under the spectral norm orthogonalizes the momentum’s singular vectors and pushes every nonzero singular value to one.</p>

  <p>For a weight matrix \(\boldsymbol{\Theta} \in \mathbb{R}^{m \times n}\), given a stochastic gradient \(\mathbf{G}_t\) and a momentum buffer \(\mathbf{M}_t = \mu \mathbf{M}_{t-1} + \mathbf{G}_t\), Muon performs the steepest descent step under the spectral norm:</p>

\[\boldsymbol{\Theta}_t = \boldsymbol{\Theta}_{t-1} - \eta \, \mathrm{msign}(\mathbf{M}_t).\]

  <p>If \(\mathbf{M} = \mathbf{U} \boldsymbol{\Sigma} \mathbf{V}^\top\) is the compact SVD, then</p>

\[\mathrm{msign}(\mathbf{M}) = \mathbf{U}\, \mathrm{sign}(\boldsymbol{\Sigma})\, \mathbf{V}^\top = \mathbf{U} \mathbf{V}^\top.\]

  <p>Every nonzero singular value is mapped to one. This is <strong>uniform spectral whitening</strong>. Computing an SVD per step is too expensive at scale, so Muon approximates \(\mathrm{msign}\) by a small number of Newton Schulz (NS) iterations. After normalizing the input as \(\mathbf{X} \leftarrow \mathbf{X} / (\|\mathbf{X}\|_F + \epsilon)\), each NS step applies an odd quintic matrix polynomial,</p>

\[\mathbf{X} \leftarrow a\, \mathbf{X} + b\, \mathbf{X}\mathbf{X}^\top \mathbf{X} + c\, \mathbf{X}(\mathbf{X}^\top \mathbf{X})^2,\]

  <p>with the canonical coefficients \((a, b, c) = (3.4445,\ -4.7750,\ 2.0315)\). By the identity \(\mathbf{X}(\mathbf{X}^\top \mathbf{X})^j = \mathbf{U}\, \boldsymbol{\Sigma}^{2j+1}\, \mathbf{V}^\top\), an NS step preserves the singular vectors and reshapes each singular value through a <strong>scalar polynomial</strong> on \([0, 1]\):</p>

\[f(\sigma;\, a, b, c) \,\triangleq\, a\sigma + b\sigma^3 + c\sigma^5.\]

  <p>So designing an NS iteration reduces to designing \(f\) on \([0, 1]\). Muon’s NS is constructed so that repeated application drives every \(\sigma \in (0, 1]\) toward one. The shape of this scalar map (and Pion’s eventual replacement for it) is the central object we visualize later in <a href="#fig-1">Figure 1</a>.</p>

  <h3 id="three-axes-beyond-pretraining">Three Axes Beyond Pretraining</h3>

  <p>LLM pretraining is typically optimized with a next token prediction loss; more concretely, the task is <strong>classification</strong>, the modality is <strong>text only</strong>, and the paradigm is <strong>supervised learning</strong>. When per token supervision is dense and accurate, pushing every singular value to one is a reasonable default. But LLM pretraining is only one part of deep learning, and how Muon behaves along different <strong>modalities</strong>, <strong>losses</strong>, and <strong>learning paradigms</strong> remains an open question worth exploring.</p>

  <div class="axes-anim">
  <div class="axes-anim-head">
    <div class="axes-anim-title">
      <span class="badge">Three axes</span>
      Three orthogonal steps out of LLM pretraining
    </div>
    <div class="axes-anim-sub">
      LLM pretraining sits in one corner of design space:
      <span class="corner">text</span>
      &nbsp;&plus;&nbsp;
      <span class="corner">classification</span>
      &nbsp;&plus;&nbsp;
      <span class="corner">supervised learning</span>.
      Each axis below pushes us out of that corner in a different direction.
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">1</span>
      <div>
        <div class="axis-name">Modality</div>
        <div class="axis-hint">language &nbsp;→&nbsp; vision / action</div>
      </div>
    </div>
    <div class="axis-from">
      <div class="ax-tok-row">
        <span class="ax-tok">the</span><span class="ax-tok">cat</span><span class="ax-tok">sits</span><span class="ax-tok">on</span><span class="ax-tok">mat</span>
      </div>
      <div class="ax-cell-label">text tokens</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <div class="ax-mod-to">
        <div class="ax-mod-pix" aria-label="image patches">
          <span style="background:#a5b4fc"></span><span style="background:#c7d2fe"></span><span style="background:#818cf8"></span>
          <span style="background:#c7d2fe"></span><span style="background:#a5b4fc"></span><span style="background:#818cf8"></span>
          <span style="background:#818cf8"></span><span style="background:#a5b4fc"></span><span style="background:#c7d2fe"></span>
        </div>
        <svg class="ax-mod-arm" viewBox="0 0 48 48" aria-hidden="true" fill="none">
          <ellipse cx="24" cy="45" rx="12" ry="1.2" fill="rgba(15,23,42,0.10)" />
          <rect x="12" y="40.5" width="24" height="4" rx="1.5" fill="#4485C7" />
          <rect x="22" y="31.5" width="4" height="10" fill="#4485C7" />
          <line x1="24" y1="31.5" x2="11" y2="21" stroke="#4485C7" stroke-width="4" stroke-linecap="round" />
          <circle cx="24" cy="31.5" r="3.2" fill="#4485C7" />
          <circle cx="24" cy="31.5" r="1.3" fill="#fff" />
          <line x1="11" y1="21" x2="33" y2="10" stroke="#4485C7" stroke-width="4" stroke-linecap="round" />
          <circle cx="11" cy="21" r="2.8" fill="#4485C7" />
          <circle cx="11" cy="21" r="1.1" fill="#fff" />
          <circle cx="33" cy="10" r="2.3" fill="#4485C7" />
          <path d="M33 10 L39 6 L41 8" stroke="#4485C7" stroke-width="2.2" stroke-linecap="round" stroke-linejoin="round" />
          <path d="M33 10 L39 14 L41 12" stroke="#4485C7" stroke-width="2.2" stroke-linecap="round" stroke-linejoin="round" />
        </svg>
      </div>
      <div class="ax-cell-label">image patches / robot actions</div>
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">2</span>
      <div>
        <div class="axis-name">Loss</div>
        <div class="axis-hint">classification &nbsp;→&nbsp; regression</div>
      </div>
    </div>
    <div class="axis-from">
      <svg class="ax-onehot" viewBox="0 0 130 44" aria-hidden="true">
        <line x1="0" y1="20" x2="130" y2="20" stroke="#e5e9ef" stroke-width="0.8" />
        <rect x="6" y="16" width="14" height="4" fill="#93BBE0" rx="1" />
        <rect x="24" y="13" width="14" height="7" fill="#93BBE0" rx="1" />
        <rect x="42" y="10" width="14" height="10" fill="#93BBE0" rx="1" />
        <rect x="60" y="4" width="14" height="16" fill="#4485C7" rx="1" />
        <rect x="78" y="11" width="14" height="9" fill="#93BBE0" rx="1" />
        <rect x="96" y="14" width="14" height="6" fill="#93BBE0" rx="1" />
        <rect x="114" y="16" width="10" height="4" fill="#93BBE0" rx="1" />
        <line x1="0" y1="40" x2="130" y2="40" stroke="#e5e9ef" stroke-width="1" />
        <rect x="6" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="24" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="42" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="60" y="23" width="14" height="17" fill="#4485C7" rx="1" />
        <rect x="78" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="96" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="114" y="38" width="10" height="2" fill="#cbd5e1" rx="1" />
      </svg>
      <div class="ax-cell-label">next-token prediction</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <svg class="ax-curve" viewBox="0 0 130 44" aria-hidden="true">
        <line x1="0" y1="40" x2="130" y2="40" stroke="rgba(68,133,199,0.4)" stroke-width="1" />
        <line x1="8" y1="34" x2="124" y2="9" stroke="#4485C7" stroke-width="1.8" stroke-linecap="round" />
        <circle cx="14" cy="33" r="1.8" fill="#4485C7" />
        <circle cx="28" cy="29" r="1.8" fill="#4485C7" />
        <circle cx="42" cy="28" r="1.8" fill="#4485C7" />
        <circle cx="56" cy="22" r="1.8" fill="#4485C7" />
        <circle cx="70" cy="22" r="1.8" fill="#4485C7" />
        <circle cx="84" cy="16" r="1.8" fill="#4485C7" />
        <circle cx="100" cy="14" r="1.8" fill="#4485C7" />
        <circle cx="116" cy="11" r="1.8" fill="#4485C7" />
      </svg>
      <div class="ax-cell-label">continuous output</div>
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">3</span>
      <div>
        <div class="axis-name">Learning paradigm</div>
        <div class="axis-hint">supervised learning &nbsp;→&nbsp; reinforcement learning</div>
      </div>
    </div>
    <div class="axis-from">
      <div class="ax-tape">
        <div class="row">
          <span class="ax-tok">x<sub>1</sub></span><span class="ax-tok">x<sub>2</sub></span><span class="ax-tok">x<sub>3</sub></span><span class="ax-tok">x<sub>4</sub></span><span class="ax-tok">x<sub>5</sub></span>
        </div>
        <div class="row">
          <span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span>
        </div>
      </div>
      <div class="ax-cell-label">per-token teacher signal</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <div class="ax-tape">
        <div class="row">
          <span class="ax-tok">x<sub>1</sub></span><span class="ax-tok">x<sub>2</sub></span><span class="ax-tok">x<sub>3</sub></span><span class="ax-tok">x<sub>4</sub></span><span class="ax-tok">x<sub>5</sub></span>
        </div>
        <div class="row">
          <span class="arr dot">·</span><span class="arr dot">·</span><span class="arr dot">·</span><span class="arr dot">·</span><span class="arr reward">↓</span>
        </div>
      </div>
      <div class="ax-cell-label">trajectory-level reward</div>
    </div>
  </div>
</div>

  <h2 id="motivation">Motivation</h2>

  <p>We consider two settings: VLA and RLVR. VLA simultaneously changes the modality and the loss (introducing the vision and action modalities and replacing classification with regression loss); RLVR changes only the learning paradigm (replacing supervised learning with reinforcement learning). Through gradient rank and signal-to-noise ratio analyses, we find that Muon transfers poorly to both the action modality and reinforcement learning.</p>

  <h3 id="beyond-modality-and-loss-vla">Beyond Modality and Loss: VLA</h3>

  <p>A VLA model is factorized into a <strong>vision encoder</strong>, a <strong>language backbone</strong>, and an <strong>action head</strong>. The vision and language modules take text instructions and images as input, while the <strong>action head</strong> is a new modality whose output is the robot’s actions. Correspondingly, the action head is trained with a non-classification loss: either \(\ell_1\) regression (e.g., VLA Adapter) or flow matching (e.g., VLANeXt). The “action modality” and “regression-style loss” choices are tightly coupled by construction.</p>

  <p>We measure the spectral structure of each module’s gradient via the <strong>effective rank</strong> (erank) of \(\mathbf{G} \in \mathbb{R}^{m \times n}\):</p>

\[\mathrm{erank}(\mathbf{G}) \,\triangleq\, \exp\!\Big( H(\mathbf{p}) \Big), \quad H(\mathbf{p}) = -\sum_{i=1}^n p_i \log p_i, \quad p_i = \frac{\sigma_i(\mathbf{G})}{\sum_j \sigma_j(\mathbf{G})}.\]

  <p>A higher erank means gradient energy is spread across many singular directions; a lower erank means it concentrates in a few dominant ones.</p>

  <div id="fig-2" class="fig-grid" style="grid-template-columns: repeat(3, 1fr);">
  <figure><img src="/images/blog/pion/erank_heatmap_sampled.png" alt="erank" /><figcaption>(a) Per module gradient erank</figcaption></figure>
  <figure><img src="/images/blog/pion/success_rate.png" alt="success rate" /><figcaption>(b) Test success rate</figcaption></figure>
  <figure><img src="/images/blog/pion/total_training_time.png" alt="training time" /><figcaption>(c) Total training time (hrs)</figcaption></figure>
</div>
  <p class="fig-caption">Figure 2. Limitations of Muon in VLA training (VLA Adapter on LIBERO Object). (a) Per module gradient erank along the training trajectory. (b)(c) Test success rate and total training time at 4.5k steps, with vision and language fixed at AdamW; only the action module optimizer differs.</p>

  <p>The ordering in <a href="#fig-2">Figure 2</a>(a) is stable across training: vision is the highest, language sits in the middle, and the <strong>action gradient is consistently the lowest</strong>. The intuition is twofold: vision and text inputs carry far richer information per sample, whereas an action vector only needs 7 degrees of freedom to express; on top of that, the action head is trained with a regression loss, whose output space is much smaller than the discrete-token space of language and vision, so its gradient is strongly low-rank in nature. When Muon is applied uniformly to such a low-erank gradient, it lifts the weak noise tail to the same magnitude as the few informative leading directions, and the resulting update is dominated by spectral floor noise. Consequently, <a href="#fig-2">Figure 2</a>(b) shows Muon underperforming AdamW on the action head. A natural workaround, <strong>Low-Rank Muon (LRMuon)</strong>, projects the momentum onto a top \(k\) subspace via SVD or Gaussian sketching before NS. LRMuon recovers the success rate, but <a href="#fig-2">Figure 2</a>(c) shows that the explicit projection inflates wall clock by about an order of magnitude, and forces a fixed rank \(k\) that cannot adapt across layers and steps.</p>

  <div class="callout">
    <p><strong>Limitation 1 (modality + loss).</strong> Conventional Muon does not adapt to the rank heterogeneity introduced by new modalities and non-classification losses. Explicit low-rank projection recovers the success rate but at the cost of scalability.</p>
  </div>

  <h3 id="beyond-learning-paradigm-rlvr">Beyond Learning Paradigm: RLVR</h3>

  <p>RLVR keeps the LLM and the text modality; only the <strong>learning paradigm</strong> changes: a token-level supervised loss (as in SFT) is replaced by a trajectory-level policy gradient against a verifiable reward (as in GRPO). To compare the two paradigms on the same footing, we measure the per-step gradient signal-to-noise ratio on a given layer’s weight matrix:</p>

\[\mathrm{SNR}(\mathbf{G}) \,\triangleq\, \frac{\|\mathbb{E}[\mathbf{G}]\|_F^2}{\mathbb{E}\big[\,\|\mathbf{G} - \mathbb{E}[\mathbf{G}]\|_F^2\,\big]}.\]

  <p>Two structural reasons explain the SNR gap in <a href="#fig-3">Figure 3</a>(a). First, <strong>coarser supervision granularity</strong>: SFT uses token-level teacher signals, while GRPO uses trajectory-level rewards, so each token receives a much sparser learning signal. Second, <strong>stabilization mechanisms</strong>: importance sampling, clipping, and group-relative normalization reweight or zero out parts of the per-token gradients, further inflating variance. When Muon is applied on top of these low-SNR gradients, the uniform whitening lifts the noisy directions to the same magnitude as the informative ones, and the policy collapses within a few steps, as shown in <a href="#fig-3">Figure 3</a>(b).</p>

  <div id="fig-3" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/grad_snr_sft_vs_rl_math3-5_step80.png" alt="SFT vs GRPO SNR" /><figcaption>(a) Gradient SNR: SFT vs GRPO</figcaption></figure>
  <figure><img src="/images/blog/pion/acc_adamw_muon.png" alt="Accuracy AdamW vs Muon" /><figcaption>(b) MATH500: AdamW vs Muon</figcaption></figure>
</div>
  <p class="fig-caption">Figure 3. RLVR diagnosis on Qwen3 1.7B (MATH levels 3 to 5). (a) GRPO has substantially lower gradient SNR than SFT throughout training. (b) Under GRPO, AdamW improves steadily while Muon collapses to near zero accuracy within a few steps.</p>

  <div class="callout">
    <p><strong>Limitation 2 (learning paradigm).</strong> Muon’s uniform spectral whitening amplifies noisy directions in low-SNR RLVR gradients, making it unsuitable for noise-sensitive post-training.</p>
  </div>

  <h2 id="method">Method</h2>

  <p>Limitations 1 and 2 come from different sources (low effective rank along the modality / loss axes, low SNR along the learning paradigm axis), yet they share <strong>one spectral signature</strong>. In the SVD of \(\mathbf{M}_t\), the few <strong>leading</strong> singular values carry the informative descent direction, while the long <strong>tail</strong> of small singular values is dominated by noise: a spectral floor when erank is low, stochastic estimation noise when SNR is low. Muon’s \(\mathrm{msign}\) lifts the tail to the magnitude of the head and corrupts the update in both regimes. The natural remedy is a <strong>spectral high pass</strong>: anchor the informative head near one and contract the noisy tail toward zero.</p>

  <h3 id="high-pass-ns">High-Pass NS</h3>

  <p>Since each NS step reshapes \(\sigma \in [0, 1]\) through the scalar polynomial \(f(\sigma; a, b, c) = a\sigma + b\sigma^3 + c\sigma^5\), designing an NS iteration reduces to designing \(f\). A single such polynomial cannot produce a sharp high pass on the unit interval, so Pion splits the default \(k = 5\) NS steps into two stages with different coefficients:</p>

  <ul>
    <li>a <strong>Promotion</strong> polynomial \(f_{\mathrm{p}}\) applied for \(k_{\mathrm{p}}\) steps, which lifts dominant singular values toward one while preserving their relative order;</li>
    <li>a <strong>Suppression</strong> polynomial \(f_{\mathrm{s}}\) applied for \(k_{\mathrm{s}} = k - k_{\mathrm{p}}\) steps, which pins large singular values near one and contracts smaller ones toward zero.</li>
  </ul>

  <p>The cutoff is controlled by the single hyperparameter \(k_{\mathrm{p}} \in \{0, 1, \ldots, 5\}\).</p>

  <p>We require three constraints on \(f_{\mathrm{p}}\): <strong>(P1)</strong> fixed point \(f_{\mathrm{p}}(1) = 1\); <strong>(P2)</strong> first order stationarity \(f_{\mathrm{p}}'(1) = 0\); and <strong>(P3)</strong> boundary concavity \(f_{\mathrm{p}}''(1) \leq 0\), which together with (P2) ensures \(\sigma = 1\) is a maximum so that the iteration does not curve upward past one near the boundary. Solving (P1) and (P2) leaves a one parameter family. Combining (P3) with monotonicity on \([0, 1]\) carves out the feasible interval \(a_{\mathrm{p}} \in [0, 1.875]\). Since \(f_{\mathrm{p}}'(0) = a_{\mathrm{p}}\) controls how strongly each step lifts small singular values, we pick the largest feasible slope, which uniquely determines the polynomial:</p>

\[f_{\mathrm{p}}(\sigma) = 1.875\, \sigma \,-\, 1.25\, \sigma^3 \,+\, 0.375\, \sigma^5.\]

  <p>A pleasant byproduct is that the derivative becomes a perfect square, \(f_{\mathrm{p}}'(\sigma) = 1.875\, (1 - \sigma^2)^2 \geq 0\), so monotonicity on \([0, 1]\) holds automatically.</p>

  <p>The Suppression polynomial inherits \(f_{\mathrm{s}}(1) = 1\) and \(f_{\mathrm{s}}'(1) = 0\), and adds a <strong>spectral filtering</strong> condition \(f_{\mathrm{s}}'(0) = 0\). Removing the linear term near the origin forces small singular values to be driven to zero by the higher order terms. The unique solution is</p>

\[f_{\mathrm{s}}(\sigma) = 2.5\, \sigma^3 \,-\, 1.5\, \sigma^5.\]

  <p>Chaining \(k_{\mathrm{p}}\) Promotion steps with \(k_{\mathrm{s}}\) Suppression steps gives Pion’s <strong>high-pass NS</strong> iteration. Fixing \(k = 5\) preserves Muon’s per-step cost. <a href="#fig-1">Figure 1</a> compares Muon NS, Promotion, Suppression, and the resulting Pion high-pass NS profile: a sharp transition between a pinned region near one and a filtered region near zero, with \(k_{\mathrm{p}}\) controlling the cutoff. Empirically, <strong>suppression-dominant</strong> allocations with \(k_{\mathrm{s}} \geq 3\) work best for both VLA and RLVR.</p>

  <div id="fig-1" class="fig-grid" style="grid-template-columns: repeat(4, 1fr);">
  <figure><img src="/images/blog/pion/iter_NS.png" alt="Muon NS" /><figcaption>(a) Muon NS</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_P.png" alt="Promotion" /><figcaption>(b) Promotion \(f_{\mathrm{p}}\)</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_S.png" alt="Suppression" /><figcaption>(c) Suppression \(f_{\mathrm{s}}\)</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_pion_mix.png" alt="High pass NS" /><figcaption>(d) Pion high pass NS</figcaption></figure>
</div>
  <p class="fig-caption">Figure 1. Visualization of \(f(\sigma)\) on \(\sigma \in [0, 1]\). Muon (a) drives every singular value toward one. Pion combines Promotion (b) with Suppression (c) to obtain the high pass profile in (d).</p>

  <h3 id="per-head-mode-for-rlvr">Per-Head Mode for RLVR</h3>

  <p>So far the high-pass NS has been applied to each per-layer momentum \(\mathbf{M}_t \in \mathbb{R}^{m \times n}\) as a single block, exactly mirroring Muon; we call this the <strong>default mode</strong>. We find that this does not transfer well to RLVR. RLVR starts from a model that has already been pretrained (or SFT’d), whose attention layers exhibit substantial per-head heterogeneity in \(\|\mathbf{W}_Q^h\|_F\), \(\|\mathbf{W}_K^h\|_F\), \(\|\mathbf{W}_V^h\|_F\), and \(\|\mathbf{W}_O^h\|_F\). This heterogeneity jointly governs the forward outputs and the backward gradients, so different heads should naturally receive updates at different scales.</p>

  <p>To respect this structure, Pion adds a <strong>per-head mode</strong> that first reshapes each attention projection along the head dimension into per-head sub-matrices and then runs the two-stage high-pass NS independently on each. Formally, with \(H\) attention heads and per-head dimension \(d_k\), each attention projection (Q / K / V / O) admits a canonical reshape along the head axis,</p>

\[\mathbf{M}_t \;\xrightarrow{\;\mathrm{Reshape}\;}\; \{\mathbf{M}_t^h\}_{h=1}^{H}, \qquad \mathbf{M}_t^h \in \mathbb{R}^{d \times d_k}.\]

  <p>The per-head mode then applies the full two-stage high-pass NS <strong>independently on each \(\mathbf{M}_t^h\)</strong>: a per-head Frobenius pre-normalization \(\mathbf{X}^h \leftarrow \mathbf{M}_t^h / (\|\mathbf{M}_t^h\|_F + \epsilon)\), followed by \(k_{\mathrm{p}}\) Promotion steps and \(k_{\mathrm{s}}\) Suppression steps, and finally a reshape of \(\{\mathbf{X}^h\}_{h=1}^H\) back to a single \(\mathbf{X} \in \mathbb{R}^{m \times n}\). Because \(\mathbf{X}^h (\mathbf{X}^h)^\top \mathbf{X}^h\) is naturally batched over \(h\) on GPU, the only extra cost over the default mode is the reshape itself.</p>

  <p><a href="#fig-4">Figure 4</a>(a) makes the default-mode failure concrete on Qwen3 1.7B: the pre-RLVR cross-head variance \(\mathrm{Var}_h(\|\mathbf{W}_{0,Q}^h\|_F)\) is non-negligible across all 28 layers (top), yet under default-mode Pion the update variance \(\mathrm{Var}_h(\|\mathbf{W}_{*,Q}^h - \mathbf{W}_{0,Q}^h\|_F)\) collapses to near zero (bottom). In other words, a single Frobenius pre-normalization plus a single NS chain over the <strong>whole</strong> projection equalizes the update scale across heads and mixes head-specific directions, so every head ends up with an almost identical update and the inter-head heterogeneity is erased. By contrast, the per-head mode restores a layer-dependent, head-specific update profile.</p>

  <div id="fig-4" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/qwen3_1p7b_Q_headnorm_variance_compact_step80.png" alt="Q headnorm variance" /><figcaption>(a) Cross-head Q variance</figcaption></figure>
  <figure><img src="/images/blog/pion/acc_mh.png" alt="Per head ablation accuracy" /><figcaption>(b) MATH500 accuracy</figcaption></figure>
</div>
  <p class="fig-caption">Figure 4. Effect of per-head high-pass NS on RLVR (Qwen3 1.7B, GRPO on MATH levels 3 to 5). (a) Cross-head Q projection variance: pre-RLVR weight \(\mathrm{Var}_h(\|\mathbf{W}_{0,Q}^h\|_F)\) (top) and post-RLVR update \(\mathrm{Var}_h(\|\mathbf{W}_{*,Q}^h - \mathbf{W}_{0,Q}^h\|_F)\) for default vs. per-head Pion (bottom). (b) MATH500 accuracy of AdamW, Muon (default vs. per-head), and Pion (default vs. per-head).</p>

  <p>At this point, Pion’s per-head high-pass NS bundles two design choices: the <strong>spectral high pass</strong> and the <strong>per-head reshape</strong>. A natural follow-up question is which of the two is doing the heavy lifting. We find that the two are complementary but <strong>not symmetric</strong>. The <strong>spectral high pass</strong> is the <em>primary</em> driver: in <a href="#fig-4">Figure 4</a>(b), even if we apply the same reshape on top of Muon’s NS, the resulting per-head Muon still collapses, because injecting the noise tail head-by-head is just as harmful as injecting it on the whole matrix. The <strong>per-head reshape</strong> is the <em>auxiliary</em> mechanism, used to preserve the per-head heterogeneity inherited from the pretrained (or SFT’d) attention layers. We do not use per-head mode for VLA: there the action head is trained from scratch, with no pretrained multi-head attention structure to preserve.</p>

  <h3 id="algorithms">Algorithms</h3>

  <p>For reference, we write out the full procedures below. Algorithm 1 is Muon’s standard NS iteration. Pion only replaces the inner NS loop with a two stage high pass version: Algorithm 2 is the default mode used for VLA training; Algorithm 3 is the per head mode used for RLVR post training. The total iteration count is fixed to (k = 5), split into (k_{\mathrm{p}}) Promotion steps and (k_{\mathrm{s}} = k - k_{\mathrm{p}}) Suppression steps. <span class="algo-legend-inline"><span class="lg-item"><span class="swatch s-1"></span> Pion vs. Muon</span><span class="lg-item"><span class="swatch s-2"></span> per head specific</span></span></p>

  <div class="algo-row">
  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">Algorithm 1</span>
      <span class="algo-title">Muon Optimizer</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; learning rate \(\eta\), momentum coefficient \(\mu\), NS iteration count \(k = 5\)
    </div>
    <ol class="algo-steps">
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{X} \leftarrow \mathbf{M}_t / (\lVert \mathbf{M}_t \rVert_F + \epsilon)\)</span><span class="comment">spectral pre-norm</span></li>
      <li class="ind-1"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k\) <span class="kw">do</span></span><span class="comment">\((a, b, c) = (3.4445, -4.7750, 2.0315)\)</span></li>
      <li class="ind-2"><span class="line">\(\mathbf{X} \leftarrow a\mathbf{X} + b\mathbf{X}\mathbf{X}^\top\mathbf{X} + c\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>

  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">Algorithm 2</span>
      <span class="algo-title">Pion Optimizer (default: high pass NS on the whole matrix)</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; learning rate \(\eta\), momentum coefficient \(\mu\), promotion steps \(k_{\mathrm{p}}\)
    </div>
    <ol class="algo-steps">
      <li class="algo-diff"><span class="line">\(k_{\mathrm{s}} \leftarrow 5 - k_{\mathrm{p}}\)</span><span class="comment">split \(k = 5\) into \(k_{\mathrm{p}} + k_{\mathrm{s}}\)</span></li>
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{X} \leftarrow \mathbf{M}_t / (\lVert \mathbf{M}_t \rVert_F + \epsilon)\)</span><span class="comment">spectral pre-norm</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k_{\mathrm{p}}\) <span class="kw">do</span></span><span class="comment">stage 1: Promotion, \((a_{\mathrm{p}}, b_{\mathrm{p}}, c_{\mathrm{p}}) = (1.875, -1.25, 0.375)\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X} \leftarrow a_{\mathrm{p}}\mathbf{X} + b_{\mathrm{p}}\mathbf{X}\mathbf{X}^\top\mathbf{X} + c_{\mathrm{p}}\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(j = 1, \dots, k_{\mathrm{s}}\) <span class="kw">do</span></span><span class="comment">stage 2: Suppression, \((a_{\mathrm{s}}, b_{\mathrm{s}}, c_{\mathrm{s}}) = (0, 2.5, -1.5)\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X} \leftarrow a_{\mathrm{s}}\mathbf{X} + b_{\mathrm{s}}\mathbf{X}\mathbf{X}^\top\mathbf{X} + c_{\mathrm{s}}\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>

  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">Algorithm 3</span>
      <span class="algo-title">Pion Optimizer (per head: high pass NS per attention head)</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; learning rate \(\eta\), momentum coefficient \(\mu\), promotion steps \(k_{\mathrm{p}}\), heads \(H\)
    </div>
    <ol class="algo-steps">
      <li class="algo-diff"><span class="line">\(k_{\mathrm{s}} \leftarrow 5 - k_{\mathrm{p}}\)</span><span class="comment">split \(k = 5\) into \(k_{\mathrm{p}} + k_{\mathrm{s}}\)</span></li>
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\{\mathbf{M}_t^h\}_{h=1}^{H} \leftarrow \mathrm{Reshape}(\mathbf{M}_t)\)</span><span class="comment">split attention along head dim</span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\mathbf{X}^h \leftarrow \mathbf{M}_t^h / (\lVert \mathbf{M}_t^h \rVert_F + \epsilon),\ \forall\, h\)</span><span class="comment">per head pre-norm</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k_{\mathrm{p}}\) <span class="kw">do</span></span><span class="comment">stage 1: Promotion, batched over \(H\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X}^h \leftarrow a_{\mathrm{p}}\mathbf{X}^h + b_{\mathrm{p}}\mathbf{X}^h(\mathbf{X}^h)^\top\mathbf{X}^h + c_{\mathrm{p}}\mathbf{X}^h\bigl((\mathbf{X}^h)^\top\mathbf{X}^h\bigr)^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(j = 1, \dots, k_{\mathrm{s}}\) <span class="kw">do</span></span><span class="comment">stage 2: Suppression, batched over \(H\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X}^h \leftarrow a_{\mathrm{s}}\mathbf{X}^h + b_{\mathrm{s}}\mathbf{X}^h(\mathbf{X}^h)^\top\mathbf{X}^h + c_{\mathrm{s}}\mathbf{X}^h\bigl((\mathbf{X}^h)^\top\mathbf{X}^h\bigr)^2\)</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\mathbf{X} \leftarrow \mathrm{Reshape}^{-1}(\{\mathbf{X}^h\}_{h=1}^{H})\)</span><span class="comment">rejoin per head matrices</span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>
</div>

  <div class="callout">
    <p><strong>Takeaway.</strong> Pion is a drop in replacement for Muon’s NS iteration. Same control flow, same per step cost; only the polynomial coefficients change.</p>
  </div>

  <h2 id="experiments">Experiments</h2>

  <p>We evaluate Pion in two settings:</p>

  <ul>
    <li><strong>VLA training</strong>: two architectures, \(\ell_1\)-regression based VLA Adapter and flow-matching based VLANeXt, with LIBERO and LIBERO Plus as benchmarks.</li>
    <li><strong>RLVR post-training</strong>: GRPO and GMPO on Qwen3 1.7B and Qwen3 4B, with MATH and GSM8K as benchmarks.</li>
  </ul>

  <h3 id="vla">VLA</h3>

  <p><strong>VLA Adapter on LIBERO.</strong> We first compare AdamW, Muon, and Pion on VLA Adapter across the four LIBERO task suites (Object, Spatial, Goal, Long) under a fixed per-suite training budget (1,500 steps for Object, 15,000 steps for the others), together with a finer learning curve on Object.</p>

  <div id="fig-5" class="fig-grid" style="grid-template-columns: minmax(0, 2fr) minmax(0, 1fr); max-width: 90%; margin: 0.6em auto 0.05em; padding: 2px 10px 2px; row-gap: 0;">
  <div class="fig-legend" style="margin-top: 0; margin-bottom: -10px;"><img src="/images/blog/pion/vlaadapter_legend.png" alt="Legend: AdamW, Muon, Pion" /></div>
  <figure style="min-width: 0; height: auto; justify-content: flex-start; margin: 0;"><img src="/images/blog/pion/vlaadapter_libero.png" alt="LIBERO four tasks" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" /><figcaption style="white-space: normal; margin: 0;">(a) Success rates on LIBERO</figcaption></figure>
  <figure style="min-width: 0; height: auto; justify-content: flex-start; margin: 0;"><img src="/images/blog/pion/vlaadapter_training.png" alt="Object training curve" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" /><figcaption style="white-space: normal; margin: 0;">(b) Success rate vs. steps on Object</figcaption></figure>
</div>
  <p class="fig-caption">Figure 5. AdamW, Muon, and Pion for VLA Adapter on LIBERO. (a) Test success rates on LIBERO Object, Spatial, Goal, and Long at a fixed training budget per suite (1,500 steps for Object, 15,000 steps for the others). (b) Test success rate vs. training steps on LIBERO Object.</p>

  <p><a href="#fig-5">Figure 5</a>(a) shows that Pion comprehensively outperforms both Muon and AdamW on every suite. <a href="#fig-5">Figure 5</a>(b) further zooms into the LIBERO Object learning curve: Pion reaches 95.4% success at 500 steps and saturates at 100% by 1,500 steps, while AdamW requires substantially more steps to catch up. This indicates that the spectral high pass substantially reduces the training cost needed to reach the high-success regime.</p>

  <p><strong>VLANeXt on LIBERO and LIBERO Plus.</strong> With flow matching, Pion not only achieves the best success rate on LIBERO but also retains its advantage on the more challenging LIBERO Plus split, particularly under the language (\(+9\) pts), noise (\(+6\) pts), and robot (\(+6\) pts) perturbations; see <a href="#tab-1">Table 1</a>. This confirms our earlier picture that uniform whitening over-amplifies noise directions that do not generalize.</p>

  <div id="tab-1" class="results-table">

    <table>
      <thead>
        <tr>
          <th style="text-align: left">Optimizer</th>
          <th style="text-align: center">LIBERO</th>
          <th style="text-align: center">LIBERO Plus</th>
          <th style="text-align: center">Background</th>
          <th style="text-align: center">Camera</th>
          <th style="text-align: center">Language</th>
          <th style="text-align: center">Layout</th>
          <th style="text-align: center">Light</th>
          <th style="text-align: center">Noise</th>
          <th style="text-align: center">Robot</th>
        </tr>
      </thead>
      <tbody>
        <tr>
          <td style="text-align: left">AdamW</td>
          <td style="text-align: center">79.45</td>
          <td style="text-align: center">64.57</td>
          <td style="text-align: center">68.97</td>
          <td style="text-align: center">70.38</td>
          <td style="text-align: center">54.50</td>
          <td style="text-align: center">61.80</td>
          <td style="text-align: center">76.35</td>
          <td style="text-align: center">66.37</td>
          <td style="text-align: center">47.04</td>
        </tr>
        <tr>
          <td style="text-align: left">Muon</td>
          <td style="text-align: center">93.65</td>
          <td style="text-align: center">72.34</td>
          <td style="text-align: center">82.72</td>
          <td style="text-align: center">68.00</td>
          <td style="text-align: center">77.53</td>
          <td style="text-align: center">76.21</td>
          <td style="text-align: center">86.17</td>
          <td style="text-align: center">69.98</td>
          <td style="text-align: center">57.36</td>
        </tr>
        <tr>
          <td style="text-align: left"><strong>Pion (Ours)</strong></td>
          <td style="text-align: center"><strong>96.35</strong></td>
          <td style="text-align: center"><strong>75.93</strong></td>
          <td style="text-align: center"><strong>84.53</strong></td>
          <td style="text-align: center"><strong>70.88</strong></td>
          <td style="text-align: center"><strong>86.93</strong></td>
          <td style="text-align: center"><strong>76.71</strong></td>
          <td style="text-align: center"><strong>90.67</strong></td>
          <td style="text-align: center"><strong>76.09</strong></td>
          <td style="text-align: center"><strong>63.18</strong></td>
        </tr>
      </tbody>
    </table>

  </div>
  <p class="fig-caption">Table 1. AdamW, Muon, and Pion for VLANeXt on LIBERO and LIBERO Plus. Best in <strong>bold</strong>.</p>

  <p>To make the LIBERO Plus gap concrete, we roll out the same LIBERO Plus episode under VLANeXt policies trained with each optimizer. AdamW and Muon fail at the grasp or placement stage, while Pion completes the task cleanly.</p>

  <div id="video-1" class="fig-grid" style="grid-template-columns: repeat(3, 1fr);">
  <figure><video src="/videos/blog/pion/ep1373_AdamW.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(a) AdamW</figcaption></figure>
  <figure><video src="/videos/blog/pion/ep1373_Muon.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(b) Muon</figcaption></figure>
  <figure><video src="/videos/blog/pion/ep1373_Pion.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(c) Pion (Ours)</figcaption></figure>
</div>
  <p class="fig-caption">Video 1. Rollouts on the same LIBERO Plus episode (ep1373) under VLANeXt policies trained with the three optimizers. Only Pion reliably completes the task; AdamW and Muon fail in the grasp or placement stage.</p>

  <h3 id="rlvr">RLVR</h3>

  <p>Across all eight RLVR settings (GRPO/GMPO × Qwen3 1.7B/4B × MATH/GSM8K; see <a href="#fig-6">Figure 6</a>), Muon collapses to near-zero accuracy without exception. Pion not only recovers a meaningful training signal but also converges faster than AdamW.</p>

  <div id="fig-6" class="fig-grid" style="grid-template-columns: repeat(4, 1fr);">
  <figure><img src="/images/blog/pion/rl_val_core_grpo_math3-5_qwen3_1.7b.png" alt="" /><figcaption>(a) GRPO, 1.7B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_math3-5_qwen3_4b.png" alt="" /><figcaption>(b) GRPO, 4B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_gsm8k_qwen3_1.7b.png" alt="" /><figcaption>(c) GRPO, 1.7B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_gsm8k_qwen3_4b.png" alt="" /><figcaption>(d) GRPO, 4B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_math3-5_qwen3_1.7b.png" alt="" /><figcaption>(e) GMPO, 1.7B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_math3-5_qwen3_4b.png" alt="" /><figcaption>(f) GMPO, 4B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_gsm8k_qwen3_1.7b.png" alt="" /><figcaption>(g) GMPO, 1.7B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_gsm8k_qwen3_4b.png" alt="" /><figcaption>(h) GMPO, 4B, GSM8K</figcaption></figure>
</div>
  <p class="fig-caption">Figure 6. AdamW, Muon, and Pion on RLVR: validation accuracy vs training step across eight settings (two algorithms × two model sizes × two benchmarks).</p>

  <p><strong>Reverse ablation: direction of spectral shaping matters.</strong> To verify that the gains come specifically from the high-pass direction, we construct <strong>Low-pass Muon (LPMuon)</strong>, which shares Pion’s NS structure and per-step cost but reverses the filtering direction to low-pass (contracting large singular values and amplifying small ones). LPMuon fails to train: its accuracy stays at the initial checkpoint, see <a href="#fig-7">Figure 7</a>.</p>

  <div id="fig-7" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/pion0_muon_lowrankmuon.png" alt="Low pass profile" /><figcaption>(a) Low pass scalar map</figcaption></figure>
  <figure><img src="/images/blog/pion/mhlpmuon.png" alt="GSM8K accuracy" /><figcaption>(b) GSM8K accuracy</figcaption></figure>
</div>
  <p class="fig-caption">Figure 7. (a) Scalar map \(f(\sigma)\) of LPMuon. (b) GSM8K accuracy of AdamW, Pion, and LPMuon (Qwen3 1.7B, GRPO).</p>

  <h2 id="bibtex">BibTeX</h2>

  <pre class="bibtex-block"><code>@misc{fan2026rethinkingmuonpretrainingspectral,
      title={Rethinking Muon Beyond Pretraining: Spectral Failures and High-Pass Remedies for VLA and RLVR}, 
      author={Chongyu Fan and Gaowen Liu and Mingyi Hong and Ramana Rao Kompella and Sijia Liu},
      year={2026},
      eprint={2605.19282},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2605.19282}, 
}
</code></pre>

</div>

<div class="post-lang post-lang-zh" hidden="">

  <div class="tldr">

    <h2 id="tldr-1">TL;DR</h2>

    <ul>
      <li><strong>Muon</strong> 是一种在 <strong>LLM 预训练</strong>中被广泛采用的“矩阵感知”优化器。它通过 Newton–Schulz (NS) 迭代将所有奇异值统一放大至 1 附近，从而实现动量矩阵正交化。</li>
      <li>然而我们发现，这种“一刀切”放大所有奇异值的做法具有局限性，一旦脱离 LLM 预训练设定（如更换<strong>模态</strong>、<strong>损失</strong>或<strong>学习范式</strong>）便不再适用。</li>
      <li>为此，我们提出 <strong>Pion</strong>（s<strong>P</strong>ectral h<strong>I</strong>gh-pass <strong>O</strong>ptimization on mome<strong>N</strong>tum）。该方法仅需修改 Muon 中 NS 迭代的系数，在保持每步计算开销与 Muon 完全一致的前提下，实现了一种“谱高通”机制，也就是将承载主要信息的头部奇异值锚定在 1 附近，并将噪声主导的尾部奇异值抑制至 0。</li>
    </ul>

  </div>

  <h2 id="section">试一试：σ 被映射到何处？</h2>

  <div class="pion-demo" data-muon-labels="被白化为 1|从 0 拉起|越过 1（震荡）" data-pion-labels="保留（高通）|过滤（被压制）|保留（高通）">
  <div class="pion-demo-body">
    <div class="pion-demo-controls">
      <div class="pion-demo-intro">
        选取一个 <span class="kbd">&sigma; &isin; [0, 1]</span>，观察同一个 <span class="kbd">&sigma;</span> 在 Muon 的 NS 与 Pion 的高通 NS 下分别被映射到何处。Muon 试图将所有 <span class="kbd">&sigma;</span> 放大到 1；Pion 放大头部、缩小尾部。
      </div>
      <div class="pion-demo-slider-row">
        <span class="sigma-label">&sigma;</span>
        <input type="range" min="0" max="1" step="0.001" value="0.35" class="pion-demo-slider" aria-label="奇异值 sigma" />
        <span class="pion-demo-sigma">0.350</span>
      </div>
      <div class="pion-demo-outputs">
        <div class="pion-demo-output muon">
          <div class="out-label">Muon (NS)</div>
          <div class="out-result-wrap">
            <div class="out-divider"></div>
            <div class="out-result">
              <span class="out-input">&sigma; = <span class="out-sigma-in">0.350</span></span>
              <span class="out-arrow-sym">&#x21A6;</span>
              <span class="out-value">&mdash;</span>
            </div>
            <div class="out-tag">&nbsp;</div>
          </div>
        </div>
        <div class="pion-demo-output pion">
          <div class="out-label">Pion (High-pass NS)</div>
          <div class="out-result-wrap">
            <div class="out-divider"></div>
            <div class="out-result">
              <span class="out-input">&sigma; = <span class="out-sigma-in">0.350</span></span>
              <span class="out-arrow-sym">&#x21A6;</span>
              <span class="out-value">&mdash;</span>
            </div>
            <div class="out-tag">&nbsp;</div>
          </div>
        </div>
      </div>
    </div>
    <div class="pion-demo-plot-wrap">
      <svg class="pion-demo-plot" xmlns="http://www.w3.org/2000/svg" aria-hidden="true"></svg>
      <div class="pion-demo-legend">
        <span class="lg lg-muon"><span class="swatch"></span>Muon</span>
        <span class="lg lg-pion"><span class="swatch"></span>Pion</span>
      </div>
    </div>
  </div>
</div>

  <h2 id="section-1">背景</h2>

  <h3 id="muon-1">Muon</h3>

  <p>Muon 是一种”<strong>矩阵感知</strong>“优化器，在 <strong>LLM 预训练</strong>中应用广泛。记权重矩阵为 \(\boldsymbol{\Theta} \in \mathbb{R}^{m \times n}\)，梯度为 \(\mathbf{G}_t\)，动量为 \(\mathbf{M}_t = \mu \mathbf{M}_{t-1} + \mathbf{G}_t\)。Muon 在谱范数下执行最速下降：</p>

\[\boldsymbol{\Theta}_t = \boldsymbol{\Theta}_{t-1} - \eta \, \mathrm{msign}(\mathbf{M}_t).\]

  <p>若 \(\mathbf{M} = \mathbf{U} \boldsymbol{\Sigma} \mathbf{V}^\top\) 为其紧凑 SVD，则</p>

\[\mathrm{msign}(\mathbf{M}) = \mathbf{U}\, \mathrm{sign}(\boldsymbol{\Sigma})\, \mathbf{V}^\top = \mathbf{U} \mathbf{V}^\top.\]

  <p>所有非零奇异值均被映射至 1 附近，即所谓的<strong>均匀谱白化</strong>。然而在大模型训练中，每步执行一次 SVD 代价过高，因此 Muon 转而用若干步 NS 迭代近似 \(\mathrm{msign}\)。先将输入归一化为 \(\mathbf{X} \leftarrow \mathbf{X} / (\|\mathbf{X}\|_F + \epsilon)\)，再在每一步 NS 中应用一次奇次多项式：</p>

\[\mathbf{X} \leftarrow a\, \mathbf{X} + b\, \mathbf{X}\mathbf{X}^\top \mathbf{X} + c\, \mathbf{X}(\mathbf{X}^\top \mathbf{X})^2,\]

  <p>系数取 \((a, b, c) = (3.4445,\ -4.7750,\ 2.0315)\)。借助恒等式 \(\mathbf{X}(\mathbf{X}^\top \mathbf{X})^j = \mathbf{U}\, \boldsymbol{\Sigma}^{2j+1}\, \mathbf{V}^\top\)，每一步 NS 都保持奇异向量不变，仅通过 \([0, 1]\) 上的一个<strong>标量多项式</strong>对奇异值进行重塑：</p>

\[f(\sigma;\, a, b, c) \,\triangleq\, a\sigma + b\sigma^3 + c\sigma^5.\]

  <p>Muon 的 NS 能将任意 \(\sigma \in (0, 1]\) 放大到 1 附近。该函数的图像见 <a href="#fig-1-zh">图 1</a>。</p>

  <h3 id="muon-">Muon 在其他场景下是否仍然适用？</h3>

  <p>LLM 预训练通常使用 next token prediction loss；更具体地说，任务是<strong>分类</strong>，模态只有<strong>文本</strong>，范式是<strong>监督学习</strong>。当 token 级监督密集且准确时，将所有奇异值放大到 1 是较为合理的默认选择。但 LLM 预训练只是深度学习的一部分，Muon 在不同<strong>模态</strong>、不同<strong>损失</strong>、不同<strong>学习范式</strong>下的表现，仍是值得探索的问题：</p>

  <div class="axes-anim">
  <div class="axes-anim-head">
    <div class="axes-anim-title">
      Muon 在其他场景下是否仍然适用？
    </div>
    <div class="axes-anim-sub">
      LLM 预训练：
      <span class="corner">文本</span>
      &nbsp;&plus;&nbsp;
      <span class="corner">分类</span>
      &nbsp;&plus;&nbsp;
      <span class="corner">监督学习</span>。
      我们将通过更改**模态**、**损失**、**学习范式**来验证 Muon 的有效性。
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">1</span>
      <div>
        <div class="axis-name">模态</div>
        <div class="axis-hint">语言 &nbsp;→&nbsp; 视觉 / 动作</div>
      </div>
    </div>
    <div class="axis-from">
      <div class="ax-tok-row">
        <span class="ax-tok">the</span><span class="ax-tok">cat</span><span class="ax-tok">sits</span><span class="ax-tok">on</span><span class="ax-tok">mat</span>
      </div>
      <div class="ax-cell-label">文本 token</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <div class="ax-mod-to">
        <div class="ax-mod-pix" aria-label="image patches">
          <span style="background:#a5b4fc"></span><span style="background:#c7d2fe"></span><span style="background:#818cf8"></span>
          <span style="background:#c7d2fe"></span><span style="background:#a5b4fc"></span><span style="background:#818cf8"></span>
          <span style="background:#818cf8"></span><span style="background:#a5b4fc"></span><span style="background:#c7d2fe"></span>
        </div>
        <svg class="ax-mod-arm" viewBox="0 0 48 48" aria-hidden="true" fill="none">
          <ellipse cx="24" cy="45" rx="12" ry="1.2" fill="rgba(15,23,42,0.10)" />
          <rect x="12" y="40.5" width="24" height="4" rx="1.5" fill="#4485C7" />
          <rect x="22" y="31.5" width="4" height="10" fill="#4485C7" />
          <line x1="24" y1="31.5" x2="11" y2="21" stroke="#4485C7" stroke-width="4" stroke-linecap="round" />
          <circle cx="24" cy="31.5" r="3.2" fill="#4485C7" />
          <circle cx="24" cy="31.5" r="1.3" fill="#fff" />
          <line x1="11" y1="21" x2="33" y2="10" stroke="#4485C7" stroke-width="4" stroke-linecap="round" />
          <circle cx="11" cy="21" r="2.8" fill="#4485C7" />
          <circle cx="11" cy="21" r="1.1" fill="#fff" />
          <circle cx="33" cy="10" r="2.3" fill="#4485C7" />
          <path d="M33 10 L39 6 L41 8" stroke="#4485C7" stroke-width="2.2" stroke-linecap="round" stroke-linejoin="round" />
          <path d="M33 10 L39 14 L41 12" stroke="#4485C7" stroke-width="2.2" stroke-linecap="round" stroke-linejoin="round" />
        </svg>
      </div>
      <div class="ax-cell-label">图像 patch / 机器人动作</div>
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">2</span>
      <div>
        <div class="axis-name">损失</div>
        <div class="axis-hint">分类 &nbsp;→&nbsp; 回归</div>
      </div>
    </div>
    <div class="axis-from">
      <svg class="ax-onehot" viewBox="0 0 130 44" aria-hidden="true">
        <line x1="0" y1="20" x2="130" y2="20" stroke="#e5e9ef" stroke-width="0.8" />
        <rect x="6" y="16" width="14" height="4" fill="#93BBE0" rx="1" />
        <rect x="24" y="13" width="14" height="7" fill="#93BBE0" rx="1" />
        <rect x="42" y="10" width="14" height="10" fill="#93BBE0" rx="1" />
        <rect x="60" y="4" width="14" height="16" fill="#4485C7" rx="1" />
        <rect x="78" y="11" width="14" height="9" fill="#93BBE0" rx="1" />
        <rect x="96" y="14" width="14" height="6" fill="#93BBE0" rx="1" />
        <rect x="114" y="16" width="10" height="4" fill="#93BBE0" rx="1" />
        <line x1="0" y1="40" x2="130" y2="40" stroke="#e5e9ef" stroke-width="1" />
        <rect x="6" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="24" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="42" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="60" y="23" width="14" height="17" fill="#4485C7" rx="1" />
        <rect x="78" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="96" y="37.5" width="14" height="2.5" fill="#cbd5e1" rx="1" />
        <rect x="114" y="38" width="10" height="2" fill="#cbd5e1" rx="1" />
      </svg>
      <div class="ax-cell-label">下一 token 预测</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <svg class="ax-curve" viewBox="0 0 130 44" aria-hidden="true">
        <line x1="0" y1="40" x2="130" y2="40" stroke="rgba(68,133,199,0.4)" stroke-width="1" />
        <line x1="8" y1="34" x2="124" y2="9" stroke="#4485C7" stroke-width="1.8" stroke-linecap="round" />
        <circle cx="14" cy="33" r="1.8" fill="#4485C7" />
        <circle cx="28" cy="29" r="1.8" fill="#4485C7" />
        <circle cx="42" cy="28" r="1.8" fill="#4485C7" />
        <circle cx="56" cy="22" r="1.8" fill="#4485C7" />
        <circle cx="70" cy="22" r="1.8" fill="#4485C7" />
        <circle cx="84" cy="16" r="1.8" fill="#4485C7" />
        <circle cx="100" cy="14" r="1.8" fill="#4485C7" />
        <circle cx="116" cy="11" r="1.8" fill="#4485C7" />
      </svg>
      <div class="ax-cell-label">连续输出</div>
    </div>
  </div>

  <div class="axis-track">
    <div class="axis-tag">
      <span class="axis-num">3</span>
      <div>
        <div class="axis-name">学习范式</div>
        <div class="axis-hint">监督学习 &nbsp;→&nbsp; 强化学习</div>
      </div>
    </div>
    <div class="axis-from">
      <div class="ax-tape">
        <div class="row">
          <span class="ax-tok">x<sub>1</sub></span><span class="ax-tok">x<sub>2</sub></span><span class="ax-tok">x<sub>3</sub></span><span class="ax-tok">x<sub>4</sub></span><span class="ax-tok">x<sub>5</sub></span>
        </div>
        <div class="row">
          <span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span><span class="arr dense">↓</span>
        </div>
      </div>
      <div class="ax-cell-label">每个 token 都有教师信号</div>
    </div>
    <div class="axis-arrow"><div class="track"><span class="pulse p1"></span><span class="pulse p2"></span><span class="pulse p3"></span></div><div class="head"></div></div>
    <div class="axis-to">
      <div class="ax-tape">
        <div class="row">
          <span class="ax-tok">x<sub>1</sub></span><span class="ax-tok">x<sub>2</sub></span><span class="ax-tok">x<sub>3</sub></span><span class="ax-tok">x<sub>4</sub></span><span class="ax-tok">x<sub>5</sub></span>
        </div>
        <div class="row">
          <span class="arr dot">·</span><span class="arr dot">·</span><span class="arr dot">·</span><span class="arr dot">·</span><span class="arr reward">↓</span>
        </div>
      </div>
      <div class="ax-cell-label">轨迹级奖励</div>
    </div>
  </div>
</div>

  <h2 id="section-2">动机</h2>

  <p>我们考虑了两个 setting：VLA 与 RLVR。VLA 同时改变了模态与损失（引入视觉与动作模态，并将分类损失替换为回归损失）；RLVR 则单独改变学习范式（将监督学习替换为强化学习）。通过对梯度秩和信噪比的分析，我们发现 Muon 在动作模态和强化学习场景下均不适用。</p>

  <h3 id="vla-1">更换模态与损失：VLA</h3>

  <p>VLA 模型由三部分构成：<strong>vision encoder</strong>、<strong>language backbone</strong> 与 <strong>action head</strong>。vision 与 language 模块的输入是文本指令与图像；action head 则对应一种全新的模态，其输出是机器人的动作。相应地，action head 通常采用的是非分类损失：要么是 \(\ell_1\) regression，要么是 flow matching。</p>

  <p>我们用<strong>有效秩</strong>（effective rank, erank）来刻画各模块梯度 \(\mathbf{G} \in \mathbb{R}^{m \times n}\) 的谱结构：</p>

\[\mathrm{erank}(\mathbf{G}) \,\triangleq\, \exp\!\Big( H(\mathbf{p}) \Big), \quad H(\mathbf{p}) = -\sum_{i=1}^n p_i \log p_i, \quad p_i = \frac{\sigma_i(\mathbf{G})}{\sum_j \sigma_j(\mathbf{G})}.\]

  <p>erank 越大，说明梯度的能量分散在很多奇异方向上；越小，说明能量集中在少数几个主方向上。</p>

  <div id="fig-2-zh" class="fig-grid" style="grid-template-columns: repeat(3, 1fr);">
  <figure><img src="/images/blog/pion/erank_heatmap_sampled.png" alt="erank" /><figcaption>(a) 各模块梯度的有效秩 (erank)</figcaption></figure>
  <figure><img src="/images/blog/pion/success_rate.png" alt="success rate" /><figcaption>(b) 测试成功率</figcaption></figure>
  <figure><img src="/images/blog/pion/total_training_time.png" alt="training time" /><figcaption>(c) 总训练时长（小时）</figcaption></figure>
</div>
  <p class="fig-caption">图 2. Muon 在 VLA 训练（VLA Adapter + LIBERO Object）中的局限性。(a) 全模态使用 AdamW 训练时，各模态梯度的有效秩 (erank)。(b)(c) 4.5k 步时的测试成功率与总训练时长（其中 vision 和 language 使用 AdamW，仅切换 action 的优化器）。</p>

  <p>从 <a href="#fig-2-zh">图 2</a>(a) 可以看出，各模态梯度的 erank 在整个训练过程中非常稳定：vision 最高、language 居中，而<strong>action 梯度的 erank 始终最低</strong>。这主要是因为 vision 与 text 输入通常包含更丰富的信息，而 action 仅需 7 个自由度即可表达；此外，action 模态采用的是 regression loss 进行训练，其输出空间远小于 language 与 vision 的离散 token 空间，这使其梯度展现出极强的低秩特性。在这种低秩的 action 梯度上直接施加 Muon 的均匀白化，等同于将微弱的噪声尾部抬升至与少数主方向相同的量级，导致最终的参数更新几乎完全被谱底噪声主导。如 <a href="#fig-2-zh">图 2</a>(b) 所示，Muon 在 action 模块上的成功率甚至不及 AdamW。一个直观的解决方案是 <strong>Low-Rank Muon (LRMuon)</strong>，即在 NS 迭代之前，先通过 SVD 或 Gaussian sketching 将动量矩阵投影到 top-\(k\) 子空间。这种方法虽能恢复成功率，但 <a href="#fig-2-zh">图 2</a>(c) 表明，引入显式低秩投影会带来巨大的计算负担，使整个训练开销激增约一个数量级。</p>

  <div class="callout">
    <p><strong>局限 1（modality + loss）。</strong> 标准 Muon 无法自适应新模态、新损失所带来的谱秩异质性；显式低秩投影虽能恢复成功率，但代价是失去可扩展性。</p>
  </div>

  <h3 id="rlvr-1">更换学习范式：RLVR</h3>

  <p>RLVR 保持 LLM 与文本模态不变，所改变的仅是<strong>学习范式</strong>：将 token 级监督损失（如 SFT）替换为轨迹级针对可验证奖励的策略梯度（如 GRPO）。为了将两种学习范式置于同一坐标下比较，我们考察每一步梯度的信噪比：</p>

\[\mathrm{SNR}(\mathbf{G}) \,\triangleq\, \frac{\|\mathbb{E}[\mathbf{G}]\|_F^2}{\mathbb{E}\big[\,\|\mathbf{G} - \mathbb{E}[\mathbf{G}]\|_F^2\,\big]}.\]

  <p><a href="#fig-3-zh">图 3</a>(a) 中的 SNR 鸿沟有两个结构性来源。一是<strong>监督粒度变粗</strong>：SFT 使用 token 级教师信号，而 GRPO 使用轨迹级奖励，每个 token 实际获得的学习信号要稀疏得多。二是<strong>稳定化机制</strong>：importance sampling、clipping、advantage normalization 均会重新加权或抹除部分 per-token 梯度，进一步放大方差。如 <a href="#fig-3-zh">图 3</a>(b) 所示，Muon 直接对这种低 SNR 梯度做白化，相当于将噪声方向抬升至与信息方向同等量级，最终策略在数步之内便崩溃。</p>

  <div id="fig-3-zh" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/grad_snr_sft_vs_rl_math3-5_step80.png" alt="SFT vs GRPO SNR" /><figcaption>(a) 梯度 SNR：SFT vs GRPO</figcaption></figure>
  <figure><img src="/images/blog/pion/acc_adamw_muon.png" alt="Accuracy AdamW vs Muon" /><figcaption>(b) MATH500：AdamW vs Muon</figcaption></figure>
</div>
  <p class="fig-caption">图 3. RLVR SNR（Qwen3 1.7B，MATH）。(a) 整段训练中 GRPO 的梯度 SNR 始终明显低于 SFT。(b) 在 GRPO 下，AdamW 稳步提升，而 Muon 在数步之内便崩溃至接近零的准确率。</p>

  <div class="callout">
    <p><strong>局限 2（learning paradigm）。</strong> Muon 的均匀白化会放大低 SNR 的 RLVR 梯度中的噪声方向，因而不适合对噪声敏感的后训练。</p>
  </div>

  <h2 id="section-3">方法</h2>

  <p>局限 1 与局限 2 的来源不同：前者源于不同 modality / loss 的低 erank，后者源于不同 learning paradigm 的低 SNR；但二者在频谱上呈现出相同的形态。在 \(\mathbf{M}_t\) 的 SVD 中，<strong>前若干个</strong>奇异值承载着高信息量的下降方向，<strong>其余大量</strong>小奇异值则被噪声主导（在 erank 较低时表现为谱底，在 SNR 较低时表现为随机估计噪声）。Muon 的 \(\mathrm{msign}\) 将尾部抬升至与头部同等量级，因此在上述两种情形下都会扰乱更新。自然的对策即为<strong>谱高通</strong>：将头部锚定在 1 附近，将尾部抑制到 0。</p>

  <h3 id="ns">高通 NS</h3>

  <p>由于 NS 每一步都通过 \(f(\sigma; a, b, c) = a\sigma + b\sigma^3 + c\sigma^5\) 重塑 \(\sigma\)，因此 NS 的设计归结为对 \(f\) 的设计。仅依靠单一的五次多项式，难以实现我们所需的高通；为此，Pion 将默认的 \(k = 5\) 步 NS 拆分为两段，分别使用不同的系数：</p>

  <ul>
    <li>第一段称为 <strong>Promotion</strong>（提升），多项式 \(f_{\mathrm{p}}\) 运行 \(k_{\mathrm{p}}\) 步：放大头部奇异值到 1 附近，同时保留它们之间的相对大小；</li>
    <li>第二段称为 <strong>Suppression</strong>（抑制），多项式 \(f_{\mathrm{s}}\) 运行 \(k_{\mathrm{s}} = k - k_{\mathrm{p}}\) 步：将已经接近 1 的大奇异值锚定在 1，将仍偏小的奇异值进一步压制至 0。</li>
  </ul>

  <p>我们对 \(f_{\mathrm{p}}\) 给出三条要求：<strong>(P1)</strong> \(\sigma = 1\) 是不动点，\(f_{\mathrm{p}}(1) = 1\)；<strong>(P2)</strong> 一阶平稳，\(f_{\mathrm{p}}'(1) = 0\)；<strong>(P3)</strong> 边界凹性，\(f_{\mathrm{p}}''(1) \leq 0\)，与 (P2) 共同保证 \(\sigma = 1\) 为局部极大点，迭代不会在边界附近越过 1 而发散。(P1) 与 (P2) 将可行解约束为单参数族，进一步结合 (P3) 与 \([0, 1]\) 上的单调性，可行参数收缩为 \(a_{\mathrm{p}} \in [0, 1.875]\)。\(f_{\mathrm{p}}'(0) = a_{\mathrm{p}}\) 控制每一步对小奇异值的提升强度，因此我们直接取其最大可行斜率，从而唯一确定多项式：</p>

\[f_{\mathrm{p}}(\sigma) = 1.875\, \sigma \,-\, 1.25\, \sigma^3 \,+\, 0.375\, \sigma^5.\]

  <p>由于其导数恰为完全平方 \(f_{\mathrm{p}}'(\sigma) = 1.875\, (1 - \sigma^2)^2 \geq 0\)，单调性自然成立。</p>

  <p>Suppression 同样要求 \(f_{\mathrm{s}}(1) = 1\)、\(f_{\mathrm{s}}'(1) = 0\)，并附加一条<strong>谱过滤</strong>条件：\(f_{\mathrm{s}}'(0) = 0\)。在消除原点附近的线性项之后，小奇异值仅能被高阶项逐步缩小到 0。其唯一解为：</p>

\[f_{\mathrm{s}}(\sigma) = 2.5\, \sigma^3 \,-\, 1.5\, \sigma^5.\]

  <p>将 \(k_{\mathrm{p}}\) 步 Promotion 与 \(k_{\mathrm{s}}\) 步 Suppression 串联，即可得到 Pion 的<strong>高通 NS</strong>。固定 \(k = 5\) 使其每步开销与 Muon 完全一致。<a href="#fig-1-zh">图 1</a> 给出了 Muon NS、Promotion、Suppression 与 Pion 高通 NS 的函数图像对比。</p>

  <div id="fig-1-zh" class="fig-grid" style="grid-template-columns: repeat(4, 1fr);">
  <figure><img src="/images/blog/pion/iter_NS.png" alt="Muon NS" /><figcaption>(a) Muon NS</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_P.png" alt="Promotion" /><figcaption>(b) Promotion \(f_{\mathrm{p}}\)</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_S.png" alt="Suppression" /><figcaption>(c) Suppression \(f_{\mathrm{s}}\)</figcaption></figure>
  <figure><img src="/images/blog/pion/iter_pion_mix.png" alt="High pass NS" /><figcaption>(d) Pion 高通 NS</figcaption></figure>
</div>
  <p class="fig-caption">图 1. \(\sigma \in [0, 1]\) 上 \(f(\sigma)\) 的可视化。Muon (a) 将每一个奇异值都放大到 1。Pion 将 Promotion (b) 与 Suppression (c) 组合，得到 (d) 中的高通形态。</p>

  <h3 id="per-head--rlvr">Per-head 模式（用于 RLVR）</h3>

  <p>目前为止，高通 NS 都将每一层的动量 \(\mathbf{M}_t \in \mathbb{R}^{m \times n}\) 作为单一整块处理，与 Muon 完全一致；我们称之为 <strong>default mode</strong>。但我们发现，这种方式并不适用于 RLVR。RLVR 起点是已经 pretrained（或 SFT 过的）LLM，其 attention 层各 head 之间在 \(\|\mathbf{W}_Q^h\|_F\)、\(\|\mathbf{W}_K^h\|_F\)、\(\|\mathbf{W}_V^h\|_F\)、\(\|\mathbf{W}_O^h\|_F\) 上存在显著差异。这种差异同时决定了 forward 的输出与 backward 的梯度，因此不同 head 本应接收<strong>不同尺度的更新</strong>。</p>

  <p>为此，Pion 在 default mode 之外提供一种 <strong>per-head mode</strong>：先沿 head 维度将 attention 投影 reshape 为若干 per-head 子矩阵，再分别在每一个子矩阵上独立运行整套两段式高通 NS。形式上，设 \(H\) 为 attention head 数、\(d_k\) 为单 head 维度，每个 attention 投影（Q / K / V / O 任一）都有一个沿 head 轴的标准 reshape：</p>

\[\mathbf{M}_t \;\xrightarrow{\;\mathrm{Reshape}\;}\; \{\mathbf{M}_t^h\}_{h=1}^{H}, \qquad \mathbf{M}_t^h \in \mathbb{R}^{d \times d_k}.\]

  <p>Per-head mode 在<strong>每个 \(\mathbf{M}_t^h\) 上独立</strong>执行两段式高通 NS：先做 per-head 的 Frobenius 预归一化 \(\mathbf{X}^h \leftarrow \mathbf{M}_t^h / (\|\mathbf{M}_t^h\|_F + \epsilon)\)，再依次执行 \(k_{\mathrm{p}}\) 步 Promotion 与 \(k_{\mathrm{s}}\) 步 Suppression，最后再将 \(\{\mathbf{X}^h\}_{h=1}^H\) reshape 回完整的 \(\mathbf{X} \in \mathbb{R}^{m \times n}\)。由于 \(\mathbf{X}^h (\mathbf{X}^h)^\top \mathbf{X}^h\) 在 GPU 上本就沿 \(h\) 维做了 batch，per-head mode 相对 default mode 的唯一额外开销即为 reshape 本身。</p>

  <p><a href="#fig-4-zh">图 4</a>(a) 在 Qwen3 1.7B 上具体展示了 default mode 的问题：RLVR 起点权重的跨 head 方差 \(\mathrm{Var}_h(\|\mathbf{W}_{0,Q}^h\|_F)\) 在全部 28 层都不可忽略（上方），但在 default mode 的 Pion 下，更新量的跨 head 方差 \(\mathrm{Var}_h(\|\mathbf{W}_{*,Q}^h - \mathbf{W}_{0,Q}^h\|_F)\) 几乎为零（下方）。也就是说，default mode 会拉平各 head 的更新尺度，并把不同 head 的子方向混合在一起，使得各 head 都得到几乎相同的更新，完全无法体现 head 之间的差异性。相比之下，per-head mode 则恢复了与层相关、随 head 变化的更新结构。</p>

  <div id="fig-4-zh" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/qwen3_1p7b_Q_headnorm_variance_compact_step80.png" alt="Q headnorm variance" /><figcaption>(a) 跨 head Q 投影方差</figcaption></figure>
  <figure><img src="/images/blog/pion/acc_mh.png" alt="Per head ablation accuracy" /><figcaption>(b) MATH500 准确率</figcaption></figure>
</div>
  <p class="fig-caption">图 4. Per-head 高通 NS 在 RLVR 上的效果（Qwen3 1.7B，GRPO + MATH 难度 3 至 5）。(a) Q 投影的跨 head 方差：RLVR 之前 \(\mathrm{Var}_h(\|\mathbf{W}_{0,Q}^h\|_F)\)（上）与 RLVR 更新量 \(\mathrm{Var}_h(\|\mathbf{W}_{*,Q}^h - \mathbf{W}_{0,Q}^h\|_F)\) 在 default 与 per-head Pion 下的对比（下）。(b) AdamW、Muon（default vs per-head）、Pion（default vs per-head）的 MATH500 准确率。</p>

  <p>至此，Pion 的 per-head 高通 NS 包含两个设计：<strong>谱高通</strong>与 <strong>per-head reshape</strong>。一个自然的问题是：两者谁更关键？我们发现两者互补但<strong>并不对称</strong>。<strong>谱高通</strong>是 Pion 提升的<em>主要</em>驱动：在 <a href="#fig-4-zh">图 4</a>(b) 中，即便给 Muon 的 NS 也加上同样的 reshape，得到的 per-head Muon 依然完全崩溃，因为它逐 head 注入的噪声尾部，与它在整块矩阵上注入的噪声同样致命。<strong>Per-head reshape</strong> 则是<em>辅助</em>机制，用于保留 pretrained（或 SFT 过的）LLM 中 attention 层各 head 的差异性。</p>

  <h3 id="section-4">伪代码</h3>

  <p>算法 1 是 Muon 标准的 NS 迭代；算法 2 是 Pion 高通 NS 的默认模式，算法 3 是 per-head 模式。<span class="algo-legend-inline"><span class="lg-item"><span class="swatch s-1"></span> Pion 与 Muon 的差异</span><span class="lg-item"><span class="swatch s-2"></span> per-head 模式独有</span></span></p>

  <div class="algo-row">
  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">算法 1</span>
      <span class="algo-title">Muon 优化器</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; 学习率 \(\eta\)，动量系数 \(\mu\)，NS 迭代步数 \(k = 5\)
    </div>
    <ol class="algo-steps">
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{X} \leftarrow \mathbf{M}_t / (\lVert \mathbf{M}_t \rVert_F + \epsilon)\)</span><span class="comment">谱预归一化</span></li>
      <li class="ind-1"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k\) <span class="kw">do</span></span><span class="comment">\((a, b, c) = (3.4445, -4.7750, 2.0315)\)</span></li>
      <li class="ind-2"><span class="line">\(\mathbf{X} \leftarrow a\mathbf{X} + b\mathbf{X}\mathbf{X}^\top\mathbf{X} + c\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>

  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">算法 2</span>
      <span class="algo-title">Pion 优化器（默认模式：整块矩阵高通 NS）</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; 学习率 \(\eta\)，动量系数 \(\mu\)，Promotion 步数 \(k_{\mathrm{p}}\)
    </div>
    <ol class="algo-steps">
      <li class="algo-diff"><span class="line">\(k_{\mathrm{s}} \leftarrow 5 - k_{\mathrm{p}}\)</span><span class="comment">把 \(k = 5\) 拆成 \(k_{\mathrm{p}} + k_{\mathrm{s}}\)</span></li>
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{X} \leftarrow \mathbf{M}_t / (\lVert \mathbf{M}_t \rVert_F + \epsilon)\)</span><span class="comment">谱预归一化</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k_{\mathrm{p}}\) <span class="kw">do</span></span><span class="comment">第一阶段 Promotion，\((a_{\mathrm{p}}, b_{\mathrm{p}}, c_{\mathrm{p}}) = (1.875, -1.25, 0.375)\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X} \leftarrow a_{\mathrm{p}}\mathbf{X} + b_{\mathrm{p}}\mathbf{X}\mathbf{X}^\top\mathbf{X} + c_{\mathrm{p}}\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(j = 1, \dots, k_{\mathrm{s}}\) <span class="kw">do</span></span><span class="comment">第二阶段 Suppression，\((a_{\mathrm{s}}, b_{\mathrm{s}}, c_{\mathrm{s}}) = (0, 2.5, -1.5)\)</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X} \leftarrow a_{\mathrm{s}}\mathbf{X} + b_{\mathrm{s}}\mathbf{X}\mathbf{X}^\top\mathbf{X} + c_{\mathrm{s}}\mathbf{X}(\mathbf{X}^\top\mathbf{X})^2\)</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>

  <div class="algo-block compact">
    <div class="algo-header">
      <span class="algo-num">算法 3</span>
      <span class="algo-title">Pion 优化器（per-head 模式：按 attention head 高通 NS）</span>
    </div>
    <div class="algo-require">
      <span class="kw">Require:</span>&nbsp; 学习率 \(\eta\)，动量系数 \(\mu\)，Promotion 步数 \(k_{\mathrm{p}}\)，head 数 \(H\)
    </div>
    <ol class="algo-steps">
      <li class="algo-diff"><span class="line">\(k_{\mathrm{s}} \leftarrow 5 - k_{\mathrm{p}}\)</span><span class="comment">把 \(k = 5\) 拆成 \(k_{\mathrm{p}} + k_{\mathrm{s}}\)</span></li>
      <li><span class="line">\(\mathbf{M}_0 \leftarrow \mathbf{0}\)</span></li>
      <li><span class="line"><span class="kw">for</span> \(t = 1, 2, \dots\) <span class="kw">do</span></span></li>
      <li class="ind-1"><span class="line">\(\mathbf{G}_t \leftarrow \nabla_{\boldsymbol{\Theta}} \mathcal{L}_t(\boldsymbol{\Theta}_{t-1})\)</span></li>
      <li class="ind-1"><span class="line">\(\mathbf{M}_t \leftarrow \mu\, \mathbf{M}_{t-1} + \mathbf{G}_t\)</span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\{\mathbf{M}_t^h\}_{h=1}^{H} \leftarrow \mathrm{Reshape}(\mathbf{M}_t)\)</span><span class="comment">沿 head 维度切分</span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\mathbf{X}^h \leftarrow \mathbf{M}_t^h / (\lVert \mathbf{M}_t^h \rVert_F + \epsilon),\ \forall\, h\)</span><span class="comment">per-head 预归一化</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(i = 1, \dots, k_{\mathrm{p}}\) <span class="kw">do</span></span><span class="comment">第一阶段 Promotion，沿 \(H\) batch</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X}^h \leftarrow a_{\mathrm{p}}\mathbf{X}^h + b_{\mathrm{p}}\mathbf{X}^h(\mathbf{X}^h)^\top\mathbf{X}^h + c_{\mathrm{p}}\mathbf{X}^h\bigl((\mathbf{X}^h)^\top\mathbf{X}^h\bigr)^2\)</span></li>
      <li class="ind-1"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">for</span> \(j = 1, \dots, k_{\mathrm{s}}\) <span class="kw">do</span></span><span class="comment">第二阶段 Suppression，沿 \(H\) batch</span></li>
      <li class="ind-2 algo-diff"><span class="line">\(\mathbf{X}^h \leftarrow a_{\mathrm{s}}\mathbf{X}^h + b_{\mathrm{s}}\mathbf{X}^h(\mathbf{X}^h)^\top\mathbf{X}^h + c_{\mathrm{s}}\mathbf{X}^h\bigl((\mathbf{X}^h)^\top\mathbf{X}^h\bigr)^2\)</span></li>
      <li class="ind-1 algo-diff"><span class="line"><span class="kw">end for</span></span></li>
      <li class="ind-1 algo-diff-2"><span class="line">\(\mathbf{X} \leftarrow \mathrm{Reshape}^{-1}(\{\mathbf{X}^h\}_{h=1}^{H})\)</span><span class="comment">合并 per-head 矩阵</span></li>
      <li class="ind-1"><span class="line">\(\boldsymbol{\Theta}_t \leftarrow \boldsymbol{\Theta}_{t-1} - \eta\, \mathbf{X}\)</span></li>
      <li><span class="line"><span class="kw">end for</span></span></li>
      <li><span class="line"><span class="kw">return</span> \(\boldsymbol{\Theta}_t\)</span></li>
    </ol>
  </div>
</div>

  <div class="callout">
    <!-- **一句话总结。** Pion 是 Muon NS 的即插即用替代方案：控制流不动、每步开销不动，只换多项式系数。 -->
  </div>

  <h2 id="section-5">实验</h2>

  <p>我们在两个 setting 验证 Pion：</p>

  <ul>
    <li><strong>VLA 训练</strong>：两种结构，基于 \(\ell_1\)-regression 的 VLA Adapter 与基于 flow-matching 的 VLANeXt，以 LIBERO 和 LIBERO Plus 作为 benchmark；</li>
    <li><strong>RLVR 后训练</strong>：算法选用 GRPO 和 GMPO；模型选用 Qwen3 1.7B 和 Qwen3 4B；benchmark 为 MATH 和 GSM8K。</li>
  </ul>

  <h3 id="vla-2">VLA</h3>

  <p><strong>VLA Adapter on LIBERO。</strong> 我们首先在 VLA Adapter 上对 AdamW、Muon、Pion 进行比较：在 LIBERO 的四个子集（Object、Spatial、Goal、Long）上，每个子集采用固定训练预算（Object 1,500 步，其余 15,000 步），并在 Object 上额外给出更精细的训练曲线。</p>

  <div id="fig-5-zh" class="fig-grid" style="grid-template-columns: minmax(0, 2fr) minmax(0, 1fr); max-width: 90%; margin: 0.6em auto 0.05em; padding: 2px 10px 2px; row-gap: 0;">
  <div class="fig-legend" style="margin-top: 0; margin-bottom: -10px;"><img src="/images/blog/pion/vlaadapter_legend.png" alt="Legend: AdamW, Muon, Pion" /></div>
  <figure style="min-width: 0; height: auto; justify-content: flex-start; margin: 0;"><img src="/images/blog/pion/vlaadapter_libero.png" alt="LIBERO four tasks" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" /><figcaption style="white-space: normal; margin: 0;">(a) LIBERO 上的成功率</figcaption></figure>
  <figure style="min-width: 0; height: auto; justify-content: flex-start; margin: 0;"><img src="/images/blog/pion/vlaadapter_training.png" alt="Object training curve" style="width: 100%; height: auto; max-height: none; max-width: 100%; display: block; margin: 0;" /><figcaption style="white-space: normal; margin: 0;">(b) Object 上的成功率 vs 训练步数</figcaption></figure>
</div>
  <p class="fig-caption">图 5. AdamW、Muon、Pion 用于 VLA Adapter on LIBERO。(a) LIBERO Object、Spatial、Goal、Long 四个子集上的成功率，每个子集采用固定的训练预算（Object 1,500 步，其余 15,000 步）。(b) LIBERO Object 上的成功率 vs 训练步数。</p>

  <p><a href="#fig-5-zh">图 5</a>(a) 表明，Pion 在每个子集上都全面优于 Muon 和 AdamW。<a href="#fig-5-zh">图 5</a>(b) 进一步给出 LIBERO Object 上的训练曲线：Pion 在 500 步即达到 95.4% 成功率，并在 1,500 步时饱和至 100%；AdamW 则需要明显更多的步数才能逼近。这说明谱高通大幅降低了到达高成功率所需的训练成本。</p>

  <p>在 VLANeXt（flow matching）上，Pion 不仅在 LIBERO 上取得最佳成功率，在更具挑战性的 LIBERO Plus 上也能继续保持优势，尤其是 language（\(+9\) 分）、noise（\(+6\) 分）、robot（\(+6\) 分）等几项扰动；详见 <a href="#tab-1-zh">表 1</a>。这恰好印证了我们之前的判断：均匀白化会过度放大那些无法泛化的噪声方向。</p>

  <div id="tab-1-zh" class="results-table">

    <table>
      <thead>
        <tr>
          <th style="text-align: left">优化器</th>
          <th style="text-align: center">LIBERO</th>
          <th style="text-align: center">LIBERO Plus</th>
          <th style="text-align: center">Background</th>
          <th style="text-align: center">Camera</th>
          <th style="text-align: center">Language</th>
          <th style="text-align: center">Layout</th>
          <th style="text-align: center">Light</th>
          <th style="text-align: center">Noise</th>
          <th style="text-align: center">Robot</th>
        </tr>
      </thead>
      <tbody>
        <tr>
          <td style="text-align: left">AdamW</td>
          <td style="text-align: center">79.45</td>
          <td style="text-align: center">64.57</td>
          <td style="text-align: center">68.97</td>
          <td style="text-align: center">70.38</td>
          <td style="text-align: center">54.50</td>
          <td style="text-align: center">61.80</td>
          <td style="text-align: center">76.35</td>
          <td style="text-align: center">66.37</td>
          <td style="text-align: center">47.04</td>
        </tr>
        <tr>
          <td style="text-align: left">Muon</td>
          <td style="text-align: center">93.65</td>
          <td style="text-align: center">72.34</td>
          <td style="text-align: center">82.72</td>
          <td style="text-align: center">68.00</td>
          <td style="text-align: center">77.53</td>
          <td style="text-align: center">76.21</td>
          <td style="text-align: center">86.17</td>
          <td style="text-align: center">69.98</td>
          <td style="text-align: center">57.36</td>
        </tr>
        <tr>
          <td style="text-align: left"><strong>Pion (Ours)</strong></td>
          <td style="text-align: center"><strong>96.35</strong></td>
          <td style="text-align: center"><strong>75.93</strong></td>
          <td style="text-align: center"><strong>84.53</strong></td>
          <td style="text-align: center"><strong>70.88</strong></td>
          <td style="text-align: center"><strong>86.93</strong></td>
          <td style="text-align: center"><strong>76.71</strong></td>
          <td style="text-align: center"><strong>90.67</strong></td>
          <td style="text-align: center"><strong>76.09</strong></td>
          <td style="text-align: center"><strong>63.18</strong></td>
        </tr>
      </tbody>
    </table>

  </div>
  <p class="fig-caption">表 1. AdamW、Muon、Pion 用于 VLANeXt on LIBERO 与 LIBERO Plus。每列最优用<strong>粗体</strong>。</p>

  <p>为了把 LIBERO Plus 上的差距更直观地展示出来，我们在同一个 LIBERO Plus episode 上，让三种优化器各自训练得到的 VLANeXt 策略各 rollout 一次。AdamW 与 Muon 在抓取或放置阶段失败，而 Pion 顺利完成任务。</p>

  <div id="video-1-zh" class="fig-grid" style="grid-template-columns: repeat(3, 1fr);">
  <figure><video src="/videos/blog/pion/ep1373_AdamW.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(a) AdamW</figcaption></figure>
  <figure><video src="/videos/blog/pion/ep1373_Muon.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(b) Muon</figcaption></figure>
  <figure><video src="/videos/blog/pion/ep1373_Pion.mp4" autoplay="" loop="" muted="" playsinline=""></video><figcaption>(c) Pion (Ours)</figcaption></figure>
</div>
  <p class="fig-caption">视频 1. LIBERO Plus 同一个 episode（ep1373）在 AdamW、Muon、Pion 三种优化器训练得到的 VLANeXt 策略下的 rollout 轨迹。</p>

  <h3 id="rlvr-2">RLVR</h3>

  <p>在全部 8 个 RLVR setting 上（GRPO/GMPO × Qwen3 1.7B/4B × MATH/GSM8K，见 <a href="#fig-6-zh">图 6</a>），Muon 无一例外地崩溃至接近零的准确率；Pion 不仅恢复出有意义的训练信号，收敛速度也快于 AdamW。</p>

  <div id="fig-6-zh" class="fig-grid" style="grid-template-columns: repeat(4, 1fr);">
  <figure><img src="/images/blog/pion/rl_val_core_grpo_math3-5_qwen3_1.7b.png" alt="" /><figcaption>(a) GRPO, 1.7B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_math3-5_qwen3_4b.png" alt="" /><figcaption>(b) GRPO, 4B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_gsm8k_qwen3_1.7b.png" alt="" /><figcaption>(c) GRPO, 1.7B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_grpo_gsm8k_qwen3_4b.png" alt="" /><figcaption>(d) GRPO, 4B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_math3-5_qwen3_1.7b.png" alt="" /><figcaption>(e) GMPO, 1.7B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_math3-5_qwen3_4b.png" alt="" /><figcaption>(f) GMPO, 4B, MATH</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_gsm8k_qwen3_1.7b.png" alt="" /><figcaption>(g) GMPO, 1.7B, GSM8K</figcaption></figure>
  <figure><img src="/images/blog/pion/rl_val_core_gmpo_gsm8k_qwen3_4b.png" alt="" /><figcaption>(h) GMPO, 4B, GSM8K</figcaption></figure>
</div>
  <p class="fig-caption">图 6. RLVR 上 AdamW、Muon、Pion 的验证准确率 vs 训练步：8 个 setting（两种算法 × 两种模型规模 × 两个 benchmark）。</p>

  <p><strong>反向消融：方向才是关键。</strong> 为确认增益的确来自”高通”这一方向，我们构造了 <strong>Low-pass Muon (LPMuon)</strong>：它与 Pion 共享 NS 结构与每步开销，但将滤波方向反转为低通。结果 LPMuon 完全无法训练，准确率始终停留在初始 checkpoint 水平，见 <a href="#fig-7-zh">图 7</a>。</p>

  <div id="fig-7-zh" class="fig-grid wrap" style="grid-template-columns: repeat(2, 1fr);">
  <figure><img src="/images/blog/pion/pion0_muon_lowrankmuon.png" alt="Low pass profile" /><figcaption>(a) 低通标量映射</figcaption></figure>
  <figure><img src="/images/blog/pion/mhlpmuon.png" alt="GSM8K accuracy" /><figcaption>(b) GSM8K 准确率</figcaption></figure>
</div>
  <p class="fig-caption">图 7. (a) LPMuon 的标量映射 \(f(\sigma)\)。(b) AdamW、Pion、LPMuon 的 GSM8K 准确率（Qwen3 1.7B，GRPO）。</p>

  <h2 id="bibtex-zh">BibTeX</h2>

  <pre class="bibtex-block"><code>@misc{fan2026rethinkingmuonpretrainingspectral,
      title={Rethinking Muon Beyond Pretraining: Spectral Failures and High-Pass Remedies for VLA and RLVR}, 
      author={Chongyu Fan and Gaowen Liu and Mingyi Hong and Ramana Rao Kompella and Sijia Liu},
      year={2026},
      eprint={2605.19282},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2605.19282}, 
}
</code></pre>

</div>]]></content><author><name>Chongyu Fan</name></author><category term="optimizer" /><category term="vla" /><category term="rlvr" /><summary type="html"><![CDATA[Muon orthogonalizes the momentum matrix and pushes every singular value to one. This works beautifully for LLM pretraining, which is essentially next token classification on text via supervised learning. But what happens when we move along three orthogonal axes: a different modality, a different loss, or a different learning paradigm? Pion is a drop in replacement for Muon's Newton Schulz iteration that fixes the spectral mismatch we observe along all three axes.]]></summary></entry></feed>